

The Frontier Inference Cloud for Agents
San Francisco, CA
Joined April 2022
- Tweets599
- Following148
- Followers601
- Likes165





Pinned Tweet
A matching prefix doesn't always mean reusable state.
As AI agents tackle longer, multi-step tasks, modern LLM architectures are changing how inference works.
Explore how MLA, hybrid architectures, and smarter caching are reshaping inference for agentic workloads. 🚀
🔗 friendli.ai/blog/llm-archite…

Friendli Inference vs. vLLM on the same 4× B200 GPUs (agentic GLM-5.3-Flash):
→ 2.1× throughput at 100 tok/s per request (~53% lower cost per token)
→ 3.1× faster generation at vLLM’s peak throughput
Full benchmark 👇
friendli.ai/blog/more-tokens…

Open-weight models are becoming a serious part of production AI.
@TheFuturumGroup's latest survey found
- 42% of surveyed enterprises use open-weight models in production, up from 31% in July.
- Gemma is used by 55% of production respondents, with low-complexity workloads accounting for a growing share of open-model usage.
While many enterprises run open-weight models on their own infrastructure, self-hosting comes with significant operational costs.
They also found
- 46% of production respondents use self-managed cloud infrastructure and 42% run models on-premises.
- Yet 50% cite self-hosting costs as a barrier to adoption.
This highlights an important opportunity for managed inference providers to make open models easier and more cost-effective to run in production.
futurumgroup.com/insights/en…

For teams looking to avoid the overhead of self-hosting, managed inference can be a practical alternative.
For example, Gemma 4 31B is available on FriendliAI at just $0.14 per 1M input tokens and $0.40 per 1M output tokens, with no GPU infrastructure to manage.
friendli.ai/models/google/ge…

friendliai retweeted

여러분, 안녕하세요! 🇰🇷
We are days away from our first trip to Seoul!
Come meet us and @friendliai on Nov 5th.
We would love to see you there!
Register below ⬇️
luma.com/ollama-friendliai-m…

A faster model doesn't always mean a faster coding agent.
AI coding performance depends on 4 layers:
🤖 Agents
🧠 Models
⚡ Inference
🖥️ GPUs
The real goal? Better task success, faster completion, and lower cost per task.
Explore the full stack 👇
friendli.ai/blog/ai-coding-a…

🌟 Special Guest Speaker: @MiniMax_AI Joins Us in Seoul!
We're excited to have Ethan Wei, Global Business Lead Solution Architect at MiniMax, as a special guest speaker at the Ollama × FriendliAI Seoul Meetup on November 5!
With extensive experience in cloud infrastructure and AI deployment, Ethan has led cloud and AI initiatives at Alibaba Cloud International and ByteDance. Since joining MiniMax in 2024, he has spearheaded the deployment of large-scale AI models and helped leading AI-native applications worldwide bring next-generation AI experiences to life.
At MiniMax Open Platform, he drives end-to-end technical architecture for large-scale AI implementations, bringing hands-on expertise in turning frontier AI capabilities into real-world applications.
🎤 Session: Inside M3.1-Flash: Frontier Capabilities for Devs
What does it take to build powerful, production-ready AI agents with frontier open models?
Ethan will take us inside MiniMax M3.1-Flash, exploring how three frontier capabilities come together in a single open-weight model:
🔹 1M-token context window for efficient long-context reasoning
🔹 Advanced coding and agentic performance for real-world software development
🔹 Native multimodality for next-generation AI applications
He'll also dive into the sparse-attention architecture powering M3.1-Flash, how it enables efficient long-context reasoning, and what it takes to build long-horizon AI agents ready for enterprise-scale deployment.
Join us in Seoul to hear directly from the frontier model labs pushing the boundaries of open AI!
📍 Seoul, South Korea
📅 November 5, 2026
🔗 Save your spot: luma.com/ollama-friendliai-m…

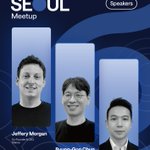
🎤 Meet the speakers joining us for the Ollama × FriendliAI Seoul Meetup!
On November 5, speakers from @ollama, @friendliai, and @MiniMax_AI are coming together in Seoul to share insights on building production agents with open models.
🔹 @jmorgan | CEO, Ollama
🔹 @bgchun | CEO, FriendliAI
🔹 Ethan Wei | Global Business Lead Solution Architect, MiniMax
Building an AI agent or LLM application with open models—or planning to? Join us to explore real-world development and production challenges, bring your questions to the open Q&A, and connect with the teams and fellow developers.
📅 November 5, 2026
📍 Seoul, South Korea
👉 Register: luma.com/ollama-friendliai-m…
#Ollama #FriendliAI #MiniMax #OpenModels #AIAgents

Not every workload needs a frontier-sized model.
Hugging Face's Carbon-X shows what domain-specialized open models can achieve.
A 14B model approaching frontier performance on specific DNA benchmarks, while offering a path to much lower inference costs and private deployment.
This is another important dimension of open-weight AI.
reddit.com/r/LocalLLaMA/comm…

Another strong result for the open-weight ecosystem.
Kimi K3.1 Pro scored 55 on Artificial Analysis's Intelligence Index, just 3 points behind the leading proprietary model.
What's notable is that this comes from an independent evaluation across multiple capabilities, not just a cherry-picked benchmark.
Looking forward to the weights release!

Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on Kimi.ai, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: platform.kimi.ai
🔗 Tech blog: kimi.ai/blog/kimi-k3-1-pro

Dynamic sparse attention reads fewer tokens per query. So why doesn’t the KV cache necessarily shrink to match?
Sliding-window attention only looks at recent tokens. Once a token falls outside the window, that layer no longer needs its KV state to continue the sequence, so the runtime can release it.
Dynamic sparse attention works differently. Each query selects which tokens to attend to from across the history. A token skipped by this query may be exactly what the next one needs.
So the runtime may still need to keep the full KV history, even though each step reads only a subset. And selecting positions and gathering noncontiguous KV entries adds its own cost.
Fewer attention reads ≠ a smaller cache. For long-context agents, compute and memory are two different budgets.
Our deep dive covers what this, and hybrid models like Kimi K3, mean for prefix reuse, caching, and speculative decoding: friendli.ai/blog/llm-archite…
Ultra-fast inference ⚡ open weights 🤗 food and drinks 🍻
An evening at the FriendliAI SF office, Wed Nov 18 6–8pm — one block
from Moscone, during Ignite week 📍
RSVP: luma.com/cch7p7pw

🚀 30% lower LLM costs. 25% faster responses.
By moving from a closed model to GLM on FriendliAI, Liner Scholar achieved both in an online A/B test.
Better economics. Faster inference. Powered by open models.
Read the story 👇
🔗 friendli.ai/customers/liner

Interesting trend from @vercel AI Gateway:
Open-weight models account for 71.5% of token usage, but only 23% of total spending.
That's a lot of inference volume at a relatively low cost.
While this reflects Vercel's workloads rather than the entire AI market, it's a compelling signal of how cost-efficient open-weight models are becoming for real-world applications.
vercel.com/blog/ai-gateway-p…


FriendliAI supports @NVIDIAAI Nemotron 3.5 Embed 1B, Embed 8B, and Rerank 8Btriever from Day-0.
#agentknowledgefoundation
Nemotron 3.5 Embed (1B & 8B) makes text and visual content searchable in one embedding space, and ranks #1 across Q2D-Web, MMTEB, ViDoRe, and RTEB, and more. Rerank 8B puts the strongest evidence first and ranks #1 on ViDoRe v3 Rerank.
Better evidence, better agents. Now on Friendli Dedicated Endpoints.
👉 Get started: friendli.ai/models/nemotron
🤓 Blog: friendli.ai/blog/nvidia-nemo…
🚀 More Models: friendli.ai/models

🎃 Just in time for Halloween, what's better than a classic "whodunit"?
Hosted by @aivalleyio, FriendliAI will be participating in a truly horrific DevTools murder mystery in SF entitled "Who Killed the Build?" 🗡️ Won't you join us?
luma.com/aivalley-lqjv

friendliai retweeted

MiniMax M3.1 Flash: Space Performance + Bunny Speed
🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash.
💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed.
API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens.
Model weights will arrive on Oct 23.
API: platform.minimax.io
M Plan: minimax.io/m-plan
MiniMax Code for desktop: agent.minimax.io/download
