πŸ§ͺ Open Source Team that maintains LMCache and Production Stack πŸ€– Democratizing AI by providing efficient LLM serving for ALL

Github, Online
Joined September 2024
When is it better to fetch a KV cache than to recompute it? New on the LMCache blog: an Internet for the KV cache, by Siddhant Ray, adapted from his arXiv paper with Nick Feamster and Junchen Jiang of the University of Chicago. One example: DeepSeek-V4-Pro, about 100,000 tokens, about 1 GB of compressed KV cache. Sending it over a 10 Gbps link takes about 0.8 s and $0.09. Recomputing it on AWS 8Γ—B200 takes about 15 s and $0.47. Under the post’s assumptions, transfer is about 19Γ— faster and 5.2Γ— cheaper ⚑ (AWS prices are examples only.) blog.lmcache.ai/en/2026/10/2…
2
1
4
72
What should we ask Dongjoo Seo about KV cache system deployment? πŸ’¬ Dongjoo Seo of Samsung speaks at 4:30 PM today at the LMCache hands-on workshop: "What we should consider for KV Cache system deployment." Reply with one question, and we will bring a few into the room. The workshop starts at 1:30 PM Pacific at Samsung, 3655 N First St, San Jose. It is free, and you can still register: ⏰ na2.hubs.ly/H08rNRd0
1
1
159
Today: hands-on LMCache in San Jose. ⏰ Doors open at 1:30 PM Pacific at Samsung, 3655 N First St. Bring a laptop (recommended). Parking is available, and signs lead you to check-in. πŸ“ Four hours: an introduction to LMCache, a 45-minute deep dive with mini-lmcache, two technical sessions, and a reception until 5:30 PM. πŸ› οΈ Registration is free: na2.hubs.ly/H08p3x20
129
Today is the last day of PyTorch Conference. Tomorrow, 22 October, stay in San Jose for the LMCache hands-on workshop: 1:30 to 5:30 PM Pacific, at Samsung, 3655 N First St. πŸ› οΈ Today is the last full day to register. It is free. 🎟️ Know someone at the conference who works on LLM inference? Send this to them before they leave San Jose. πŸ” na2.hubs.ly/H08k6110
1
136
Tomorrow at 1:30 PM, doors open at Samsung, 3655 N First St, San Jose. πŸ“ Bring a laptop; it is recommended for the hands-on part. Parking is available, and signs lead you to check-in at the event location. Refreshments are provided. Setup help starts at 1:30 PM, so arrive early if you want someone to check your environment. πŸ› οΈ The LMCache hands-on workshop runs until 5:30 PM Pacific. It is free, and registration is required. ⏰ na2.hubs.ly/H08k60h0
1
1
2
192
What is the hardest KV cache question in your stack right now? 🧠 Bring it to the LMCache booth at PyTorch Conference, today or tomorrow, at the San Jose Convention Center. If it needs more time, bring it to our hands-on workshop on Thursday, and test your ideas against a live LMCache environment. Thursday 22 October, 1:30 to 5:30 PM Pacific, at Samsung, 3655 N First St, San Jose. Free. πŸ“ na2.hubs.ly/H08k5_-0
1
3
215
Here's a question from our ecosystem of LMCache integrators: When you run several vLLM processes, does each one keep LMCache inside its own process, or can all of them share one LMCache service? Here's one way: In multi-process mode, you start lmcache server with CPU memory as L1 and FlashBlade over GPUDirect Storage (GDS) as L2. Each vLLM process connects to the shared server through LMCacheMPConnector. Josh Lay and Jean-Baptiste Thomas published the full server and vLLM configuration, pinned to lmcache==0.5.3 and vllm==0.24.0, on the Everpure blog: na2.hubs.ly/H08nWCR0 #LMCache #KVCache
1
3
245
PyTorch Conference day 1 starts this morning at the San Jose Convention Center, and LMCache has a booth. πŸ“ Find us to talk about KV cache management, and register at the booth for our hands-on workshop. The workshop is in 2 days: Thursday 22 October, 1:30 to 5:30 PM Pacific, at Samsung, 3655 N First St, San Jose. Free. ⏰ What should we show you at the booth? πŸ’¬ na2.hubs.ly/H08k5_K0
130
Tag one teammate who should spend Thursday afternoon with LMCache. πŸ” 22 October, 1:30 to 5:30 PM Pacific, at Samsung, 3655 N First St, San Jose: a live LMCache environment, a hands-on deep dive with mini-lmcache, engineering sessions, and a reception. A laptop is recommended. 🀝 It is free. Each of you registers here: na2.hubs.ly/H08k5PT0
2
164
Going to PyTorch Conference this week? Find the LMCache booth at the San Jose Convention Center on 20 and 21 October. πŸ“ You can register at the booth for Thursday's LMCache hands-on workshop. It is the day after the conference ends: 22 October, 1:30 to 5:30 PM Pacific, at Samsung, 3655 N First St, San Jose. Free. 🎟️ Ask us about KV cache management while you are there. Or register now: na2.hubs.ly/H08k5Pw0
1
122
In 3 days, LMCache runs a hands-on workshop in San Jose. Is it for you? 🧠 It is for engineers and researchers who work on KV cache management and LLM efficiency. If you run LLM inference and care about time-to-first-token (TTFT) and throughput, the afternoon is built for you. Thursday 22 October, 1:30 to 5:30 PM Pacific, at Samsung, 3655 N First St, San Jose. Free, registration required. ⏰ na2.hubs.ly/H08k5M40
1
159
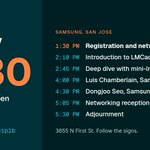
The second half of the LMCache workshop on Thursday 22 October has two Samsung speakers, one after the other. 🀝 4:00 PM: Luis Chamberlain (mcgrof) on asymmetric quantization, dma-buf with io_uring, and learned prefix caching. 4:30 PM: Dongjoo Seo, "What we should consider for KV Cache system deployment." 5:00 PM: closing remarks, then a reception until 5:30 PM. Before that: the Introduction to LMCache and a 45-minute hands-on deep dive with mini-lmcache. πŸ› οΈ Free, registration required: na2.hubs.ly/H08rNNB0
1
159
Which is harder for your stack: long context, or many users at once? πŸ’¬ Reply with one word. In 4 days you can bring that answer to a live LMCache environment, and to a room of people who run inference. The LMCache hands-on workshop is on Thursday 22 October, 1:30 to 5:30 PM Pacific, at Samsung, 3655 N First St, San Jose. Free, registration required. ⏰ na2.hubs.ly/H08k5K50
1
125
The agenda for Thursday 22 October has three blocks for people: networking at 1:30 PM, a networking break at 3:30 PM, and a reception from 5:05 PM until 5:30 PM. 🀝 Bring a problem you have not solved in your own stack. Someone at Samsung in San Jose may run a similar setup. Which inference problem would you most like to discuss with peers? πŸ’¬ The LMCache hands-on workshop is free, and refreshments are provided. πŸ“ Registration is required: na2.hubs.ly/H08k5JR0
3
256
45 minutes, one live deployment, and your laptop: that is the deep dive Samuel Shen of Tensormesh leads at 2:45 PM on Thursday 22 October. πŸ› οΈ First, the mechanics of a public server deployment. Then hands-on work against the mini-lmcache API endpoints to benchmark and optimize KV cache management. The test environment stays open after the session. It is part of the free LMCache workshop, 1:30 to 5:30 PM Pacific, at Samsung, 3655 N First St, San Jose. πŸ“ Registration is required: na2.hubs.ly/H08p4vJ0
1
120
Never run LMCache before? Start at 2:10 PM on Thursday 22 October. 🧠 Karsten Wade gives the Introduction to LMCache: what the KV cache layer does, and where it is useful. Its PyPI summary says it in one line: "A LLM serving engine extension to reduce TTFT and increase throughput, especially under long-context scenarios." TTFT means time-to-first-token. Then you try it yourself in the hands-on deep dive. 1:30 to 5:30 PM Pacific, Samsung, 3655 N First St, San Jose. Free. πŸ“ na2.hubs.ly/H08k5Dt0
119
Open Source AI Week starts today in the Bay Area and runs to 25 October. πŸ“… If you come for PyTorch Conference at the San Jose Convention Center on 20 and 21 October, stay one more day. On Thursday 22 October, the LMCache hands-on workshop runs 1:30 to 5:30 PM Pacific at Samsung, 3655 N First St, San Jose. πŸ“ Four hours with a live LMCache environment, engineering sessions, and a reception. Free, registration required: na2.hubs.ly/H08k5yg0
1
2
182
New speaker for the LMCache workshop: Luis Chamberlain (mcgrof) of Samsung takes the 4:00 PM session on Thursday 22 October. 🧠 His topics: asymmetric quantization, dma-buf support with io_uring, and learned prefix caching with Cartridges and beyond. Dongjoo Seo of Samsung speaks next, at 4:30 PM. 1:30 to 5:30 PM Pacific, Samsung, 3655 N First St, San Jose. Free. πŸ“ na2.hubs.ly/H08p3xz0
1
141
After the workshop on Thursday 22 October, the mini-lmcache test environment stays open for your own experiments. πŸ› οΈ So what would you test first? A long shared prompt? A document that many requests read again? Reply with one line. πŸ’¬ The hands-on deep dive is part of a free afternoon, 1:30 to 5:30 PM Pacific, at Samsung, 3655 N First St, San Jose. Registration is required: na2.hubs.ly/H08k5xM0
1
1
1
129
Ecosystem check-in from our community of LMCache integrators: At 128K tokens of context, time to first token went from 33.5 s with no cache to 1.9 s with LMCache storing the KV cache on FlashBlade over GPUDirect Storage (GDS). Josh Lay and Jean-Baptiste Thomas ran the test on NVIDIA L40S with openai/gpt-oss-20b, vllm==0.24.0, and lmcache==0.5.3. The baseline is a cold prefill with no cache. How do you connect vLLM, LMCache, and FlashBlade to get this result? Their post on the Everpure blog has the configs: na2.hubs.ly/H08nWlC0 #LMCache #KVCache
1
1
4
254