

Accelerate inference, model shaping, and pre-training on a research-optimized platform.
San Francisco, CA
Joined November 2022
- Tweets3.3K
- Following279
- Followers66.3K
- Likes2.5K





Pinned Tweet
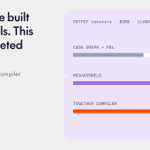
Two weeks ago we announced Together Compiler: agents that tune inference to your model, chip, and traffic, for up to 2.6x more throughput.
Today, we’re sharing the journey behind it: the experiments that challenged our assumptions of megakernels, the surprising strengths of Torch Compile, and the lessons that shaped our development of a next-generation system for inference optimization.
Shout out to @dylan__lim @reyna_abhyankar @simran_s_arora and the team!
Read more: together.ai/blog/road-to-tog…

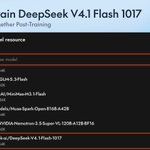
deepseek v4.1 flash 1017 is now available for post-training on together ai
run sft or rl with your own data, rewards + environments, and keep the training loop in your own python code
take v4.1 flash and shape it for your own coding and agentic work
together.ai/post-training

ALT Together Post-Training console showing the Create model resource dialog. The base model list has deepseek-ai/DeepSeek-V4.1-Flash-1017 highlighted. Title: Post-train DeepSeek V4.1 Flash 1017, now on Together Post-Training.
What does coaching basketball have to do with RL? 🏀
Zach Wentz answers it at Open by Design with @nvidia and @reflection_ai.
Watch the full panel: youtube.com/watch?v=-4ibZIfj…
Check out our upcoming events: luma.com/together-ai

3
675
What It Takes to Build a Frontier Local Coding Model : A conversation with Ricursive Intelligence and Together AI xitter.gq/i/broadcasts/2aWQRdMnn…

Starting soon: how @RicursiveAI built a small coding model from scratch, live with @DZhang50 and @zainhas .
Join → luma.com/together-1kx8


2
9
2,045
For languages off-the-shelf speech models underserve, @wonderful_ai, the AI OS for the enterprise, builds its own voice models.
Running on @NVIDIA accelerated computing, through Together AI:
→ 274ms time to first sentence
→ 100% uptime
→ Zero human interaction to scale, ship new weights, or run blue/green tests
together.ai/customers/wonder…

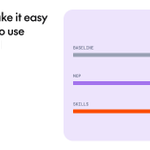
Here's how we do agent evals at Together AI:
→ Define ~10 representative tasks
→ Run agents (Claude Code) in sandboxes
→ Test 3 configs (baseline, MCP, skills) for each task
→ Analyze trajectories and improve docs + APIs
Agent task completion improved from 67% to 96%!


coding agents resend the whole conversation on every turn. prefix caching keeps long sessions fast, but only if the harness and the inference engine both do their part.
@zainhas from Together and @parthsareen from @ollama wrote down what each side needs to get right.
together.ai/blog/making-open…

Together AI retweeted

Last Year We Built Megakernels. This Year We Deleted Them.
One year ago, we helped introduce some of the first AI megakernels to the world. Since then, we’ve enjoyed seeing their wide adoption from friends and researchers. However, while whole model megakernels are a helpful abstraction, we’ve found that they overcomplicate and are not always an ideal optimization target.
Below, we discuss our journey to understand and push past these limitations. We start with a deep dive into two contrasting paradigms of ML optimization – Torch Compile and Megakernels

Two weeks ago we announced Together Compiler: agents that tune inference to your model, chip, and traffic, for up to 2.6x more throughput.
Today, we’re sharing the journey behind it: the experiments that challenged our assumptions of megakernels, the surprising strengths of Torch Compile, and the lessons that shaped our development of a next-generation system for inference optimization.
Shout out to @dylan__lim @reyna_abhyankar @simran_s_arora and the team!
Read more: together.ai/blog/road-to-tog…
Together AI retweeted

in a world where agent experience (AX) >> developer experience (DX) you need to make sure agents can use your platform
this is how we use evals to make sure agents can use the Together platform🔥

How we do agent evals at Together:
→ Define ~10 representative tasks
→ Run agents (Claude Code) in sandboxes
→ Test 3 configs (baseline, MCP, skills) for each task
→ Analyze trajectories and improve docs + APIs
Agent task completion improved from 67% to 96%! More below:

Read more about how we do agent evals here:
together.ai/blog/how-we-do-a…

3
734
closed → open migration works best as an iterative rollout
discover → evaluate → adapt → decide → production
evaluate on real traffic, improve what falls short, then canary the strongest candidate before moving more traffic

How do you build a small coding model from scratch?
@RicursiveAI 's Dan Zhang breaks down the architecture and decisions behind Ripple-65B Preview with @zainhas: dense over MoE, the ablations that held up (and didn’t), and what happened inside the RL runs.
Tuesday, Nov 17 . 11 A.M. PT / 2 P.M. ET
Register: luma.com/together-1kx8
6
1,229
Heading to @AWSreInvent ? Make plans for Tuesday night. Join Together AI + Coder at SUSHISAMBA for food, drinks, and conversation.
📍SUSHISAMBA at the Venetian, Las Vegas
🗓️ Tuesday, December 1
🕡 6:30-8:30 p.m. PST


inkling 2 small from thinking machines is now live on together ai
the multimodal moe is built for coding, long-horizon agentic work + vision, with 594b total parameters, 17b active + up to 1m context
try it now: together.ai/models/inkling-2…

poetiq uses together post-training to launch complex rl research workloads quickly, while keeping complete algorithmic control over their setup
fast to launch, with the training loop still fully theirs
together.ai/post-training
