

Research Scientist @SkildAI. PhD in RL, The University of Edinburgh. Interested in intelligence through trial-and-error in the Era of Experience.
San Francisco, CA
Joined September 2021
- Tweets101
- Following439
- Followers156
- Likes2.3K




Pinned Tweet
Introducing Terra Nova, a new comprehensive challenge environment for RL research inspired by Civilization V.
The humanoids just want to (self) play.

We trained a robot to play football.
How? Self-play for 140 years in a virtual World Cup.
Meet the #Messinator:

Some exciting new results with in-context learning, allowing for very long-horizon behaviors.
The team hit it out of the park with this one!
Feels like a good time to announce that I've joined Skild as a Research Scientist.
Looking forward to continuing the push for RL in the real world.
Music credit:
"A Brighter Future" by All Good Folks: uppbeat.io/t/all-good-folks/…
"Go Ahead" by Gerald Olivieri: uppbeat.io/t/gerald-olivieri…
The ability to feel will be crucial for real-world robots.
Our new NeurIPS paper studies how tactile sensors affect downstream RL control. With the right representations, we can do dexterous tasks like Baoding ball rotation without seeing anything at all (no pixels, just touch).

Excited to share our #NeurIPS2025 paper "Enhancing Tactile-based RL for Robotic Control"!
We show how incorporating self-supervision into tactile RL can lead to simulated superhuman dexterity🤏 By the way, this agent is fully blind.
Find out more: elle-miller.github.io/tactil…
🧵👇
I've not done a great job promoting my work during the PhD, so here's one from last year:
Given an interaction budget, what data should we collect online after pretraining an RL agent offline? We answered this question by planning to go out of distribution (PTGOOD).
We find that PTGOOD consistently produces the best-performing policies among a set of OtO and exploration algorithms across various continuous-control tasks and offline dataset qualities.

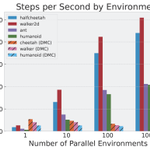
We also investigate the failure modes and complications of common exploration approaches in online RL, performance impacts of hyperparameter selection, perform comprehensive tuning of our baselines, and more.
Check out the paper here: arxiv.org/abs/2310.05723