

Command your own software factory.
San Francisco
Joined March 2025
- Tweets208
- Following32
- Followers1.3K
- Likes263


Pinned Tweet
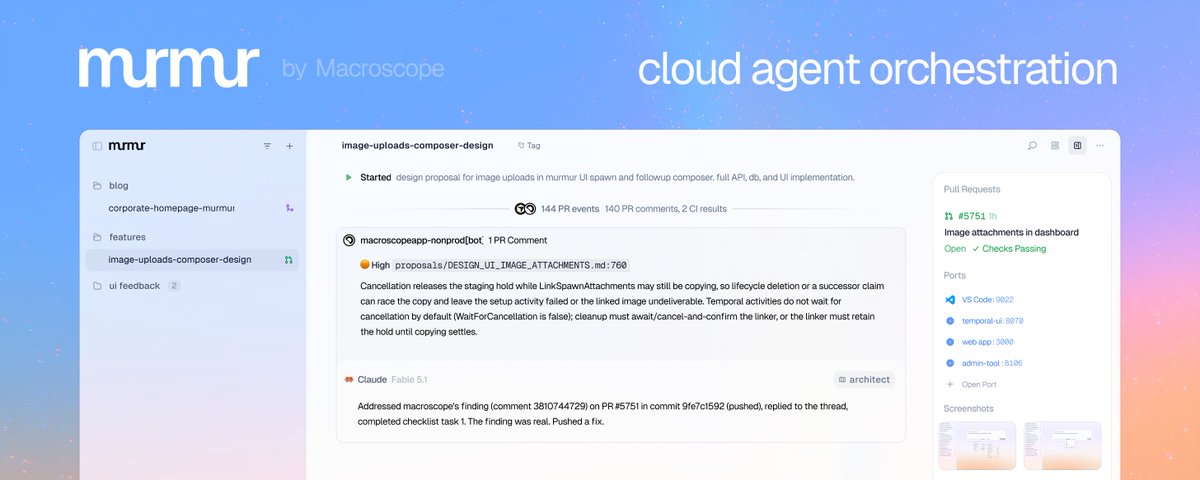
Today we are introducing Murmur, our cloud agent orchestration system.
Here's an early preview of Murmur:

1/ a few upgrades to approvability and check run agents this week.
approvability is a macroscope agent that decides whether a PR is safe to merge without a human, and approves it if so. it helps make code review less of a bottleneck for your eng team.
as of this week, when you resolve the last blocking comment on a PR, approvability automatically reruns. so a fixed PR gets approved right away, instead of sitting there waiting on a new commit or a manual rerun. this means faster approvals and faster merges.
2/ new: onlyApprove. list paths in approvability's front matter, and it will only consider approving PRs whose diff stays inside them. touch anything outside those paths and it won't approve.
so you can turn on auto-approval for the parts of your codebase you trust it with, without handing it the keys to everything.
3/ check run agents are agentic PR checks you write in plain markdown.
they now follow the same ignore rules as code review, so they skip test files, .json, or anything else you've told Macroscope to ignore. that means faster checks, simpler configs and much more cost efficiency.
if one of your agents does need to review something you've deliberately ignored, use the "include" param in its config.
Back for day 2 of ELC! Loved all the conversations yesterday and are excited for more today.
If you’re at the conference, come say hi :)

Yesterday's #SFTechWeek Clickety Clack Café, in photos 📷
Thanks for stopping by! And if your PR needs another shot, check out Macroscope: macroscope.com


PSA: free coffee and matcha at 500 Folsom St until 4:30pm 🍵
Grab a hot (or cold) fix before your next #SFTechWeek event. We'll be here (caffeinated).


Clickety Clack Café is live!☕️
Coffee & code review on Macroscope.
Register for location: partiful.com/e/1XFyBiTbjMeIm…
#SFTechWeek


Macroscope retweeted
@Macroscope runs its go-to-market on a business world model built with Lightfield.
They ingest customer touchpoints across marketing interactions, product use, and sales into a single platform. This gives agents full context on entire customer lifecycle. Agentic workflows that used to take months to build in other systems can be designed in hours using natural language.
Read how Macroscope is building its GTM system.
lightfield.app/customers/mac…
Tomorrow: free coffee for everyone at #SFTechWeek.
Clickety Clack Café, 1:30 to 4:30pm. RSVP for the location.
Coffee & Code review on us.
partiful.com/e/1XFyBiTbjMeIm…

Macroscope retweeted
@cars24india is one of India's largest auto-tech companies: 300M+ users, $1B+ in revenue, 400 engineers.
with Macroscope, they saw up to 3x more code reaching production in 3 months. 🧵

🥉 GPT 6.1 Sol debuts at #3 on our code review leaderboard.
It comes below GPT 6 Sol because recall is lower, but it leaves 30% fewer comments with very high precision.
It also slightly beats workhorse Astra at a seventh of the price!
See full results: macroscope.com/benchmark

We're opening a coffee cart for #SFTechWeek ☕
Free coffee and matcha for everyone shipping code
Tue Oct 6, 1:30 to 4:30pm, downtown SF. RSVP for location drop.
partiful.com/e/1XFyBiTbjMeIm…

Building on the release of MacroscopeBench, we’ve been researching post-training our own models at Macroscope, leveraging training infrastructure from @FireworksAI_HQ .
Our co-founder, @Rob_Bishop, and Vivek Chauhan, product lead for training at Fireworks, will be sharing learnings from the collaboration on Sep 29, 11am PT.

As a reminder: Macroscope never trains on customer data. Both MacroscopeBench and our model-training datasets are built from real bugs in open-source repositories. Learn more about our methodology: macroscope.com/blog/macrosco…

Register here: fireworks.ai/event/build-lik…

GPT-6 Sol scored 80.3, #2 overall, behind only Claude Opus 5.5 max.
It is ahead of GPT-6 Astra at less than half Astra's cost.
Against GPT-5.6 Sol it matches the old model's best score at half the price
GPT-6 Luna, while ranking at #13 using max effort, still delivers great performance for extremely low prices. It reached 93% of GPT-6 Astra's score for about 1/60th of the cost! It holds a very respectable f1 score due to its very high precision (89.1%), second only to Astra
There are some new top models leading our code review benchmark.
🥇 Claude Opus 5.5 — 82.3 (f1 score)
🥈 GPT-6 Sol — 80.3
🥉 GPT-6 Astra — 78.0
See full results here: macroscope.com/benchmark

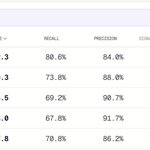
Claude Opus 5.5 at max effort takes #1 with impressive recall (80.6%) and precision (84%). The downside: cost and latency, being the most expensive model we’ve tested
xHigh effort level still delivers very strong performance, very similar to GPT 6 Sol max at half the latency.