

Empowering AI Evolution Ecosystem
Palo Alto, CA
Joined August 2024
- Tweets173
- Following78
- Followers339
- Likes218






2077AI papers at #CoRL2026 on Thursday, Nov 12: TouchScale and ENCORE, presented across three workshops.
🧤 TouchScale: 500 Hours of Human Vision and Touch for Visual-Tactile Learning
• Scaling H2R Workshop, poster session 10:30–11:00 AM CST
• Everything Beneath the Policy, poster session 10:35–11:05 AM CST, Hilton Austin, Salon E
500 hours of human vision and touch data from one wearable setup. TouchScale mid-training improved real-world robot success from 22.5% to 57.5% across four tasks.
🔗 touch-scale.github.io
💻 ENCORE: Few-Shot Agentic Discovery of Manipulation Strategies
• Workshop on Agentic Robotics, poster session 4:20–5:55 PM CST
A coding agent reads a few demonstrations, writes a policy program, and freezes it. 96.3% on LIBERO-PRO perturbation tasks vs. 89.3% for the strongest prior agentic system (same model).
🔗 yifank.github.io/encore
Come check out our works at the poster sessions!
What tells a simulator how hard a human grips?
Video shows where each finger stops. How far it closes, which sets grip force, goes unseen, so prior pipelines that rebuild demos from vision never get contact force.
TouchTwin, a CoRL 2026 late-breaking result built on TouchScale, adds it: selected recordings replayed in MuJoCo, with the glove's measured touch setting each finger's force.
On held-out recordings:
• A hand policy's grip force, in sim: 0.31× the recording when trained on observed pose, 0.99× on touch-grounded replays
• A contact predictor misses 13% of real contact frames when trained on touch-grounded replays, vs 32% on vision-based replays
Limits: policy tested in simulation only; mug task only; small test sets.
📍 Presented today at CoRL: Real2Sim2Real poster session, lunch break, Griffin (2nd floor), JW Marriott Austin.
A collaboration between Stanford, Texas A&M, Yale and 2077AI.
🔗 Project page: touchtwin.github.io
📄 Paper: touchtwin.github.io/paper/to…
Congrats to the TouchTwin team: Huiwen Han, Nuo Chen, @Ziyao_Zeng ,@EdisonLeeROC , @haohw_, Amir Hossein Rahmati, Xiaoning Qian, @Neutrino_l, @zhiwen_fan_

2
51
Proactive agents face a calibration problem: acting correctly is not enough if the intervention itself is poorly timed or unwarranted.
We introduce HALO, a human-grounded benchmark for evaluating proactive agents across everyday environments.
📄 arxiv.org/abs/2610.39086
🧵 (1/5)

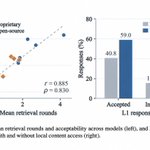
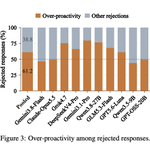
(5/5) HALO-8K contains 8,000 responses from 10 models, annotated by 20 experts for action level, acceptability, timing, intervention intensity, and rejection reasons.
The evaluation is designed to capture not only what an agent does, but whether it should have acted at all.
1
1
23
This project was led by @WenqiPei, in collaboration with 2077AI researchers Xinyu Wang, Jinrui Liu, Cynthia Zhuge, @ZoeSheng22, and @ZihanWang123, together with @TenghaoHuang45, under the guidance of @muhao_chen.
📄 Paper: arxiv.org/html/2610.39086v1
💻 Code & benchmark: github.com/CedricPei/HALO
4
117
ENCORE (Oral, NeurIPS 2026 Robot Learning Workshop; CoRL 2026 Agentic Robotics Workshop): a coding agent reads a few robot demos, writes a policy program, refines it, then freezes it.
96.3% on LIBERO-PRO, vs 89.3% for the best prior agent on the same model.
arxiv.org/abs/2609.37359
yifank.github.io/encore
3/4 96.3% on LIBERO-PRO vs 89.3% for the strongest prior agent on the same model. When the instruction leaves the goal unstated, no program written without demos succeeds in any of three independent runs.
1
14
4/4 The same loop runs on a real bimanual robot: 9/10 on cube handover and 9/10 on cup inversion, from 5 demos each.
📄Paper: arxiv.org/abs/2609.37359
💻Code: github.com/YIFANK/encore
🔗Page: yifank.github.io/encore

15

🙌 This work is built in collaboration with Berkeley RDI, alongside researchers from UC Santa Cruz, UC Santa Barbara, UW-Madison, MIT, the University of Toronto, Johns Hopkins, CMU, Purdue, and Texas A&M.
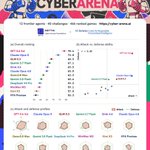
At 2077AI, we build open benchmarks that show both what frontier models can do and where they fall short. In that spirit, CyberArena’s engine, challenges and match replays are all open source.
1
94
Read more:
📄 Paper: arxiv.org/abs/2610.19005
🌐 Homepage: cyber-arena.ai
🤗 Leaderboard: huggingface.co/spaces/2077AI…
💻 GitHub: github.com/cyber-arena-ai/cy…

68