

Machine Learning Engineer | Keyboard Enthusiast | Ex - Mechanical Aerospace Robotics Engineer | Kaggler
United Kingdom
Joined November 2019
- Tweets417
- Following238
- Followers1.1K
- Likes899





Abed Merii 🎙️ retweeted

🚀 Big milestone: @marimo_io just crossed Jupyter notebook in GitHub stars
We reached 12000 stars in just over a year — people are clearly hungry for a better environment for working with data, and we have a lot more planned still.
Excited for the road ahead!

Abed Merii 🎙️ retweeted

Congrats to @AIatMeta on Llama 3 release!! 🎉
ai.meta.com/blog/meta-llama-…
Notes:
Releasing 8B and 70B (both base and finetuned) models, strong-performing in their model class (but we'll see when the rankings come in @ @lmsysorg :))
400B is still training, but already encroaching GPT-4 territory (e.g. 84.8 MMLU vs. 86.5 4Turbo).
Tokenizer: number of tokens was 4X'd from 32K (Llama 2) -> 128K (Llama 3). With more tokens you can compress sequences more in length, cites 15% fewer tokens, and see better downstream performance.
Architecture: no major changes from the Llama 2. In Llama 2 only the bigger models used Grouped Query Attention (GQA), but now all models do, including the smallest 8B model. This is a parameter sharing scheme for the keys/values in the Attention, which reduces the size of the KV cache during inference. This is a good, welcome, complexity reducing fix and optimization.
Sequence length: the maximum number of tokens in the context window was bumped up to 8192 from 4096 (Llama 2) and 2048 (Llama 1). This bump is welcome, but quite small w.r.t. modern standards (e.g. GPT-4 is 128K) and I think many people were hoping for more on this axis. May come as a finetune later (?).
Training data. Llama 2 was trained on 2 trillion tokens, Llama 3 was bumped to 15T training dataset, including a lot of attention that went to quality, 4X more code tokens, and 5% non-en tokens over 30 languages. (5% is fairly low w.r.t. non-en:en mix, so certainly this is a mostly English model, but it's quite nice that it is > 0).
Scaling laws. Very notably, 15T is a very very large dataset to train with for a model as "small" as 8B parameters, and this is not normally done and is new and very welcome. The Chinchilla "compute optimal" point for an 8B model would be train it for ~200B tokens. (if you were only interested to get the most "bang-for-the-buck" w.r.t. model performance at that size). So this is training ~75X beyond that point, which is unusual but personally, I think extremely welcome. Because we all get a very capable model that is very small, easy to work with and inference. Meta mentions that even at this point, the model doesn't seem to be "converging" in a standard sense. In other words, the LLMs we work with all the time are significantly undertrained by a factor of maybe 100-1000X or more, nowhere near their point of convergence. Actually, I really hope people carry forward the trend and start training and releasing even more long-trained, even smaller models.
Systems. Llama 3 is cited as trained with 16K GPUs at observed throughput of 400 TFLOPS. It's not mentioned but I'm assuming these are H100s at fp16, which clock in at 1,979 TFLOPS in NVIDIA marketing materials. But we all know their tiny asterisk (*with sparsity) is doing a lot of work, and really you want to divide this number by 2 to get the real TFLOPS of ~990. Why is sparsity counting as FLOPS? Anyway, focus Andrej. So 400/990 ~= 40% utilization, not too bad at all across that many GPUs! A lot of really solid engineering is required to get here at that scale.
TLDR: Super welcome, Llama 3 is a very capable looking model release from Meta. Sticking to fundamentals, spending a lot of quality time on solid systems and data work, exploring the limits of long-training models. Also very excited for the 400B model, which could be the first GPT-4 grade open source release. I think many people will ask for more context length.
Personal ask: I think I'm not alone to say that I'd also love much smaller models than 8B, for educational work, and for (unit) testing, and maybe for embedded applications etc. Ideally at ~100M and ~1B scale.
Talk to it at meta.ai
Integration with github.com/pytorch/torchtune
Abed Merii 🎙️ retweeted
# scheduling workloads to run on humans
Some computational workloads in human organizations are best "run on a CPU": take one single, highly competent person and assign them a task to complete in a single-threaded fashion, without synchronization. Usually the best fit when starting something new. Comparable to "building the skeleton" of a thing.
Other workloads are best run on a GPU: take a larger number of (possibly more junior) people and assign tasks in parallel: massively multi-threaded, requiring synchronization overhead. Usually a good fit for later stages of a project, or parts that naturally afford parallelism, comparable to "fleshing out" a thing when the skeleton is there.
There's some middle ground here - sometimes you can imagine a multi-threaded CPU execution of a small team collaborating.
A good manager will understand the computational geometry of the project at hand and know when to delegate parts of it on the CPU or on the GPU. One notable place where the analogy breaks down a bit is that the worst thing that can happen when you misallocate computer resources is that your program will run slower. But in human organizations it can be much worse - not just slower, but the result can be of lower quality overall, more brittle, more disorganized, less consistent, uglier.
The most common stumbling point here is trying to parallelize something that was supposed to run on the CPU. In the common tongue, this comes from the misunderstanding that something can go faster if you put more people on it, usually leading to outcomes where something is "designed by a committee" - not only is the thing actually slower, but the philosophy is inconsistent, the entropy is high, and the long-term outcomes much worse.
The opposite problem is more rare and usually looks like someone doing something repetitive, uninteresting or tedious, where they could really benefit from more help.
I think this is one accidental advantage of startups - they lack resources of large companies and run compute on powerful CPUs, winning in cases where that is the right thing to do. Larger companies, especially in cases where something is deemed of high strategic importance, will almost always reach for too much parallelism.
TLDR: Think about your project, its computational geometry, its inherent parallelism, and which parts are a best fit for a CPU or a GPU.
Abed Merii 🎙️ retweeted
Have you ever wanted to train LLMs in pure C without 245MB of PyTorch and 107MB of cPython? No? Well now you can! With llm.c:
github.com/karpathy/llm.c
To start, implements GPT-2 training on CPU/fp32 in only ~1,000 lines of clean code. It compiles and runs instantly, and exactly matches the PyTorch reference implementation.
I chose GPT-2 to start because it is the grand-daddy of LLMs, the first time the LLM stack was put together in a recognizably modern form, and with model weights available.

Abed Merii 🎙️ retweeted

What matters most when training a neural network is how well it generalizes to unseen data.
For neural networks, it turns out there's a simple principle that can allow you to understand model generalization. (1/18)
A thread ↓
Abed Merii 🎙️ retweeted

A true programmer never makes the same mistake twice. They make it more like half a dozen times.
Coding is hard & failing is human. Make room for your screw-ups.
Abed Merii 🎙️ retweeted
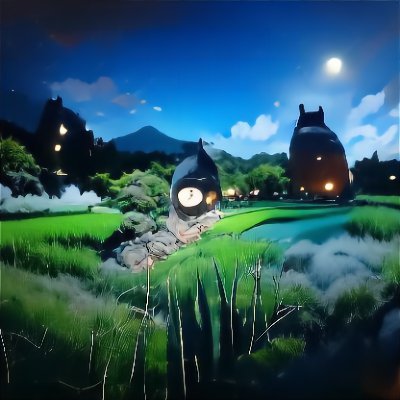
Physical Design using Differentiable Learned Simulators
abs: arxiv.org/abs/2202.00728
Abed Merii 🎙️ retweeted

I’ve recently struggled to understand Python concurrency:
- How threads & processes work on your OS vs Python
- The role of CPUs, hardware & the GIL
- Understanding beyond rules of thumb
After tons of research, I wrote this w/the answers plus more 👇🧵
python.hamel.dev/concurrency…


Abed Merii 🎙️ retweeted

Awesome service for working on Jupyter Notebooks collaboratively. My students are currently using it for their machine learning class projects; and it's also useful for me to check & comment. Really cool is the data management. No mounting required, it's just drag and drop:

We have some exciting news - Deepnote is now open for all! 🎉 A big thank you to everyone who was a part of our private beta and helped us shape Deepnote into the product it is today.
👉 No more waitlist, get started today at: deepnote.com

Abed Merii 🎙️ retweeted
Startup vs big company! xitter.gq/zerogravityhxp/status/… – at Westport, CT

Abed Merii 🎙️ retweeted
Someone noticed that when you have hundreds / thousands of cores in a supercomputer, the individual utilization boxes in Task Manager start to look like pixels. People started making pictures by doing different amounts of work on specific processors.
It escalated quickly.
This Post is from an account that no longer exists. Learn more

Abed Merii 🎙️ retweeted

Latest update:
Currently working on my first data-wrangling project where I’m being exposed to real data for the first time!
Thanks to my mentor @AH_Merii, without your guidance and genuine support I wouldn’t have learned this much.
Ps. I’m still learning and will always be 👩🏻💻
Abed Merii 🎙️ retweeted
Day 82 #100DaysOfCode
It’s been a while since I last tweeted about my progress.
But pausing those tweets doesn’t mean that I stopped learning!
It’s been a productive month and I’ve learned so many new stuff!
Abed Merii 🎙️ retweeted

In case you guys missed it all my udemy courses are still FREE in light of current situation. Keep learning ! ❤️

In the light of the current situation I decided to make all my 7 software engineering udemy courses free of charge. This is only a small way I can help, with my knowledge. Please keep learning 📚 📖 and share the love.
Stay safe. ❤️
udemy.com/user/hussein-nasse…


