
PhD student at CIIRC CTU in Prague and https://xitter.gq/t.co/I0d7P3u2Nu under supervision of Josef Sivic and Patrick Pérez. Interested in computer vision.
Joined July 2019
- Tweets50
- Following173
- Followers95
- Likes141





Antonín Vobecký retweeted

This paper went completely under the radar!
Meta researchers have developed a novel and simple self-supervised learning framework competitive with DINOv2 and DINOv3!
"Scalable Patch-Level Self-Supervised Learning"
The authors introduce JEM, a principled student-teacher method that learns to align patch representations across different views. Additionally, it incorporates explicit regularization to ensure representations are informative and prevent structural collapse.
The framework outperforms DINOv2 in a controlled setting on dense tasks, and even beats the DINOv3 checkpoint despite it being trained on 12x less data.

Antonín Vobecký retweeted

What if the metadata from acquisition was enough? 👀
Sometimes the most useful labels aren't labels at all.
Introducing📄 Who Needs Labels? Adapting Vision Foundation Models With the Metadata You Already Have

Antonín Vobecký retweeted

Check out the CLIP-DINOiser idea and say hi to the team in the posters of Wednesday afternoon. Poster #72 #ECCV2024

Hear! Hear! We're presenting CLIP-DINOiser at poster #72 in the Wednesday afternoon session.
Come find out our simple and cost-efficient open-vocabulary semantic segmentation approach #ECCV2024


Antonín Vobecký retweeted

🍕 Heading to Milan for #ECCV2024!
Our team has put together a mega-thread of our papers. I'll be presenting works on LLMs/VLMs, motion forecasting, and corner-case generation for autonomous driving.
Looking forward to great discussions!

Antonín Vobecký retweeted

hahaha that's a nice praise😊

SigLIP was on my to-read list for quite some time.
We (/w @ritwik_raha) present a blog post on CLIP vs SigLIP. The SigLIP paper communicates the ideas so well, that people do not need to read our blog post, but we present it anyway.

ALT https://blog.ritwikraha.dev/choosing-between-siglip-and-clip-for-language-image-pretraining
Antonín Vobecký retweeted

We will present our OccFeat poster at noon in the Workshop on Autonomous Driving #WAD2024 #CVPR2024
We'll be there with @SpyrosGidaris @AVobecky
OccFeat: Self-supervised Occupancy Feature Prediction for Pretraining BEV Segmentation Networks
by S. Sirko @AlexandreBoulch @SpyrosGidaris @abursuc @AVobecky @ptrkprz R. Marlet
tl;dr: BEV pretraining w/ geometry & semantics (DINOv2 features)
#WAD2024
arxiv.org/abs/2404.14027

Antonín Vobecký retweeted

🚨@CIIRCCTU researchers @AVobecky and @JosefSivic have developed a new #POP3D method, which was a big success at the @NeurIPSConf 2023.
The work was developed in collaboration with the @valeoai research team, & it's part of the EXA4MIND Industrial Application Case.
Read more⤵️

🚨 Výzkumníci CIIRC @AVobecky a @JosefSivic vyvinuli novou metodu #POP3D, která zaznamenala velký úspěch i na konferenci @NeurIPS 2023. Práce vznikla ve spolupráci s výzkumným týmem @valeoai.
Přečtěte si více zde: 1url.cz/iu6nU
@EXA4MIND
Antonín Vobecký retweeted

🚨 Výzkumníci CIIRC @AVobecky a @JosefSivic vyvinuli novou metodu #POP3D, která zaznamenala velký úspěch i na konferenci @NeurIPS 2023. Práce vznikla ve spolupráci s výzkumným týmem @valeoai.
Přečtěte si více zde: 1url.cz/iu6nU
@EXA4MIND
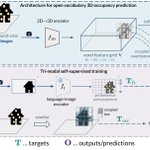
[@NeurIPSConf'23]🚨Did you miss it? Our POP-3D generates open-vocabulary 3D occupancy predictions from 📷 surround-view images only, w/o human labels & w/ distillation from pre-trained models.
We also propose a new small 3D-occupancy open-vocabulary benchmark #neurips2023⬇️ [1/N]
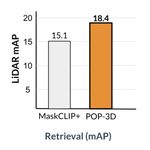
For open-vocabulary language-driven object retrieval, POP-3D outperforms the MaskCLIP+ baseline (+3.5 mAP) that needs 3D point clouds for projecting image-language features to voxel space. [7/N]

More qualitative results of POP-3D 🚘+📸=⬇️.
Work in collaboration w\
@oriane_simeoni @HurychDavid @SpyrosGidaris @abursuc @ptrkprz and Josef Sivic
@CIIRCCTU @valeoai @EXA4MIND [8/N]
🖥️: vobecant.github.io/POP3D/
📜: arxiv.org/abs/2401.09413
⌨️: github.com/vobecant/POP3D

Antonín Vobecký retweeted

🚨Happy to release on arXiv CLIP-DINOiser: Teaching CLIP a few DINO tricks🦖🎓
We obtain dense CLIP features in 1 forward pass w/o feature alteration and w/ almost no computational extra cost to facilitate open-vocabulary semantic segmentation 🧶
🖥️: wysoczanska.github.io/CLIP_D… [1/N]
In less than an hour I will present our work 🍾 “POP-3D Open-Vocabulary 3D Occupancy Prediction from Images” at @NeurIPSConf.
We perform open-vocab 3D semantic segmentation w/ only images at inference!
Come to chat at poster #115!
Webpage: vobecant.github.io/POP3D/

POP-3D: Open-Vocabulary 3D Occupancy Prediction from Images
by @AVobecky @oriane_simeoni D.Hurych @SpyrosGidaris @abursuc P.Pérez, J.Sivic
tl;dr: open-vocab 3D semantic occupancy maps from multi-cam inputs w/ tri-modal self-supervised learning #neurips2023
vobecant.github.io/POP3D/


🍾POP-3D
If you are interested in open-vocabulary segmentation in 3D using only images, come check our poster on Thursday morning!
Poster #115
⏲️Th. 14 Dec. 10:45 a.m. CST — 12:45 p.m. CST
Thanks to @oriane_simeoni D.Hurych @SpyrosGidaris @abursuc @ptrkprz J.Sivic! 🥳
