

Calgary, Canada
Joined September 2022
- Tweets15
- Following25
- Followers44
- Likes5





Aida Mohammadshahi retweeted

1/10 🧵
🔍Can weight symmetry provide insights into sparse training and the Lottery Ticket Hypothesis?
🧐We dive deep into this question in our latest paper, "Sparse Training from Random Initialization: Aligning Lottery Ticket Masks using Weight Symmetry", accepted at #ICML2025

✨Our paper is now officially published in Transactions on Machine Learning Research (TMLR)!
We explore how knowledge #distillation (KD) impacts fairness & bias in AI models, across both group and individual fairness.

On balanced datasets like CIFAR-100 and ImageNet:
Up to 41% of classes showed statistically significant accuracy shifts post-distillation.
These biases are subtle, and not visible in top-line accuracy.
Distillation changes behavior in non-obvious ways.

1
2
268
Distilled models aren't just “smaller copies.”
They’re behaviorally different, especially in fairness-critical settings.
check out our full paper for more details 👇
openreview.net/pdf?id=xBbj46…
1
2
214
Aida Mohammadshahi retweeted

✨Our new @unireps paper tries to answer why the Lottery Ticket Hypothesis (LTH) fails to work for different random inits through the lens of weight-space symmetry.
We improve the transferability of LTH masks to new random inits leveraging weight symmetries.
🧵(1/6)


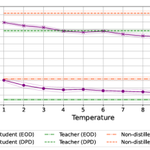
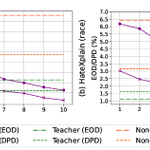
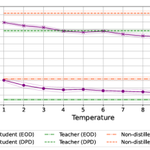
Knowledge #distillation is a widely used model compression method. We explore the nuanced impact of temperature on distilled models' #fairness ⚖️. Our findings show distilled students are less fair than their teachers at typical temps, but can be more fair in some instances…🧵👇


Distilled models are everywhere—from mobile devices to large-scale applications. Our findings highlight the need to consider fairness carefully when deploying these models, especially in sensitive applications. @UCalgary @CalgaryMLC
📄Check out our paper:
arxiv.org/abs/2410.08407
144