

A Bioinformatics Platform to Gain Bioinformatics Skills in Python, R, Linux, NGS, Single-Cell Genomics & Metagneomics | Get Analysis Services & Consultancy
Islamabad, Pakistan
Joined July 2020
- Tweets891
- Following0
- Followers1.1K
- Likes21






Need help with #Bioinformatics Analysis for your project?
Just contact us at [email protected] and avail bioinformatics services catered to your needs or visit consultancy.biocode.org.uk
#Genomics #MolecularBiology #NGS #ComputationalBiology #Biology #Biotechnology

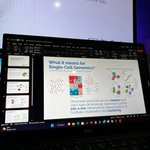
CEO, @twDignity is going live for an oral talk on Parkinson's disease research at the International Society for Computational Biology conference in Lyon, France.
iscb.junolive.co/ismb2023/li…
9/ How exactly it is done? You can use scanPy (Python) or Seurat (R) to accomplish this, but don’t directly go into dimension reduction, first you will have to do quality control and normalization among other steps.
8/ To put it simply, the aim of dimension reduction in single-cell genomics projects is to convert high-dimensional data into a more compact form, which enables the performance of clustering and the identification of cell-type subpopulations within a complete sample set.
7/ By using these methods to reduce the dimensionality of the data, we can gain a better understanding of the complex relationships between individual cells and their gene expression patterns.
6/ This allows us to identify patterns and relationships that would be difficult or impossible to detect in the original data.
5/ This is where machine learning comes in. By leveraging advanced algorithms for dimension reduction, we can transform the high-dimensional data into a more manageable low-dimensional space.
4/ However, with this newfound ability to analyze so many cells and genes comes the challenge of high dimensionality. The data generated by single cell genomics can contain thousands of variables, making it difficult to extract meaningful insights.
3/ Single cell sequencing allows us to investigate gene expression patterns in thousands of cells simultaneously, opening up exciting new avenues for understanding the complex relationships between genes and cells, where the structure of the represents m x n (genes x cells)
2/ As the scale increases, so does the level of responsibility where single-cell genomics quickly becomes a problem of high-dimension data rather than a biological concept - let us explain.

6/ Oh, this slide is part of one of our detailed courses on single-cell RNA-seq analysis using Linux, R, and Python.
6/ Voila!, you have your first gene count matrix that you can now import into Seurat (R package) for further quality control, dimension reduction, cell clustering, and finally cell subpopulation identification and differential gene expression analysis between them.
5/ STARsolo takes your raw reads, performs alignment against a reference genome while taking into account the provided whitelists (cell barcodes), and provides you a final cell vs. gene count matrix.
4/ After retrieving the dataset, we need to install some software, packages, and download some files. Next, we need to choose an aligner. I suggest using STAR with its submodule STARsolo.
3/ Once you have established which disease you want to analyze in terms of scRNA-seq, take its scientific name and put it on ArrayExpress, EMBL ENA, or NCBI GEO and start hunting for a disease vs. control/normal dataset. The dataset must be in FASTQ format.
2/ Next, figure out the disease that you want to work on. Single-Cell RNA-seq data is still scarce and not readily available, so if it’s alright for you, I suggest choosing any cancer because the data is readily available.