

10+ years in tech: Engineering + AI + platform. hackathon winner. open source contributor. kickball mvp. Building RentSi and https://xitter.cf/t.co/aMN2ZSpVCy
Remote
Joined December 2025
- Tweets3.8K
- Following755
- Followers828
- Likes18.3K




Pinned Tweet
gpt-6.1 sol has the slowest tps and finishes a short code question first
in my testing, start to exit, typical time over 6 runs each:
gpt-6.1 sol: 9.3s
muse wonder: 15.8s
opus 5.5: 16.7s
gemini 4 argon: 17.0s
tps doesnt mean a task finishes first

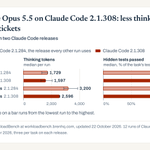
same opus 5.5, newer claude code cli version, less thinking on my tickets test.
testing versions 2.1.308 against 2.1.284, every tickets run thought less, about 19% at the median.


Opus 5.5's thinking on my bug hunt spiked on Sept 30, then went back.
from my testing it used:
~ 1,737 thinking tokens per run on Sept 29
~ 5,314 on Sept 30
~ 1,736 on Oct 21
same Claude Code version.
different cli version tests running today.

keep seeing reports of reduction in ability of Opus 5.5 on x in the past few days.
going to run some tests in the lab and will post on workloadbench.brenhq.com
also starting a new testing theory today with different cli versions to see their potential impact on test results


Coding is solved

October has been an absolute nightmare for software
> Railway - customer secrets exposure
> LiteLLM - malicious PyPI + Docker releases
> Zeabur - infrastructure breached
> OpenCode - AI API keys exposed
> OVHcloud CLI - official binaries backdoored
> Rank Math PRO - malware in official plugin
> TeamUpdraft - customer data compromised
> ConnectWise - cloud backup identities compromised
> Tensorlake - npm package infected
> SubQuery - backdoored npm package
> GhostAction - GitHub repos with malicious workflows
> PHP - critical RCE vulnerabilities
> Node.js - security vulnerabilities patched
> eMudhra - certificate authority keys compromised
> Tailscale - eMudhra incident
At this point, the biggest security risk might not be the code we write, but the code we trust...


keep seeing reports of reduction in ability of Opus 5.5 on x in the past few days.
going to run some tests in the lab and will post on workloadbench.brenhq.com
also starting a new testing theory today with different cli versions to see their potential impact on test results

From my testing of Opus 5.5 and GPT-6.1 SOL, 89 to 96% of a typical long task's prompt came from cache.

Bren retweeted

Haven’t read the thread, and I’m still sleepy, just woke up.
But the premise that the “agent has to learn everything in the project from scratch” is false.
It doesn’t need to understand the entire project to implement a new feature or fix a bug. This is obvious true, because much can be inferred from a single file from the interfaces it interacts with.
And the more self-contained your files and modules are, the less context it needs.
Of course, some tasks require a broader understanding of the codebase. But that can be rediscovered as needed.
This is something I realized pretty early on. And it’s still one of the things I actively control as the human in the loop: I decide what context the agents get, and what they need to know. A well specified prompt will make the agent state whether more context is needed, but the agent can figure that out by itself anyways.
I’d go further and argue that “knowing everything about the project” is detrimental. The underlying architecture is still the same, and everything in the context competes for attention. Things unrelated to the task injected into the context can only be detrimental.
all the comments here are plugin/tools/mem caches which all *still burn tokens, either by more model calls or just file bloat.
And yes, all the solutions to this problem become "stale". a conversation you just had adding a feature has made prior chats stale.


You're not a REAL engineer if you haven't rebuilt an app you pay $10 a month for with 10x that amount in tokens.

Trending repository of the week 🏅
rea
Reverse engineer anything with agents, from app behavior down to native binaries.
Last week: 229,268 ⭐
Total: 330,497 ⭐️
github.com/morluto/rea

We need 2 week to slow the curve of AI psychosis

It is becoming f*cking dangerous
A 23-year-old dev from China just ran 300 Claude Code agents in parallel and hooked them to a verification layer so none of them could bullshit him
He opens the live dashboard:
- 300 agents writing and checking at the same time
- Every output verified against the source in ~100 ms
- Three passes over 100 company profiles → zero errors left
- Everything dumped straight into an Obsidian vault
The trick is the split: one model does the work, a cheaper one decides if the claim is actually true. The loop doesn’t stop until everything checks out
An analyst team would bill weeks for this. He got it in one run
Same kind of Second Brain + swarm setup that keeps circulating. Bookmark the full breakdown
The year is 2050.
Robots do all blue collar work.
AI does all the white collar work.
Life expectancy is 150 years old.
Drones keep humans under control.
elon and anthropic are telling you to own assets
20% of Anthropic stock is committed to public good
elon giving every kid in America one share of spacex
tesla offering buy in to cybercabs for a robotaxi fleet
AI is removing the need for human intelligence and labor
