

ML research PhD student @unibielefeld | Prev. @UniofOxford, @Honda Research, @CSHL, @LIACS
Joined September 2024
- Tweets142
- Following1.5K
- Followers308
- Likes1.4K




Pinned Tweet
Signals of physical plausibility are hiding in the geometry of frozen image encoders. No video training. No physics supervision.

Christian Internò retweeted

In 2024, @zimmerrol and I wrote a paper on AutoInterp for vision models. The interpretability score (MIS) is basically an accuracy of how well most and least activating inputs can be distinguished. He analyzed over 70 Million neurons from over 800 models and found scores from 80% to over 90%. Back then, I was really into SAEs/Superposition and kind of bummed that even the neurons scored so high – maybe now this is relevant again?
proceedings.neurips.cc/paper…


Christian Internò retweeted

Looking for a PhD program where you can study computational neuroscience? NYU has a fantastic array of researchers covering the field, and we'd love to consider your application:
groups.google.com/g/systems-…
Christian Internò retweeted
Check out @hazel_heejeong latest paper. This was a pleasure to work on. Turns out now that we know World Models can be disentangled we can move on to Compositional Generalization: Has your model actually learned the dynamics of the world or is it just predicting a biased policy?

Your world model may know less about the world than you think.
I've always wondered what world models really learn.
Humans don't memorize every trajectory. We learn rules we can reuse.
Can world models do the same?
We built AnyGoal to find out.
hazel-heejeong-nam.github.io…
Christian Internò retweeted

New surprising result:
We trained AI recursively on its own safe generations, while giving it a benign cue. Models became increasingly misaligned over time, giving advice on how to do harm and build biological weapons.
We call this Progressive Misalignment. 🧵👇
Christian Internò retweeted
Does this explain everything, like why we found direction selective neurons or face cells in the brain or why all these monosemantic neurons were/are about to be found in LLM MLPs?
NO. This is theory. There are assumptions. It is always a bit of "theory fairyland" (@ChrisInterno). Our goal as theoreticians is to bring these assumptions as close as possible to reality (e.g., not just pretending the KL were the other way around). But ultimately, it is a model, hopefully a useful one that will spark further research, ideas and hypotheses ☺️
Christian Internò retweeted
Why? How did we ever get so lucky find meaningful neurons inside neural networks?
We finally have a theory: arxiv.org/abs/2610.20851
🧵🧵🧵


interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
already-clean.goodfire.com/

Christian Internò retweeted
In 2023 I showed @zimmerrol this neuron's most activating images and said that it is polysemantic (arxiv.org/abs/2310.11431). He said hold on, I think it codes for "crossing diagonal lines".. 🤯
That was eye opening and highlighted a limitation of our VisionAutoInterp metric (openreview.net/forum?id=oYyE…)

interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
already-clean.goodfire.com/
Christian Internò retweeted

We’re bringing natural-language control to any scientific generator.
We are very excited to introduce LLM-to-Flow Distillation (LFD), a method to adapt scientific generators to high-level natural-language discovery goals.
Starting from textual goals like “design peptides with promising anticancer activity” or “design small molecules binding to the D2 dopamine receptor”, LFD distills high-level goal-related knowledge from LLMs into scientific generators through iterative DPO on LLM-generated sub-goals.
🔥 LFD does not need task-specific proxy rewards, works with any frontier LLM via API-access, and outperforms state-of-the-art reward-guided methods such as FlowGRPO and DiffusionNFT on held-out computational evaluations. (1/6)
Christian Internò retweeted
Looking for a PhD program where you can study vision from different perspectives (computer vision, visual neuroscience, visual perception, image processing)? Consider applying to NYU!
visionscience.com/pipermail/…
Really enjoyed working on this, thanks to @ZacharyShinnick! I believe it will open so many new research directions :)
🌐 Project: zlshinnick.github.io/procedu……
📄 Paper: arxiv.org/abs/2609.37631
A tiny 1M-param model trained only on procedural data (no images at all) makes an 85M-param ViT better at: image classification, downstream vision tasks even language & coding tasks.
We found out it suppresses high-norm tokens while keeping attention on actual content.
@HemanthThe1st, @AntonvdH & @DamienTeney.


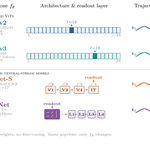
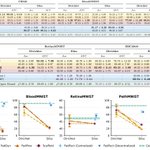
𝗚𝗲𝗼𝗣𝗵𝘆𝘀 is accepted at NeurIPS 2026! (github.com/ChristianInterno/…). Physical plausibility is written into the geometry of frozen image-encoder features.
When I started working on physical plausibility, almost no shared generated videos/data were available to the community and every experiment began from scratch. That slowed everyone down, so today we release everything we built along the way:
🎬 𝟯,𝟭𝟲𝟴 𝗴𝗲𝗻𝗲𝗿𝗮𝘁𝗲𝗱 𝘃𝗶𝗱𝗲𝗼𝘀 (drive.google.com/drive/folde…): 16 MAGI-1 24B candidates for each of the 198 Physics-IQ scenarios, each with its Physics-IQ score. You can benchmark your method without generating a single video: picking the first candidate scores 53.3, the best possible pick 73.1, and our GeoPhys picks reach 64.6 with the official Physics-IQ code and 59.9 on Physics-IQ Verified ( Robert Geirhos, @sammtmd, @GoogleDeepMind and @Anates_Labs , @TimRaedsch)
📦 𝟮𝟮𝟳 𝗚𝗕 𝗼𝗳 𝗳𝗿𝗮𝗺𝗲-𝘁𝗿𝗮𝗷𝗲𝗰𝘁𝗼𝗿𝘆 𝗳𝗲𝗮𝘁𝘂𝗿𝗲𝘀 (huggingface.co/datasets/CInt…): LikePhys, IntPhys 2 and all 3,168 Physics-IQ candidates, through four frozen encoders (DINOv2, DINOv3, CORnet-S, VOneNet), at every layer. You can explore the geometry of physical plausibility without a GPU.
🧠𝗧𝗵𝗲 𝗻𝗲𝘂𝗿𝗼 𝗘𝗘𝗚 𝗮𝗻𝗮𝗹𝘆𝘀𝗶𝘀: the data and scripts behind the alignment with human EEG responses, and matched video pairs rendered with ADEPT (github.com/JerryLingjieMei/A…) with Habon Issa (@CSHL)
🛠️ 𝗧𝗵𝗲 𝗰𝗼𝗱𝗲 (github.com/ChristianInterno): get the results, calibrate YOUR GeoPhys to your own model and domain with a few labelled pairs, use it on (𝟭) your videos for violation detection, (𝟮) best-of-N selection, or (𝟯) as a per-video plausibility evaluation metric.
A Colab demo introduce you to GeopHy on real LikePhys videos in five minutes: colab.research.google.com/gi…
Odyssey-3 (@odysseyml) and FLUX 3 (@bfl_ai) just took the top of Physics-IQ Verified, congrats! I believe inference-time verification matters, and a training-free verifier you can calibrate to your own model might push that further.
I'm so curious to see what you build with this!
💻Code:github.com/ChristianInterno/…
🎬 Videos: drive.google.com/drive/folde…
🤗 Features: huggingface.co/datasets/CInt…
📄 Paper:arxiv.org/abs/2606.20707 (will be updated soon with new content and results)
🌐 Project page: christianinterno.github.io/G…
With @klindt_david, Barbara Hammer (HammerLab ML), @EeroSimoncelli, @philiptorr, Fabio Pizzati, Francesco Pinto, Habon Issa, @alexpondaven, Ivan Laptev, Markus Olhofer (Honda Research Institute Europe).
#NeurIPS2026 #VideoGeneration #WorldModels #PhysicalReasoning #PhysicalPlausibility #PhysicsIQ #ArtificialIntelligence

Christian Internò retweeted

This is a result I’ve dreamt about for many years: *unpaired translation between images and text*
I thought it might be only slightly possible, the kind of thing you have to really squint at. But Dominik proved this wrong. You don’t have to squint. Worth looking for yourself:

DINOv2 has never seen a caption, and Qwen3 has never seen an image. We still aligned their embedding spaces without a single image-caption pair.
It even works when the images and the captions come from different datasets.
Project page: dominik-schnaus.github.io/un…
⬇️
Christian Internò retweeted

What would a language model learn if its training data stopped before 1913?
Our Language Model from 1913, TypewriterLM is headed to EMNLP 2026 🇭🇺!

Our paper on History Language Models has been accepted to the EMNLP Main Conference!
We trained TypewriterLM, a 7B model on 54 billion tokens of historical text published before 1913.
Paper: arxiv.org/abs/2606.02991v2

Christian Internò retweeted
Check out @YujiaZheng9 latest paper. This was a pleasure to learn about. Using the sparse support structure of the Jacobian (e.g., moving an object does not change the whole image) is a very elegant way of disentangling latents all the way (not just up to linear mixing like in our prior LeJEPA result). Great work 🚀

Is it possible to provably recover individual latent variables of the true world, even without reconstruction (e.g., JEPA)?
Yes, with DSReg, a simple regularization that can be applied post hoc to your pretrained model!
dsreg.github.io/
Christian Internò retweeted
The @Redwood_Neuro strikes back – forget about SAEs, sparse coding done right 😁
👏 @hadivafaii and team 🤗

LLMs have shown us that sand can think. But how? We need powerful methods to interpret their mind.
⚫️ Introducing BeFOND, an encoder-free iterative sparse coding model.
⚫️ BeFOND has closed-form inference and learning rules, both unified as natural gradient flow on free energy.
⚫️ At 524k width, BeFOND matches Gemma Scope's single-feature probing accuracy with over 1000x fewer samples (~6M vs 8B SAE-training tokens).
⚫️ BeFOND keeps improving with SAE width, while alternatives plateau.
⚫️ Importantly, we provide theory to explain WHY BeFOND works so well. Read on! 👉🧵[1/17]
Work with my amazing co-lead @tejasraoai

Christian Internò retweeted

Accepted to NeurIPS 2026 GenAI4Health workshop! Go team! 🚀

Christian Internò retweeted
🧠 The Science of Intelligence 🧠
Check out the recordings/zooms of this new course at @Redwood_Neuro redwood.berkeley.edu/courses…
Very excited to see how Jake, Mike, Bruno and others are transforming the Redwood into the new center for studying and designing a theory of intelligence ⭐️

