

CoreWeave is The Essential Cloud for AI. Built for pioneers by pioneers. Trusted by 9 of the 10 leading AI labs.
United States
Joined March 2018
- Tweets2.1K
- Following465
- Followers30.4K
- Likes2.6K





Pinned Tweet
NVIDIA Vera Rubin NVL72 is available on CoreWeave.
@Cognition is running @devindevelopers in production on it, at up to 4.8x the total token throughput of GB200 NVL72.
V100 in 2017. Vera Rubin today. Same platform, every generation. crwv.co/utcq5


Richard Ahlfeld walked @altryne through how he explains physical AI to LLM engineers.
The reasoning a good chatbot does stays the same.
Our CoreWeave Physical AI team just released Launchables.
Tested Templates for robotics and simulation tools, each run with one command. crwv.co/utSf3
Today we're launching the CoreWeave Zero Trust AI Framework, a six-layer framework built to keep us out of your trust chain for sensitive AI workloads.
With Support Access Management, support gets in only with your OK, and access ends when the work does. And we don't train on your data.
Remote Key Encryption is coming later this year and is built so that, without your key, we can't decrypt your data. crwv.co/utTZz
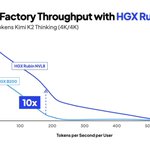
The @NVIDIA HGX Rubin NVL8 is coming to CoreWeave Cloud this quarter, and it's built for agents with a lot to remember 🧠
Its HBM4 holds large KV caches for million-token contexts, so many agent sessions stay live at once on a single node.
Sixth-generation NVLink keeps tensor-parallel serving inside the node, and NVIDIA projects up to 10x more tokens per megawatt than HGX B200. crwv.co/utTM9
CoreWeave Physical AI Launchables are live today. Tested Templates for robotics and simulation tools, each run with one command.
Setup time caps the number of experiments a robotics team runs. Get the week before the run back, and that number goes up.
In our @nvidia Isaac Sim example, a dozen variations off one baseline each took about 30 seconds to launch, by hand.
Request a briefing here: crwv.co/utSf3
Reliability is what keeps @cognition on CoreWeave. @silasalberti explains why.
On a run across thousands of GPUs, one replica going down stops the whole thing.
CoreWeave Mission Control is included with CoreWeave Cloud.
It replaces unhealthy nodes before they hurt throughput, and GPU Straggler Detection, in preview, finds the one GPU dragging a synchronous job. crwv.co/utu0S
Every math teacher has written "show your work" in red pen. @CarinaLHong turned it into an output format.
The @axiommathai team built an AI for really hard math that writes its proofs as code a machine can check. Watch Carina's story 👇
Prove your workload at production scale before day-one billing. Apply for ARENA Pass below. crwv.co/utOB3

Bringing production-scale AI inference to life takes a strong open ecosystem. As a founding member of the project to now releasing llm-d 1.0, we're thrilled to support this community and fuel the future of open innovation 💪

Scale distributed inference and control AI serving costs with confidence. llm-d 1.0 brings multi-tenant quality of service, zero-downtime rolling updates, and prefix-cache-aware routing to your production workloads. Explore the release: red.ht/4ysmUU5 #PyTorchCon

GPU sandboxes in CoreWeave Sandboxes are in preview.
Get enabled on CoreWeave Forge and pay hourly with no commitment.
RL training can push sandbox counts into the thousands per step. A memory spike or infinite loop stays in the sandbox that caused it. @deok_filho told @altryne why there's an enable step.
Deok and @Yolo_Jenkins420 host Run Agents with Guardrails today at 11 a.m. ET if you want to see it in action. crwv.co/utu0E
More than 250K people will spend time with their Tolan this month, after more than 70M conversations last year. Congrats to @tolanworld on today's $30M raise 🎉
We're proud Tolan chose CoreWeave Dedicated Inference for the very low latency and cost-efficient token throughput a companion at that scale needs.
The optimizations we've achieved together on our infrastructure have been incredible, and we're proud to keep building with you.

Last year we launched Tolan, inspired by a vision of AI that sees you and believes in you, not one that books restaurant reservations for you.
Your Tolan shows up for you at 3am when you’re alone with your newborn. On your commute when you’re anxious about the day ahead. When you just finished a new show and none of your friends have watched it yet.
The people who love Tolan are parents. Caregivers. Moms in Dallas and Dads in Atlanta. People who aren’t trying to optimize and be more productive, but who simply want to feel seen and supported in their aspirations.
This month more than 250k people will spend time with their Tolan. Those users have exchanged billions of messages across more than 70m conversations over the last year.
Today, we're announcing $30m in additional capital from @mignano and @usv, with @khoslaventures and @rabois doubling down, bringing our total capital raised to $60m.
To celebrate, we made a short film celebrating some of the ways that Tolans show up :)
Someone asks if last week's fix helped your agent, and you start opening tabs.
The trace that showed the failure is in one tool and the eval that would prove the fix is in another, so you stitch them together by hand.
CoreWeave Forge is available and keeps all of it connected, so you can see what changed and whether it helped.
Free to start, with a 30 day Pro trial on every new account: crwv.co/utcVH
Watch @GoldbergChen lay out the whole AI loop in under two minutes.
Builders, another CoreWeave Hacks is on the way.
Follow our Luma calendar so you hear about it first 🗓️
utm.io/utaTo

Five weeks ago, Jev was a secret on our San Francisco floor 🥷
@typesafeai was still in stealth when it sponsored CoreWeave Hacks on September 12 and 13. The team brought Jev before it launched and stayed all weekend helping over 60 teams build on it.
Two days later, @CompleteSkeptic announced Jev to his 1,500 followers. That post is now past 40 million views, and he's at 156K followers.
It hasn't slowed down since.
He told the WSJ that Jev had now crossed a trillion tokens a day and was in use by about a quarter of the Fortune 500.
Workday's new Workday Home is powered by it, and Vercel says nothing was ever adopted faster on its AI Gateway.
Proud that they unveiled it with our builders first. This one's going in the CoreWeave Hacks history books.
In reinforcement learning, inference is part of the training loop. Every checkpoint used to mean a redeploy, and the trainer waited.
CoreWeave RL Rollouts load the new weights into a live deployment without touching in-flight requests, about 15x faster than a redeploy cycle.
@nvidia and @youdotcom used it to post-train Nemotron 3.5 Lightning for web search, lifting BrowseComp accuracy from 36.97% to 45.45% while reducing tool calls by 30.24%.
Full breakdown here: crwv.co/utdYc

"Whenever you mix a software and a hardware layer together, the integration is never out of the box."
Behind every frictionless developer experience is serious engineering under the hood.
In this episode of the AICE podcast, Field CTO Christian Stano breaks down how @anyscalecompute and CoreWeave aligned both technical and product layers so AI teams can get up and running instantly.
Full episode here: crwv.co/utdXJ
Raising the security bar for agents helps everyone building them.
If you want to evaluate SPACE on your own CKS cluster, our setup guide has the steps: crwv.co/utuZ7


We're open sourcing SPACE, the sandbox platform that runs every task in Perplexity Computer.
SPACE gives each agent task its own Firecracker microVM and controls credentials and outbound traffic from outside the VM.
Available now under Apache 2.0: github.com/perplexityai/SPAC…
🔦 Beam, Reflection's first model with open weights, is live today on CoreWeave Serverless Inference.
Call it through an API and leave the GPUs to us.
We are also proud to share that @reflection_ai used @wandb in CoreWeave Forge during Beam's training.
Developers in the private preview have been calling it fast and accurate, and they like that it doesn't ramble.
See what @TheCodingSoup on our team built with private preview access below.
Get started with Beam here: crwv.co/utuxk
Our CISO Jim Higgins wrote about why AI security controls have to travel with the work.
Keys, identity, telemetry, revocation, and audit evidence stay attached across training, inference, evaluation, and agents.
Jim closes with nine questions for any AI platform in production here: crwv.co/utuew


CoreWeave retweeted

During @reflection_ai’s private preview of Beam, I built a haunted escape room to put its coding and reasoning to the test.
I created a game called “Code Your Way Out”, and it's one room with three linked puzzles. Beam has to repair a brass orrery by lining its rings up with a constellation, route the light, then program its escape through a sealed hatch.
Beam never sees the room. Each turn, it gets text observations and writes Python; the code runs in a @CoreWeave Sandbox, and the game engine validates every action before the explorer robot moves.
Beam was out in about 30 seconds. Super bullish on this model and really excited to see builders get this model in their hands.