




Pinned Tweet
Is @openservai the @Tesla of AI Data? The Hidden Data Company Thesis.
There is a strong conceptual parallel that some $serv supporters would make, though the company is much earlier in its lifecycle than Tesla, so the scale and proof points are very different.
The thesis is essentially:
Tesla’s moat:
Millions of cars → billions of miles → proprietary real-world driving data → better autonomy
OpenServ’s potential moat:
Millions of agents → trillions of actions → proprietary enterprise reasoning data → better AI agents
The key idea is that the “value” may not be the AI model itself. Just like critics say, “Tesla is just a car company,” or “DeepSeek can copy a model,” the counterargument is:
You can copy a model. You cannot copy the data flywheel. For OpenServ, the potential strategic asset would be:
How agents interact with real enterprise workflows? Which actions succeed or fail?
How agents collaborate with other agents?
Human feedback and corrections. Long-term memory of organizational processes
Security, audit, and compliance histories.
That creates a “reasoning dataset” that a new competitor cannot instantly recreate…as @NFTreeVerse rightfully argued:
xitter.gq/nftreeverse/status/206…
The bull case would be that the future AI stack has three layers:
1. Foundation models: the brains (OpenAI, Anthropic, Google, etc.)
2. Agent infrastructure: the operating system where AI actually does work
3. Enterprise data flywheel, the accumulated knowledge from billions or trillions of agent actions
If/when OpenServ becomes the layer where enterprise and government AI agents operate, its data could become a durable moat in the same way Tesla believes its driving data is a moat.
The biggest caveat: this thesis requires mass adoption. A data moat only compounds if the platform reaches sufficient scale. Tesla’s advantage came from having millions of vehicles in the field. OpenServ must prove it can achieve a comparable network effect in enterprise AI.
The most bullish analogy (I love analogies…just like my Netflix one I’ve applied for serv):
Tesla didn’t become valuable because it built the best car. Their thesis was that it turned every car into a data-generating robot.
The OpenServ thesis is similar:
The winners in AI may not be the companies that build the smartest agents. They may be the companies that own the largest repository of real-world agent experience.
That is likely the core argument behind the phrase often associated with OpenServ: “Millions of agents. Trillions of actions. One intelligent layer.” 🚀

$SERV – "It's just structured prompting. Anyone could build this in a weekend."
Fair point.
"Can it be replicated?" is due diligence 101.
The paper's public. The prompt's in the appendix. Start whenever you like. But read this first.
open.substack.com/pub/flasho…
DCL4385 retweeted

My SERV Hackathon 02 builder story 🧵
I kept going and shipped Agent Firewall.
every tool call an agent makes gets checked against your policy by SERV Reasoning before it runs.
allowed, blocked or escalated, with the reason logged.
the big lesson: never let the model be your only line of defence.
so I stacked three layers:
• SERV Prompt Guard catches injections,
• SERV Reasoning makes the call,
• SERV Shadow Agent double-checks it.
in the demo it lets a safe call through, sends a risky one to a human for approval, and stops three different attacks.
Then @openservai's CTO quoted it.
That really did something for my confidence I can't fully explain.
The person building the infrastructure looked at my work and said it's the layer most production stacks are missing.
If you're doubting whether you're "technical enough," you're probably closer than you think.
Ship it anyway!
github.com/defisensei-maxxin…


Agents are getting access to email, money and company data much faster than anyone is building the controls around them. I, for one, haven't given any agent access to any of my personal data yet.
@defisensei7’s Agent Firewall uses SERV Reasoning to check every tool call against your policy before it happens, and keeps an audit trail of why each action was allowed, blocked or escalated.
It's the layer most agent stacks I see in production are still missing today. Surprising, I know.
DCL4385 retweeted

SERV’s tech stack made this possible.
a platform where you can create mini agents using dolphin ai for menial internet jobs, helpers for everyday tasks, and lots more, with serv reasoning guiding every step of the way while reppo evaluates the scores of each app so renters can rent the quality ones.
it’s a working economy between builders and users.
you build, you rent, users rent your agents, you earn 90% of the fee.

SERV’s tech stack is the result of more than two years of intense AI research and development.
Now everything is converging into one robust agent execution system: the SERV platform.
An operating system for AI agents where every element works has been refined by running production workloads with teams across enterprise, governments and crypto.
Our work has followed one long-term plan from day one, and every stage of the roadmap has moved SERV further along the same trajectory.
Graph Sharding is the next stop, bringing SERV closer to becoming the industry standard for AI agents.

DCL4385 retweeted

We've been talking a lot about pairing SERV with open models, so it was great to see someone in SERV Hackathon 02 building with this combination.
@stratton001 built a Recovery Copilot for Janus in the @dphnAI track. Dolphin interprets the evidence from Sui handovers, SERV Reasoning turns it into a structured recovery plan, and strict validation rejects anything fabricated or anything that tries to override the deterministic verdict.
It shows models can be useful and still stay bounded in a high-stakes workflow, which is serious engineering for a hackathon build.

Thrilled to share my submission for the @openservai SERV Hackathon 02, built for the @dphnAI Dolphin track: Janus + OpenServ Recovery Copilot.
Janus is a recovery cockpit for Sui handovers. When an administrator transfers control to a successor, an interruption can leave both parties unsure what was approved. Janus restores signed intent from Walrus Memory, verifies live Sui Testnet state through Tatum, and produces a deterministic verdict that blocks unsafe actions.
For the hackathon I added the Recovery Copilot around the real Engine.view() path. Dolphin Network interprets the normalized evidence and drafts source-linked findings. SERV Reasoning turns that interpretation, the same evidence and the deterministic verdict into a structured recovery plan.
The important part is what the models cannot do. Application validation rejects unknown source IDs, fabricated addresses or digests, verdict substitution, inferred approval, fee promises and prohibited wallet actions. The copilot is advisory only. It cannot sign, submit, retry or override the deterministic verdict. Every transaction still goes through the existing wallet review and signing flow.
The cockpit shows verified vs uncertain findings, expandable source evidence, review steps, open questions, provider/model metadata and a stale banner when the operation changes.
What I built during the hackathon:
- Allowlisted RecoveryEvidenceBundle from Engine.view()
- Separate Dolphin and SERV Reasoning adapters
- Strict JSON schemas plus independent application validation
- Durable jobs, deduplication, rate limits, stale detection and restart recovery
- Private participant-only assessments in SQLite
- Recovery Copilot cockpit panel
- Fixture and live Sui Testnet E2E coverage
Evidence so far: 109/109 tests passing, 25/25 copilot tests, 20/20 cockpit browser fixtures, real Dolphin/SERV calls, and an isolated Sui Testnet E2E covering deployment, proposal, successor mismatch, approval, acceptance, stale detection, counter, preference, memory isolation and cancellation.
The live runs also showed why validation matters: SERV once recommended wallet review on a completed handover, and Dolphin once cited a nonexistent source ID. Both were rejected; a bounded retry passed.
The app is local-first and reproducible from the repo, with no hosted app claim. Existing Janus Sui/Walrus/Tatum work is clearly separated from the new OpenServ contribution.
Track: Dolphin
Demo: youtu.be/hfp9qpYCxWI
Repo: github.com/vickman787/janus-…
#SERVHackathon #OpenServ #Dolphin #Sui #Walrus


DCL4385 retweeted

This one’s a really good example of what agents should actually be doing day to day.
You point it at your launch page, it decides which checks are actually worth paying for, buys them in USDC through @GoKiteAI Passport, and comes back with what broke, what got fixed and a receipt for every cent. Under 4 cents for two full runs.
People underrate that receipt part. If an agent spends company money and nobody can see what it bought or why, you can't improve it and you can't justify it to anyone.
Gud tek.

Meet LaunCheck, I sent an AI agent to check my launch page.
It bought browser checks with USDC and brought receipts. @openservai × @GoKiteAI
Our demo: 10 findings → 6 resolved after fixes. $0.035 for both runs.
AI buys the checks. You get the receipts.
Live Beta : launcheck.xyz
How it works :
→ SERV plans which paid checks are worth buying and helps explain recorded findings
→ a Kite Passport agent pays x402 services inside an owner allowance
→ settled purchases show transaction links; unresolved payments stay labelled.
Built for the @openservai SERV 02 Hackathon.
Code: github.com/Story91/launcheck
DCL4385 retweeted
Tonight’s all nighter is unofficially sponsored by the @openservai team.
recognitions like this is why i wont stop showing up.
who’s active & grinding? 👀👀

DCL4385 retweeted
I asked @marianebekker where she’s seeing serious investor interest right now.
Developer tools are raising $50M Series As. That’s how fast the market has changed.
Rome wasn’t built in a day, and empires aren’t built overnight. True infrastructure takes patience.
2+ years of R&D just came together into one unified operating system for AI agents: the $serv platform.
SERV breaks complex jobs into smaller, verified steps so one early AI mistake doesn't ruin the whole task.
That means agents that are up to 100x cheaper to run and reliable enough for major enterprises and governments.
Next up: enterprise security certifications, AWS Marketplace, and scaling serv utility as volume grows.
The foundation is officially here. @openservai
SERV’s tech stack is the result of more than two years of intense AI research and development.
Now everything is converging into one robust agent execution system: the SERV platform.
An operating system for AI agents where every element works has been refined by running production workloads with teams across enterprise, governments and crypto.
Our work has followed one long-term plan from day one, and every stage of the roadmap has moved SERV further along the same trajectory.
Graph Sharding is the next stop, bringing SERV closer to becoming the industry standard for AI agents.
DCL4385 retweeted

I have every confidence that $SERV will scale both web3 and web2 enterprise
2 years of research all coming together solving some of the biggest bottlenecks in #AI
Huge value add for every builder & user, built to scale with real value capture for token
SERV’s tech stack is the result of more than two years of intense AI research and development.
Now everything is converging into one robust agent execution system: the SERV platform.
An operating system for AI agents where every element works has been refined by running production workloads with teams across enterprise, governments and crypto.
Our work has followed one long-term plan from day one, and every stage of the roadmap has moved SERV further along the same trajectory.
Graph Sharding is the next stop, bringing SERV closer to becoming the industry standard for AI agents.
DCL4385 retweeted
SERV.
SERV’s tech stack is the result of more than two years of intense AI research and development.
Now everything is converging into one robust agent execution system: the SERV platform.
An operating system for AI agents where every element works has been refined by running production workloads with teams across enterprise, governments and crypto.
Our work has followed one long-term plan from day one, and every stage of the roadmap has moved SERV further along the same trajectory.
Graph Sharding is the next stop, bringing SERV closer to becoming the industry standard for AI agents.
DCL4385 retweeted
SERV’s tech stack is the result of more than two years of intense AI research and development.
Now everything is converging into one robust agent execution system: the SERV platform.
An operating system for AI agents where every element works has been refined by running production workloads with teams across enterprise, governments and crypto.
Our work has followed one long-term plan from day one, and every stage of the roadmap has moved SERV further along the same trajectory.
Graph Sharding is the next stop, bringing SERV closer to becoming the industry standard for AI agents.
Everything we’ve shipped has been building toward one platform: SERV.
From our first agent SDK to Graph Sharding, each layer made the next one possible, with the orchestration technology from our earlier version multi-agent platform now running at the core of the SERV engine.
SERV Reasoning was the starting point, and the public API is open to every team and builder. With Graph Sharding and the next release, SERV grows beyond a reasoning layer into an agentic execution platform for enterprise AI.
Teams shipping serious agents can map AI workflows, inspect why every decision happens and control how each step runs, the capability regulated industries ask us about most.
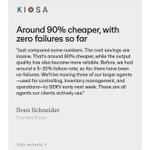
With more than two years of R&D few teams can match, we’ve been solving what keeps AI agents stuck in low-impact environments: reliability, cost and auditability. The result is reasoning that outperforms frontier models at up to 90x lower cost, built for repeat, high-volume agent workloads.
With SOC 2 underway and AWS Marketplace as our first enterprise distribution channel, SERV is on the path to becoming the foundational infrastructure for enterprises running AI agents at scale.
The goal is to put SERV at the center of the agentic AI world and make SERV a household name.
DCL4385 retweeted

Pawlr made it to the featured builds for SERV Hackathon 02
149 submissions in just 2 weeks, and seeing Pawlr highlighted means a lot.
We built Pawlr so AI agents don't keep paying for services that fail to deliver. Every payment is checked, and bad delivery stops the next one.
Thank you @openservai for the feature! ❤️
Fingers crossed for the results 🤞
You can check out pawlr here
pawlr.vercel.app/

DCL4385 retweeted
Robinhood Chain builders keep showing up at every SERV hackathon, which is great to see.
Convik is a full agentic terminal for tokenized stocks. You can see who’s buying, ask why they’re buying, and let an agent take the trade for you.
Agents managing money are going to grow massively in number, but right now they’re still held back by cost and hallucinations. With stakes that high you really need to understand why an agent made each trade.
Agentic trading on the go, with SERV doing the reasoning.

Introducing Convik Terminal.
The agentic terminal for tokenized stocks on Robinhood Chain. See who is buying, ask why, and let an agent trade it for you.
Live now: app.convik.xyz/terminal 🧵
DCL4385 retweeted
Most agent demos show money moving. What I find more interesting is when the agent decides not to pay.
In @0xMemeshe's Tranche, evidence goes through SERV Reasoning, then an independent score from @reppo, then a policy gate, and only then a payment through @GoKiteAI Passport.
A novel use case for SERV: giving agents a principled way to say no before money moves.

Most agent demos show money moving. The useful part is the refusal.
Tranche for @openservai #SERVHackathon (Kite): evidence -> SERV -> @reppo -> policy gate -> @GoKiteAI Passport.
👉 tranche-serv.fly.dev
Source: github.com/PhiBao/tranche
DCL4385 retweeted
Most AI research tools just tell you what you want to hear, which is a problem when you’re actually making decisions based on the answer.
Crux uses SERV to stress-test its own answers, sends the report off to independent @reppo reviewers, and then goes back and rewrites it based on their critiques. In one run it nearly doubled the facts it found and lowered its own confidence because the reviewers turned out to be right.
Being able to inspect the reasoning is what makes that possible, and it’s a big part of what we’re building SERV around.
@myacxt built the first version in our first hackathon and came back with this, love to see it.

introducing Crux v2: research that challenges itself and now learns from independent criticism.
Crux, powered by serv reasoning, researches a question, stress tests its own answer and shows what changed.
new, built on @reppo evaluation api: anyone can send a report to independent reviewers, free, no account needed.
their critiques come back and Crux researches again and writes a better, more honest report.
real run: reppo scored it 65/100 (revise). crux went from 29 to 56 facts, answered 3 of 3 critiques and lowered its confidence because the reviewers were right.
try it: crux.myacxt.site
code: github.com/mhiah/crux
built for #servhackathon reppo track @openservai
DCL4385 retweeted

Great conversation.
Distribution and trust are underrated advantages in building a startup.
Your network can be your biggest competitive edge.
Billions will $SERV
OpenServ presents Build Break Ship.
Our Founder & CEO @open_founder sits down with founders building in AI, starting with @marianebekker.
Is your audience worth more than your AI product?
Worth watching until the very end ↓
DCL4385 retweeted
OpenServ presents Build Break Ship.
Our Founder & CEO @open_founder sits down with founders building in AI, starting with @marianebekker.
Is your audience worth more than your AI product?
Worth watching until the very end ↓

Episode 1 of Build Break Ship is live, presented by @openservai.
@marianebekker grew Founders Bay to 200,000+ members. We get into distribution, trust, fundraising, and why your network is way harder to copy than your product.
Pretty fun one to kick things off, watch it below.