

Founder and CEO of @BeliefMarket_, 승부사 \\ PhD dropout @ NYU, ex-researcher at @HHMIjanelia \\ Founder of @AIFounded
New York City
Joined December 2016
- Tweets3.6K
- Following1.8K
- Followers958
- Likes6.9K




Uh-oh, crypto 🙄
The CLARITY Act expires in January, and Elizabeth Warren is expected to chair Senate Banking


My account @im_daniel_im was compromised and now appears deleted. I’ve submitted recovery and data-access requests without a response. I urgently need retained investor/partnership contact names and usernames. Please route my case to account security/privacy. @SmsTelegram
Im Daniel Im retweeted

Andrej Karpathy dropped a 2-hour masterclass on everything that he knows
It covers:
- Agents
- Harnesses
- Loops
- Graphs
This is a must watch.
Bookmark this post
Im Daniel Im retweeted

Weekend hack: HackerTube. I was annoyed with YouTube's recommendations so I had Claude filter down 43M comments over 20 years of HN to 6,454 videos that keep being recommended. *Significantly* better viewing experience, ~2 hours with Opus 5.5:
hackertube.org/
- Excellent recs without any logins (state is kept in local browser session)
- Thumbnail is a representative frame from middle of the video instead of the super duper A/B test hyper-optimized user uploads
- Underlying data from the comment analysis as one zip file, point your Claude at it and ask for your own version
- HackerTube Longs ✊
A bit more on the process:
I use Claude Code (desktop app for Mac), Opus 5.5 on Medium effort as my default. I only talk to Claude and have it do everything, the only "manual work" I helped with in tandem was in the browser (reminiscent of MenuGen): 1) I had to create some kind of API key from Google Cloud UI to query YouTube for video metadata, 2) I booted up a VPS box for serving and 3) I bought the domain name. Once the box was up I gave Claude the IP and told it update, secure, harden, deploy and optimize the code, and it did the whole thing.
Many awesome projects that would have normally taken weeks/months even can now be few-shotted for breakfast. What else are we not thinking of.


Im Daniel Im retweeted

The strong exponential time hypothesis (SETH) explained by MIT professor @rrwilliams who was selected by OpenAI to verify the recent breakthrough result:
Q: "Could you explain the Strong Exponential Time Hypothesis, or SETH, and its significance?"
Ryan Williams: "Strong ETH is a severe strengthening of the P versus NP question. P versus NP is asking whether the SAT problem has a polynomial-time algorithm or not.
Strong ETH is basically saying that for the SAT problem, you cannot solve it much faster than 2^n. There’s no 1.999^n time algorithm. For every string of 9s, there is no 1.9999^n time algorithm. To say it totally precisely, it has to do with the k-SAT problem, where you’re looking at clauses of length k for arbitrary k, but those details don’t matter so much.
SAT is a canonical NP-complete problem. It’s solved all the time in practice. It’s extremely useful for verification; nowadays it’s an engine for verification. So it can be solved fairly well in practice. However, in the worst case, we still don’t know how to solve it significantly faster than 2^n.
So the hypothesis that it needs, say, 1.99999^n time is a very strong exponential time hypothesis. It’s stronger than P versus NP. It says it’s not just superpolynomial. It’s darn near 2^n time that you need."
Q: "Do you think that hypothesis is true? Why or why not?"
Ryan Williams: "I think I’m on the record as not believing this hypothesis.
Why don’t I believe it? I started thinking about this hypothesis maybe already as an undergrad, but certainly early in grad school. Before it was even called Strong ETH, I guess that shows how old I am. I was trying to figure out how to solve CNF-SAT faster than 2^n.
At the time there were a number of other NP-complete problems that had faster algorithms, like subset sum. So I thought, what’s so special about SAT? If all these other problems have faster algorithms, why not SAT as well?
Even 3-SAT, where each clause is an OR of 3 variables, has a faster algorithm, and this is just a more general version of SAT. So at first I thought there’s no good reason to believe a lower bound. These other related problems have upper bounds, so why not?
But then, over time, I would have different attacks on Strong ETH, always trying to refute it in different ways. These attacks would fail in some completely catastrophic and ridiculous way. They would have no chance of actually solving the original problem.
But by staring at my failure, I’d think: there’s something interesting happening here. It doesn’t refute Strong ETH, so what does it do? By trying to pivot and figure out what I could do with my failure, I was able to solve a variety of other problems instead.
So after a while, I realized that the truth value of Strong ETH to me is almost irrelevant. If I believe that it’s false, then I get good ideas.
By thinking about what an algorithm that breaks 2^n could look like, I force myself to think in a different way. I have to discard the natural algorithmic possibilities, because we know they won’t work, and think in a different direction. Because it sends my brain in a different direction, it’s very useful for research. Even though I still haven’t refuted it, it’s very useful for me to believe that it’s false, operationally."
Q: This is a minority opinion, right?
Ryan Williams: "Russell Impagliazzo, a good friend of mine who helped propose this, always emphasizes to me: this is a hypothesis. We explicitly did not name it a conjecture. We wanted to put forth a lower bound that would get you to think about it, something a little more controversial than P versus NP or other things people more normally believe.
Hypotheses at the edge of our understanding, where we truly don’t know what the answer might be based on our intuition, can be enlightening to think about. That’s one reason why it was proposed.
But one reason you might believe Strong ETH is true is that it conveniently implies a lot of other lower bounds. You can reduce SAT to a bunch of problems that seem totally unrelated, like edit distance and various pattern matching problems. They have natural polynomial-time solutions. If you could improve on the algorithms for any of those, you would improve the one for SAT as well, and get something better than 2^n.
So believing in it makes a convenient worldview. It shows that all these different textbook algorithms are indeed optimal."

Announcing three major scientific discoveries, one each in mathematics (harmonic analysis), computer science (complexity theory), and physics (quantum field theory).
AI starting to help us improve our understanding of the universe! openai.com/index/building-sc…

Im Daniel Im retweeted

So some elaboration on this -
ETH is a much stronger statement than P≠NP. It's a bit surprising that it's not true but it doesn't really break much.
The bounds are technically sub-exponential, but "2^n / complicated log sqrt expression" is still very close to exponential.
Given how well SAT solvers work in practice, and have for decades, some slightly tighter bounds aren't extremely surprising. There are SAT solvers which have been proven to be <O(2^n) for a long time, just with exponents smaller than 2.
What this amounts to is that for any function O(k^n), there's some algorithm that can do better than any value k, if you make n absurdly big. That's a cute result, but we already knew that many NP problems are easier to solve in practice than in theory, and n really doesn't need to be very big for this to be a pretty meaningless statement in practice.
Ultimately though, and this is something I have some unpublished work on myself that I need to get out there soon, the difficulty of NP problems really has dramatically more to do with the structure of the problem than it does the number of variables. You can have small NP problems that are almost as hard as brute force, and you can have others with millions of variables that can be solved quickly. With NP problems in particular, it's clear that the tools we're applying are simply dramatically too primitive to understand what's actually going on.


The computer science collaboration will understand and explain a result concerning the Exponential Time Hypothesis (ETH), a longstanding conjecture about the computational complexity of Boolean formula satisfiability, a problem deeply related to the P vs. NP problem.
Surprisingly, our system has recently proved that the ETH is false, a result that was subsequently verified in Lean.
The refutation of the ETH reopens questions about how much faster these tasks could become, and may help guide the search for better algorithms. Finding such algorithms, and turning theoretical advances into practical improvements, will require significant further research.
Our system found its natural language disproof for the ETH we reached out to to @rrwilliams. Ryan will form a collaboration with Russell Impagliazzo and Ramamohan Paturi to verify and shepherd this result. Impagliazzo and Paturi, along with Francis Zane, are the original proposers of the Exponential Time Hypothesis, and Williams has refuted strong versions of the ETH, used ETH for hardness results, and connected algorithms and lower bounds.
This group asked us to make all raw data of the results public to facilitate independent verification by the community, which we have done by posting the natural language proof and Lean formalization to our GitHub repo. The group also invites the community to help organize an open examination of the ETH claim and to discuss the broader questions that AI-generated breakthroughs raise about verification, access, credit, and the future of research.
github.com/openai/math/blob/…

P=NP coming soon? 🙄😳
"The computer science collaboration will understand and explain a result concerning the Exponential Time Hypothesis (ETH), a longstanding conjecture about the computational complexity of Boolean formula satisfiability, a problem deeply related to the P vs. NP problem. The ETH has been widely believed to be true, and has been used in hundreds of papers to derive conditional computational hardness results across a wide variety of fields including graph theory, computational biology, databases, computational geometry, and more. Surprisingly, our system has recently proved that the ETH is false, a result that was subsequently verified in Lean."

Im Daniel Im retweeted

Daniel is this our official uniform 😂
Thanks for having us, @SuperteamTH 💜

Come with me next time 😂
Was at @SuperteamTH’s open house last night.
You can leave the blazer at home.
Thanks everyone for asking me about @BeliefMarket_

Im Daniel Im retweeted

Hi all, I have a new result I'm excited to share. It turns out that *all existing implementations* of softmax and cross-entropy (that's JAX, PyTorch, textbooks, etc) have a subtle bug --- two bugs, actually. A simple rewrite fixes both, and eliminates "slingshots" when grokking:
Come with me next time 😂
Was at @SuperteamTH’s open house last night.
You can leave the blazer at home.
Thanks everyone for asking me about @BeliefMarket_
Im Daniel Im retweeted

We formally announced Mirendil less than 4 months ago. Today, I'm excited to share an important milestone for:
Pretraining at scale without a pretraining team.
Mirendil's mission is to solve Recursive Self-Improvement (RSI) and use it to democratize frontier AI development, ultimately accelerating science and technology. At Mirendil, when we think about RSI, we think holistically about the company as an intelligent entity that self-improves toward its goal. From that perspective, the most powerful notion of acceleration is reducing the time and resources (number of human experts, compute, and other costs) needed to achieve ambitious goals.
Given that pretraining is perhaps the most important yet most challenging part of frontier AI development, we decided to run an ambitious controlled experiment: Starting fully from scratch, can we significantly reduce the time, number of human experts, and compute resources needed to go all the way to successfully pretraining a strong coding model at scale?
Mirendil-Base is the result of this experiment. Our first pretrained model was built by one researcher in 3.5 months, with less than $10M in compute. This includes all the research and small-scale experiments it took to get there, as well as the final training run.
The recipe holds up as the models get bigger. For reference, Mirendil-Base is in the 100B-500B parameter range, Mirendil-Base-Large in the 500B-2T range, and Mirendil-Base-XL in the 2T-10T range.
We're beginning to see a world where a single researcher, empowered by AI, can take on work that once required an entire research organization. As these systems improve, the bottleneck shifts from the size of a team to the ambition and judgment of the people directing them. This has profound implications for who gets to build AI and, ultimately, who gets to push the frontiers of science and technology forward.
We’ll share independent evaluations, post-training benchmarks and API-access sooner than you think so stay tuned!

Im Daniel Im retweeted

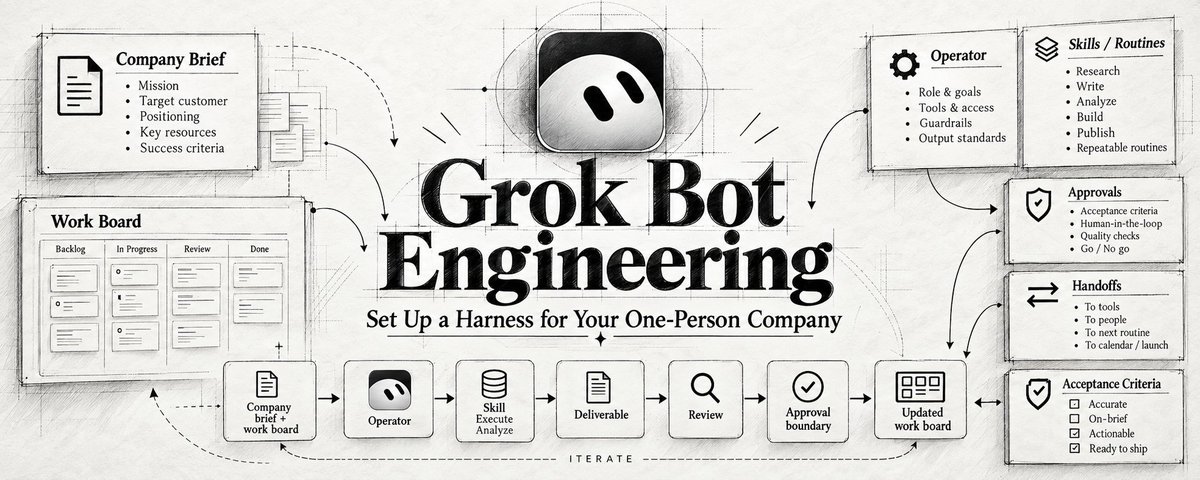
This is f*king insane. SpaceXAI engineer, Lauren Tan:
"I'm running 30+ GrokBot agents with /loop, /goal, inside pstack. My bots shipping code even when I sleep
at SpaceXAI, 90% of our engineers running 10+ GrokBot agents as a team. I have a Chief of Staff agent, it knows other agents and manages everything"
in a 1-hour workshop, a SpaceXAI engineer revealed how to build a team of GrokBot agents from scratch
worth more than a $650 agentic engineering course
watch today, then read the article on how to build a team of GrokBot agents from scratch

You know when you meet someone at a conference,
forget to tell them what i do 😂
Hope you check my profile later 😂


Ppl think AI is the singularity but i think it is not.
i don't think AI is the final thing. it is only suboptimal solution due to energy scarcity.
Over the long period, i believe that , ultimately, we all gonna be living in matrix where
only brains remain biological and minds are digital…
Founders, what are you stuck on?
I am solving how to convert visitors to sign in.
Have some traffics to our app.
They click log-in button, and hesitate.
Now need to convert to registeration.
The first orientation day, representing @BeliefMarket_ in @ProtocolCamp Cohort 10.


Protocol Camp marked the start of Cohort 10 at Next Builders during KBW.
The recap looks back at the event and the 11 teams introduced as part of this edition.
@0xShardLab @hashed_official
