

recovering R-addict, dataholic, visual-maniac, so rather plain person
Dallas, TX
Joined September 2018
- Tweets261
- Following100
- Followers107
- Likes382




Integrating RAGChecker metrics in Inspect-ai tasks linkedin.com/pulse/integrati… via @LinkedIn

14
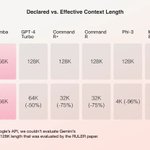
Context window is one of key LLM features, but what vendors declare almost never the same as effective context length. Check out this graph showing @AI21's #Jamba's declared vs. effective #contextwindow

22
GregoryKanevsky retweeted

Hack by popular demand!
Open-Source Agent #Hackathon with @AndrewYNg & @DeepLearningAI at @agihouse_org Saturday, *August 24th*
Stellar schedule planned w/ secret guest speakers, alongside co-hosts, @GroqInc & @langchain.
Reserve your spot now --> eu1.hubs.ly/H0bJRt70

GregoryKanevsky retweeted

📽️ New 4 hour (lol) video lecture on YouTube:
"Let’s reproduce GPT-2 (124M)"
youtu.be/l8pRSuU81PU
The video ended up so long because it is... comprehensive: we start with empty file and end up with a GPT-2 (124M) model:
- first we build the GPT-2 network
- then we optimize it to train very fast
- then we set up the training run optimization and hyperparameters by referencing GPT-2 and GPT-3 papers
- then we bring up model evaluation, and
- then cross our fingers and go to sleep.
In the morning we look through the results and enjoy amusing model generations. Our "overnight" run even gets very close to the GPT-3 (124M) model. This video builds on the Zero To Hero series and at times references previous videos. You could also see this video as building my nanoGPT repo, which by the end is about 90% similar.
Github. The associated GitHub repo contains the full commit history so you can step through all of the code changes in the video, step by step.
github.com/karpathy/build-na…
Chapters.
On a high level Section 1 is building up the network, a lot of this might be review. Section 2 is making the training fast. Section 3 is setting up the run. Section 4 is the results. In more detail:
00:00:00 intro: Let’s reproduce GPT-2 (124M)
00:03:39 exploring the GPT-2 (124M) OpenAI checkpoint
00:13:47 SECTION 1: implementing the GPT-2 nn.Module
00:28:08 loading the huggingface/GPT-2 parameters
00:31:00 implementing the forward pass to get logits
00:33:31 sampling init, prefix tokens, tokenization
00:37:02 sampling loop
00:41:47 sample, auto-detect the device
00:45:50 let’s train: data batches (B,T) → logits (B,T,C)
00:52:53 cross entropy loss
00:56:42 optimization loop: overfit a single batch
01:02:00 data loader lite
01:06:14 parameter sharing wte and lm_head
01:13:47 model initialization: std 0.02, residual init
01:22:18 SECTION 2: Let’s make it fast. GPUs, mixed precision, 1000ms
01:28:14 Tensor Cores, timing the code, TF32 precision, 333ms
01:39:38 float16, gradient scalers, bfloat16, 300ms
01:48:15 torch.compile, Python overhead, kernel fusion, 130ms
02:00:18 flash attention, 96ms
02:06:54 nice/ugly numbers. vocab size 50257 → 50304, 93ms
02:14:55 SECTION 3: hyperpamaters, AdamW, gradient clipping
02:21:06 learning rate scheduler: warmup + cosine decay
02:26:21 batch size schedule, weight decay, FusedAdamW, 90ms
02:34:09 gradient accumulation
02:46:52 distributed data parallel (DDP)
03:10:21 datasets used in GPT-2, GPT-3, FineWeb (EDU)
03:23:10 validation data split, validation loss, sampling revive
03:28:23 evaluation: HellaSwag, starting the run
03:43:05 SECTION 4: results in the morning! GPT-2, GPT-3 repro
03:56:21 shoutout to llm.c, equivalent but faster code in raw C/CUDA
03:59:39 summary, phew, build-nanogpt github repo

If you're a developer, this is probably the first chance you'll get to hack using a model that was developed with Mamba. Prizes include up to $5K in credits to build apps with Jamba on AI21 Studio (and lots of fun swag too!). Come meet the AI21 team and hack with us.
16
Come join @AI21Labs #Jambathon at the @AGIHouseSF on June 22nd to hack away with Jamba, the groundbreaking fusion of Mamba and Transformer architectures.
agihouse-app.web.app/events/…
1
38
Upgrade pip
> pip install --upgrade pip
Install Python
> pyenv install -s 3.10.13
Remove virtual env
> pyenv virtualenv-delete [virtual-env-name]
1
63
Git
remove local branches after they were deleted in remote repo likely by closing PRs :
> git fetch --all -p; git branch -vv | grep ": gone]" | awk '{ print $1 }' | xargs -n 1 git branch -d
36
All while the virtual environment is active.
Export installed packages into requirements.txt:
> pip freeze > requirements.txt
Uninstall a package <pkg_name>
> pip uninstall <pkg_name>
1
62
Using pyenv + virtualenv :
> pyenv versions # to list python versions, once
> pyenv virtualenv [python version] [virtual env name] # create virtualenv, once
> pyenv activate [virtual env name] # each time
> pip install -r requirements.txt # once
> pyenv deactivate # each time
1
78
pyenv + virtualenv :
> pyenv versions (once)
> pyenv virtualenv <desired python version> <virtual env name> (once)
> pyenv activate <virtual env name> (every time)
> pip install -r requirements.txt (once)
> pyenv deactivate (every time)
1
118
GregoryKanevsky retweeted

Artificial Intelligence: The Good, The Bad and The Ugly - Free public lecture on May 24 by Professor Abu-Mostafa of @Caltech to explain the science of AI in plain language and assess extreme scenarios.
work.caltech.edu/watson
#MachineLearning #ArtificialIntelligence #AI #chatGPT


