

Astro+ML @jodrellbank @OfficialUoM. she/her
Manchester, England
Joined July 2012
- Tweets77
- Following463
- Followers136
- Likes2.6K



Devina Mohan retweeted

TMLR has refocused its acceptance criteria to place more emphasis on clear writing. Read more in this blog post: medium.com/@TmlrOrg/increasi…

Devina Mohan retweeted

The (true) story of development and inspiration behind the "attention" operator, the one in "Attention is All you Need" that introduced the Transformer. From personal email correspondence with the author @DBahdanau ~2 years ago, published here and now (with permission) following some fake news about how it was developed that circulated here over the last few days.
Attention is a brilliant (data-dependent) weighted average operation. It is a form of global pooling, a reduction, communication. It is a way to aggregate relevant information from multiple nodes (tokens, image patches, or etc.). It is expressive, powerful, has plenty of parallelism, and is efficiently optimizable. Even the Multilayer Perceptron (MLP) can actually be almost re-written as Attention over data-indepedent weights (1st layer weights are the queries, 2nd layer weights are the values, the keys are just input, and softmax becomes elementwise, deleting the normalization). TLDR Attention is awesome and a *major* unlock in neural network architecture design.
It's always been a little surprising to me that the paper "Attention is All You Need" gets ~100X more err ... attention... than the paper that actually introduced Attention ~3 years earlier, by Dzmitry Bahdanau, Kyunghyun Cho, Yoshua Bengio: "Neural Machine Translation by Jointly Learning to Align and Translate". As the name suggests, the core contribution of the Attention is All You Need paper that introduced the Transformer neural net is deleting everything *except* Attention, and basically just stacking it in a ResNet with MLPs (which can also be seen as ~attention per the above). But I do think the Transformer paper stands on its own because it adds many additional amazing ideas bundled up all together at once - positional encodings, scaled attention, multi-headed attention, the isotropic simple design, etc. And the Transformer has imo stuck around basically in its 2017 form to this day ~7 years later, with relatively few and minor modifications, maybe with the exception better positional encoding schemes (RoPE and friends).
Anyway, pasting the full email below, which also hints at why this operation is called "attention" in the first place - it comes from attending to words of a source sentence while emitting the words of the translation in a sequential manner, and was introduced as a term late in the process by Yoshua Bengio in place of RNNSearch (thank god? :D). It's also interesting that the design was inspired by a human cognitive process/strategy, of attending back and forth over some data sequentially. Lastly the story is quite interesting from the perspective of nature of progress, with similar ideas and formulations "in the air", with a particular mentions to the work of Alex Graves (NMT) and Jason Weston (Memory Networks) around that time.
Thank you for the story @DBahdanau !


Devina Mohan retweeted

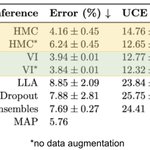
🤔 Variational learning is often thought to be impractical
🔥 Plot twist: it actually works better than Adam!
Meet IVON, a new optimizer that brings the best out of variational learning – 🧵 (1/9) #NLProc #ICML2024
📰 arxiv.org/abs/2402.17641
youtu.be/TRNYnRRJBRg
Devina Mohan retweeted

Some thoughts/ideas, "pêle-mêle" as we say in French, about VI and MCMC after attending #ProbAI.
statmodeling.stat.columbia.e…
Devina Mohan retweeted

Three scientist mothers call for a change in how conference childcare costs are reimbursed, drawing on their personal experiences go.nature.com/3X03rLo
Devina Mohan retweeted

.@eccvconf reviews are out and the official notification email points to a blog @deviparikh, @stefmlee, and I wrote a few years ago for our students.
Glad to see that our lab style is spreading to the community :-).
deviparikh.medium.com/how-we…

Devina Mohan retweeted

I’m offering a deep-learning PhD project with my colleagues @sun_mingfei & @JuliaHandl : Combinatorial Optimisation on Graphs for Science Operations in Radio Astronomy ✨📡💻 Get in contact if you are interested! #AI4Astro – at Manchester, England
Devina Mohan retweeted

This is my attempt to convey how unreasonable and unimaginably large #NeurIPS2023 is. Wild.


Devina Mohan retweeted
With awesome collaborators, I'm super excited to share another contribution to the @ML4PhyS workshop at #NeurIPS2023! It's pretty much all in the title: "Bayesian Imaging for Radio Interferometry with Score-Based Priors"! 🎉🎉
🧵arxiv.org/abs/2311.18012

Devina Mohan retweeted

Double #NeurIPS2023 #ML4PS arxiv day!
I think the future of @galaxyzoo is to go beyond classification. Here's two steps towards that.
1) Deep learning segmentation of bars and spirals in DESI, with @DrAshleyNova 🦾
arxiv.org/abs/2312.02908
@NeurIPSConf
@ML4PhyS

Devina Mohan retweeted

We recently held the JBCA internal symposium organized by our postgraduate committee. They did a great job. Thanks to the @SKAO for hosting the meeting! Also to Phil Black for the group photo.

Devina Mohan retweeted
Postdoc call!
Lead a new project using deep learning to investigate galaxy morphology in Hubble, JWST, and Euclid.
walmsley.dev/postdoc
Work alongside the ESA data science team in Madrid, Spain. And come visit me @UoT!
#eas2023 #easkrakow2023 #nam2023 @esa @galaxyzoo

Postdoc opportunity - work with me - Mike Walmsley
Solving interesting problems with data
walmsley.devThis Post is from a suspended account. Learn more
Devina Mohan retweeted
This figure took me too long to make for me not to show ... I also gave a talk. 🙃
Thanks @turinginst and the @NHM_London for hosting this great Turing Fellows meeting!
If you want to know more about "Reducing labelling costs by deriving semantic class targets" reach out! 😄

Devina Mohan retweeted
Do you, like me, do everything last minute?
If so, it's now time to hurriedly write your abstract for the #NAM2023 ML session - due Monday!
It's been (yet another) big year for ML. I'm curious to see how our astroML community has adapted.

The server is humming and the abstracts are racing in for #NAM2023. Make sure yours is amongst them before 1300hrs (UTC) on Monday!!

Devina Mohan retweeted
We used AI to make astronomy more accessible! Not through #GPT4
but by finding plain English terms to be used as a proxy for some of the more confusing technical terminology in our field! manchester.ac.uk/discover/ne…
Devina Mohan retweeted
Ever thought about the language we use in science? Should we be challenging it? Come dive into my latest work accepted at the #ml4phys @NeurIPSConf. 🎉
arxiv.org/abs/2210.14760
A thread 🧵1/6

Devina Mohan retweeted
Good morning #NAM2022!
Interested in ML? Here's the schedule and abstracts for the ML sessions, techniques2/3 - mwalmsley.github.io/nam-ml
Thanks @AstroSunnyC, @t_killestein for helping with this!
@nam2022warwick
Devina Mohan retweeted

SARAO has released a new MeerKAT telescope image of the centre of our Galaxy, showing radio emission from the region with unprecedented clarity and depth. Read more: cutt.ly/aI77faR #MeerKAT #radioastronomy #heartofthegalaxy


