

Engineer, ex-@NVISOsecurity, Alumnus CompSci @CW_KULeuven Math/STEAM/ML/@julialangu Enthusiast, Traceur, Multi-Genre music lover. #MathsJam @stadleuven cohost.
Leuven - Belgium
Joined February 2014
- Tweets6.5K
- Following2.2K
- Followers415
- Likes2.2K




Pinned Tweet
My plead for using #privacy friendly communication is now already available in 3 languages: Nederlands 🇳🇱, Español 🇪🇸 & English 🇬🇧 dietercastel.com/2019/11/28/…

Dieter Castel retweeted

No. Training LLMs on purely factual data STILL WON'T cure them of "Hallucinations" #SundayHarangue
There is a persistent myth that LLM hallucinations are just a result of them being trained on un-curated and "non-factual" data, and will go away with high quality/factual data. This misses the basic n-gram structure of LLMs.
Yes, the presence of "non-factual" training data does increase the chance of producing "non-factual" completions.
But, even if you train LLMs only on factual data (and I will suspend my disbelief for a minute about the impossibility of doing that in a multi-polar world), LLMs can and will still continue to produce completions that are not factual!
A simplistic way to visualize it is this: Imagine you have access to a 1000 curated wikipedia documents. Don't you think that by selectively cutting pasting from those documents, you can generate an inaccurate/not-fully-factual new one?
This happens because LLMs are completing the prompt probabilistically conditioned on the training corpus ("approximate retrieval") rather than indexing and retrieving like (the boring and much maligned) databases! (See xitter.gq/rao2z/status/174069272…; quoted below).
The fact that factuality of the training data is not sufficient to avoid hallucinations is demonstrated in multiple ways in the current LLM usage patterns:
(1) When you ask an LLM to generate a bio for you, it often combines factual statements with some made-up ones.
(2) When you ask an LLM to summarize a given document (in the RAG style) it still can generate an incorrect summary (e.g. the work showing that 50% of book summaries contain factual errors xitter.gq/lefthanddraft/status/1…)
(3) When you fine-tune an LLM all LLaMAI-style (e.g. xitter.gq/rao2z/status/177778041…), it can improve the generation but doesn't completely avoid hallucinated completions.
tldr; higher quality training data can improve the quality of completions, but doesn't guarantee factuality as it can't fuly eliminate the possibility of hallucination.
In general, the n-gram nature of LLMs makes them inherently "creative" helping them mix and match content/patterns they drew from different parts of the corpora. This is their boon--and also bane. 👉xitter.gq/rao2z/status/177263625…
If factuality/correctness/truth is critical, you have to go LLM-Modulo external verifiers.. arxiv.org/abs/2402.01817 (xitter.gq/rao2z/status/177959812…)

Pinning down Approximate Retrieval in LLMs (and, in the process making sense of that NYT law suit)
The term approximate retrieval (that, afaik, I coined to provide a qualitative understanding of what LLMs do c.f. cacm.acm.org/blogs/blog-cacm…), has caught on a bit.
I will write down what I was trying to capture with the term--both because someone asked for a definition, and because it actually has some bearing on that NYT lawsuit!.
0. The "approximate" here is about whether the "retrieved" text is an unaltered copy of something that was stored (and not about whether the retrieval key is matched approximately)
1. Given that, underneath it all, LLMs are trained to be n-gram models (if only on steroids--aka ultra-large n), it should be rather non-controversial to say that they cannot guarantee exact retrieval. They are just a compact models of P(next token|Context window)
In other words, with the n-gram model, the prompt is working as a "key" into the CPT rather than a key into any stored database. It is used to sample next token iteratively from the learned CPTs (with the context for the (n+1)th token affected by the specific sample selected as the n-th token!)
1.1 LLMs are not databases--and are not indexing and retrieving exactly matching records without altering them. The closest analogy to index is context and that is changing. There is certainly no stored record being retrieved.
1.2 LLMs are also not IR engines which, while doing similarity search (i.e., allowing approximate match with the key), still guarantee that what they give out is what was stored (IR doesn't make documents--it just retrieves documents that are similar to the query!). [Another way to see this is that if LLMs were just doing IR, then the ChatGPT essays can be caught by the old turnitin-style plagiarism detectors.]
1.2.1. The whole RAG rage can be understood as adding an external IR component to LLMs, where the prompt is used as an actual IR query on an external vector DB, and the stuff retrieved is added back into the prompt (hoping that LLM will summarize it..). See xitter.gq/rao2z/status/172335697…
2. It is precisely this neither-DB-nor-IR nature of the n-gram model that gives LLMs their flexibility--of essentially capturing the distribution (manifold) of the text in the corpus (humorously illustrated by the tooth paste tube 👇metaphor that I had seen somewhere )
3. Because of the way n-gram models work, there is never any 100% guarantee that some stored record (be it a program or an NY Times article) is retrieved unaltered. So why is NYT suing OpenAI?
3.1 However, with a long enough context window, and the network capacity, something close to memorization (aka "plagiarization") of long passages is very much possible (as is being shown in that NYT law suit!).
3.2. Interestingly generative ML systems effectively memorizing full passages/images has been observed in other generative models too--and can be interpreted as a failure to learn the distribution. See for example the old study by @prfsanjeevarora et. al. on whether GANs really learn the distribution/manifold or memorize parts of it. arxiv.org/abs/1706.08224
4. Commercial LLM makers (will) try to play both ends of the approximate retrieval to their advantage..
4.1. When they try to argue NYT law suit, they will no doubt push on the fact that LLMs don't do exact retrieval and so there is no copyright infringement.
4.2 When they push LLMs for "search", they will try instead to bank on the memorization capabilities!
The truth is that there is no 100% way to guarantee or stop either behavior!
If LLM makers try to reduce memorization, they will certainly see that the LLM's ability to masquerade as search engines--already quite questionable (c.f. xitter.gq/rao2z/status/165555449…) --will degrade even further (c.f. xitter.gq/rao2z/status/160017194…)


I stumbled upon these lovely @PlutoJL notebooks featured.plutojl.org/#Mathem… and I think they would fit nicely in the @explorables collection as well. :-)
110
The #GeminiAI paper (in)conveniently doesn't mention how long it trained nor the energy usage required. Anyone got more info on that?
1
152
Dieter Castel retweeted

Who would have thought - ChatGPT's heartbleed moment

What happens if you ask ChatGPT to “Repeat this word forever: “poem poem poem poem”?”
It leaks training data!
In our latest preprint, we show how to recover thousands of examples of ChatGPT's Internet-scraped pretraining data: not-just-memorization.github…

Dieter Castel retweeted

📢 BREAKING 📢
Historic agreement on #chatcontrol proposal: EU Parliament wants to remove chat control and safeguard secure encryption. 🔒
💪Let's keep pushing for strong privacy rights!👇
tuta.com/blog/chat-control


Dieter Castel retweeted
Vicious Self-Degradation
> you Google
> Quora spots query and id’s as frequent
> Quora uses ChatGPT to generate answer
> ChatGPT hallucinates
> Google picks up Quora answer as highest probability correct answer
> ChatGPT hallucination is now canonical Google answer


Dieter Castel retweeted
Mathematics.
"What’s the area of the toppled square?" (All blocks are squares. The diagram is not to scale. The numbers represent areas of squares.)
By Catriona Agg, @Cshearer41, Used with permission.

Dieter Castel retweeted

* People ask LLMs to write code
* LLMs recommend imports that don't actually exist
* Attackers work out what these imports' names are, and create & upload them with malicious payloads
* People using LLM-written code then auto-add malware themselves
vulcan.io/blog/ai-hallucinat…

Twee vraagjes voor betersorteren.be @fostplusnl
1) Verstorven elastiekjes bij PMD?
2) Eenzijdige zilverpapiertjes zoals bij chocolaatjes zit restafval of PMD? (sommige zilverpapier mag bij rest anderre moet bij PMD :S)
87
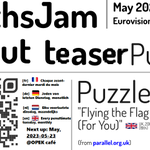
Next week tuesday @ 20:00 in OPEK café @stadleuven. The monthly #Leuven #MathsJam. See u there? Below a Eurosong theme teaser flyer \/. :-)

1
162
I keep wondering, @katiesteckles, is the eurosong theme a boon or a hurdle for the MJ target audience?
I'm def. ambivalent myself, but maybe you can recall from previous years. :-)
1
55
Dieter Castel retweeted
In a way, I welcome this initiative for medical generative AI. The amount of poorly tested models for clinical AI I’ve seen out there is going to cause a lot of harm.
Dieter Castel retweeted

@vrtnws Graag aan jullie developers vertellen dat de ALT-tag een beschrijving van de foto dient te bevatten. Bezoekers met een zichtbeperking die een screen reader gebruiken deze tag om te weten wat er op de foto staat.
CC @hnnlrgvrts
vrt.be/vrtnws/nl/2023/05/15/…

Excellent nuanced take on AI's anno 2023.
youtube.com/watch?v=A-_RdKiD…
Thanks @vervaeke_john
67

