

LLM inference, optimization & large-scale serving for RL training pipelines @hcompany_ai. Previously built on-device voice ML libraries @Sonos.
Paris, France
Joined June 2019
- Tweets139
- Following292
- Followers87
- Likes443




2022 me was actually cooking
github.com/sonos/tract/pull/…

25

Repo if you want to try it: github.com/ai-dynamo/snapsho…

41
Really cool work from @DecagonAI, especially the on policy drafter automated finetuning !
Curious about the benchmark workload and how much training data was needed to get there 🤔


3
102
Link to the slides: drive.google.com/file/d/1a6v…
49
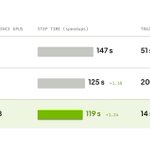
Counterintuitively, we used more inference GPUs (8 to 14.8 on average).
But the trainer kept 32 H100s allocated throughout. Cutting rollout wait from 51s to 14s/step saved more GPU-time than the additional inference workers consumed.
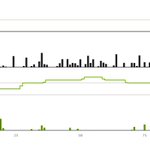
Training curves below 👇

1
2
63
Request-based autoscaling couldn't see the trainer waiting for slow rollouts, even when workers were below their load target.
So we implemented a custom controller that uses worker load, latency, trainer wait time, and GPU cost to estimate the optimal inference fleet size.

2
2
73
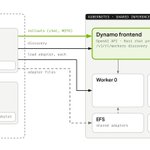
We decoupled inference from training and moved rollouts to a shared, autoscaled inference fleet powered by NVIDIA Dynamo.
This gave us:
- session-aware routing for better KV-cache reuse
- fast worker startup with ModelExpress (11.1 to 2.6 min)
- the flexibility to scale inference independently of training

1
3
100
With prime-rl, we had to choose the inference GPU count before each RL run and keep it fixed. Too few GPUs left the trainer waiting for rollouts, too many wasted compute.
We wanted to scale inference during a run, without touching the trainer.
1
3
166

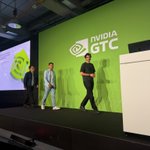
Great time speaking at NVIDIA GTC Berlin about post-training open-source models with Prime-RL and Dynamo!
I shared some of the optimizations we' e made at @hcompany_ai to speed up training and improve inference efficiency.
Thanks to everyone who joined and for the great discussions afterward! 🚀


1
13
218
Heading to NVIDIA #GTCBerlin this Thursday!
Catch our talk on using RL + NVIDIA Dynamo to ship open models as production agents at H Company alongside NVIDIA & Prime Intellect.
Session details: nvidia.com/en-eu/gtc/session…
Let’s grab a coffee if you're in town! ☕️

Excited to chat with @NVIDIAAI this Thursday about how we are using Dynamo to scale VLM serving for computer-use agents at H !
Looking forward to the discussion and live Q&A! 🚀

Live with @NVIDIAAI this Thursday: how we serve vision-language models for computer-use agents.
Thu Oct 8 · 1PM CEST / 7AM ET
With @AvshalomM (inference team lead) and @EmrickSini (research engineer). Live Q&A.

Emrick retweeted

Call for London based runners 🏃
@hcompany_ai is organising a short run followed by breakfast on Oct 16 - bring your friends, colleagues, dogs and let's sweat a bit!
Today we're releasing the Holo4 model family.
Once again, we've pushed the Pareto frontier of capability vs. cost per task for computer-use agents.
A few of the things that made this possible:
• We scaled our environments and built an Agentic Task Factory that has generated ~10k verifiable tasks across web, desktop and MCP environments
• We further improved our SFT and asynchronous online RL infrastructure to train efficiently and reliably on long horizon agentic tasks
• We expanded beyond pure GUI interaction: Holo4 can click, code, call MCP tools and APIs, choosing the right interface for the task
More details below 👇

Emrick retweeted
New party alert - Sep 22, Paris 🪩
@hcompany_ai is teaming up with @bfl_ai and @modal to throw a casual get together ahead of the @aiDotEngineer conference organised by @MistralAI !
There will be drinks, food, smart folks, and all of this by the Seine!
