

Making agentic workflows hallucination and poison free powered by our verifiable databases and cryptography tools.
Switzerland
Joined April 2024
- Tweets233
- Following87
- Followers360
- Likes1.4K






3/4
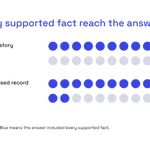
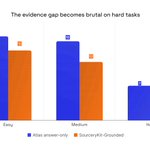
How many answers included every supported fact?
• Conversation alone: 12 of 24
• With the organised record: 14 of 24
Two more complete answers. A preliminary result, not proof of higher overall accuracy.

4/4
Recovering information is only part of the job. We also need to check whether it reaches the answer.
SourceryKit makes that gap checkable.
Read the experiment:
switchboard.provably.ai/blog…

6/7
One hard task followed a chain from a museum to its architect, his birthplace, a library and the nearest subway.
Guided recovery found evidence for all five expected claims.
The final answer still omitted them.
Finding the evidence isn’t the same as using it.
7/7
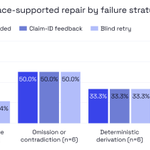
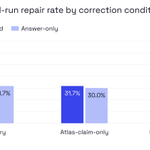
Of 32 guided runs that recovered complete evidence, only 11 also passed the final-answer check.
The next challenge: getting that evidence into the answer.
These were selected failures, weighted toward missing tool evidence.
provably.ai/blogs/the-trace-…

Provably retweeted

anthropic.com/research/multi…
This is fantastic read.
1. agents struggle to coordinate with each other especially for common resources.
2. they don't know how to detect when they are being lied to.
And as usual Anthropic wants to solve it through more learning..


We believe agents should capture evidence natively as they work.
SourceryKit captures tool calls in a state of the art verifiable database, allowing agents to evaluate themselves and downstream agents to independently verify their answers.

SourceryKit detected 100% of the covered deterministic grounding errors in this study.
Next, we will test how much accuracy agents can recover through answer healing and targeted retries.
Read the study:
provably.ai/blogs/The-Agent-…
