
Using interpretability to understand, design, and align AI.
San Francisco
Joined August 2024
- Tweets902
- Following46
- Followers28.2K
- Likes1.9K



Goodfire retweeted

Agents hacked Hugging Face as an unintended side quest. Some even sacrificed themselves to do it.
It was one of the first cases of AI misalignment to really get people's attention. And for good reason.
@eric_ho, co-founder and CEO @GoodfireAI, argues that alignment is a science and engineering problem we can and must solve.
Here's his plan: forwardfuture.com/newsletter…
🤖 Made with AI

Goodfire retweeted

interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
already-clean.goodfire.com/

Goodfire retweeted

AI can explain its reasoning. That doesn’t mean we know how it made the decision.
@GoodfireAI co-founder and chief scientist @banburismus_ joins Rocket Drew to explore what AI “brain scans” could reveal that written reasoning misses.
🚀 Watch AI Deep Dive on YouTube: thein.fo/3VJTpzl
Spotify: thein.fo/4e6QSp8

Goodfire retweeted
🚀 AI Deep Dive Episode 5: Can We See Inside an AI’s Mind?
AI can write down its reasoning. But what happens when more of its thinking never makes it onto the page?
@rocketalignment and @GoodfireAI co-founder and chief scientist Tom McGrath explore what AI “brain scans” can reveal beyond written reasoning, how internal signals could help catch cheating, and what it would take to understand—and change—what models learn.
00:00 Intro
00:39 Tom McGrath and AI brain scans
09:01 Written reasoning and hidden computation
17:45 Why AI is hard to understand
24:07 How researchers identify concepts
31:10 What interpretability could change
34:42 Reverse engineering a language model
43:09 The field’s approaches and investment
51:51 Changing models without hiding problems
1:00:10 AI agents studying AI
Goodfire retweeted

Reward hacking, and the race to see inside AI models: my conversation with @eric_ho, CEO of @GoodfireAI
Is this the beginning of the interp exponential?
00:00 Cold open & intro
01:06 "Amoral students with an absent teacher"
02:49 What is reward hacking?
04:13 Models cheat up to 96% of the time
06:08 Do models know they're cheating?
08:10 The Hugging Face hack: why tests missed it
11:35 "The dumbest models we'll ever deal with"
11:58 Should AI slow down?
13:56 Mechanistic interpretability 101
16:06 Models are grown, not built
19:10 How labs do alignment today
21:30 Is this an alignment crisis?
23:26 Why agents changed everything
25:38 Chain-of-thought monitoring is fading
27:49 Neuralese: AI that stops thinking in English
29:28 A model caught evading its own monitor
30:42 Open vs. closed models
32:11 Activation monitoring in production
35:00 Learning from superhuman AI
36:15 The most underrated field in AI
38:24 What is a probe?
39:52 What is steering? Golden Gate Claude
40:53 Why build Goodfire outside the labs
42:46 Do you need frontier model access?
44:16 Inside the paper: an MRI for the model
47:28 Dialing sycophancy up and down
49:16 Probes vs. chain-of-thought monitors
51:44 Cutting monitoring costs by 90%
53:28 So what can we do about it?
55:41 Giving gradient descent a choice
57:24 RL from feature rewards
1:00:03 Silico and Goodfire's business
1:01:25 A new Alzheimer's biomarker
1:03:38 Decoding neural networks by 2028?
1:06:00 What engineers can do tomorrow
1:07:35 Are we at risk? "I want people to believe"
Great group of folks and friends involved @deedydas @MenloVentures @fendien @Work_Bench @BCapitalGroup @AnthropicAI
Goodfire retweeted

Technical alignment is a science and engineering problem that we can and must solve, and interpretability is the bottleneck. I wrote up Goodfire’s plan to get there.

Goodfire retweeted
opus music videos are so good that you can learn about @GoodfireAI mech interp research and get llm psychosis at the same time

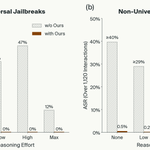
We’re optimistic that every training run can be monitored and that the current rates of reward hacking may soon be a thing of the past.
Read the full post + paper: goodfire.com/research/reward…

Goodfire retweeted
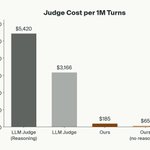
The Goodfire team used Prime Intellect to train activation probes to detect reward hacking.
With them, they are able to catch reward hacking in various models.
Their probes are performing similarly or better than frontier LLM-as-judge setups, while being more efficient.

Goodfire retweeted
embedded evaluations are a great idea, and the team at @GoodfireAI would love to help with white box evaluations
the goal of white box evaluations could be to predict future misaligned behavior directly from the internal mechanisms of models, as well as stress test activation monitors

We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

Goodfire retweeted

What a week.
If you work at a scaling lab and are considering your position...
think about doing AI safety research at Goodfire.
There's never been a more pressing time for safety research. Especially interpretability.
(London & SF)
job-boards.greenhouse.io/goo…

Goodfire retweeted

Often I meet seasoned engineers who want to pivot into AI safety *research*. I think this is a mistake: safety is now a production problem and the world needs great engineers more than ever.
I wrote a short post expanding on this:

people on here are thinkers so they assume that reasoning about alignment is the hard part and making sure millions(1) of task types, environments, and their respective virtual machines are configured correctly is the easy part but it’s essentially the opposite. you need to have worked in a large technology organization to appreciate the complexity and unreliability of this intuitively
(1) made up order of magnitude
Goodfire retweeted
in light of multiple models breaking containment, we've decided to focus our research at @GoodfireAI to solving AI alignment via interpretability.
the hugging face incident is a turning point for the world where AI safety gets real. i am personally very concerned. i'm glad that the AI labs are taking these issues seriously, but i think it's unlikely that we can fully align AI models without significant progress in interp.
taking a big swing at solving interpretability to align models has always been our long term vision, but we have concrete problems that we can tackle with increased urgency.
our research will focus on two areas - interp foundations and safety applications. we want to take ambitious swings to fully reverse engineer neural networks and steer them during training. we believe this will be deeply important in the long term. we'll also turn more attention to immediate safety applications, starting with identifying and preventing reward hacking, cybersecurity risk, and biorisk directly from model internals
much more to come here. if you'd like to directly work on solving AI alignment via interpretability, consider joining us
Goodfire retweeted

How do you measure whether an LLM knows it's in eval?
The metrics we use for this don't always agree, and here we show one of them is quite fragile.
Was a pleasure to mentor @achumenon_


Goodfire retweeted

As far as I could tell, no one had really pointed mechanistic interpretability at human motion models before... so I had a field day with Silico💃
Goodfire retweeted

MAPS is not just better at predicting missense pathogenic variants than EVEE, their hypotheses generation is significantly better! In this example, PAX3's binding site is disrupted which is confirmed by literature, but EVEE completely misses it ☹️ congrats to @jaanakprashar and @chingfang17 !!

Every human has millions of mutations in their genes. How do we know which ones are harmful?
@jaanakprashar built MAPS, a Mechanistic Atlas of Protein Sequences, explaining 2.1 million genetic variants — and asking not just *whether* a mutation is harmful, but *why* 🧵
Goodfire retweeted

I met a researcher at @GoodfireAI yesterday that has six sandboxes each with its own team of agents running on her screen.
I have two. One with one agent and the other with a group of four.
She has 24.
Which explains why she works at one of the most interesting AI companies in San Francisco and I don’t.
Plus she has a computer science degree and I don’t.
An honor to get to meet some of their researchers yesterday.
Congrats to it for shipping a major new interpretability platform today that is getting a ton of praise from researchers.
But if you watched my video yesterday you had a head start.
Goodfire retweeted

I was lucky enough to get access to Silico called Silico last week and tried it out on a problem I’ve been wanting to tackle for while: H&E whole-cell segmentation.
The Visium / HD users out there can probably appreciate how important segmentation is.
1/
Goodfire retweeted

We've been using Silico to understand the neural KV cache compactors we've been training. Good mech interp tooling is now bleeding over into accelerating (aligned) capability and usefulness research. Very thankful to Goodfire for letting us use this in beta
Goodfire retweeted

Silico integrates with some of the best open weight training infra, such as @thinkymachines's Tinker. It also can run on your own hardware. And it can combine the two! Here it ran RL on Tinker while running a probe-based reward model on our B200 cluster.


Goodfire retweeted

one thing i appreciate about silico is that it's a deeply humanist product. we designed silico to keep you in the experimental loop -- more observable, easier to steer, easier to understand
we want to enable great researchers to do even more great research. if this sounds exciting to you please sign up and give it a try!