

We build Research-driven infrastructure for enterprise-grade private LLM inference and GenAI systems.
AI
Joined July 2025
- Tweets27
- Following70
- Followers80
- Likes32




Pinned Tweet
👀 We are live on @ProductHunt
InferiaLLM is an operating system for LLMs.
From raw LLMs to real users - routing, RBAC, policies, and compute built in.
Upvote and support is highly appreciated.
producthunt.com/products/inf…

InferiaLLM v0.1.0 beta 1 is live
A unified platform to deploy, manage, and secure LLM inference at scale with orchestration across clouds and DePIN, built in guardrails, RAG pipelines, access control, and deep observability.
Supports vLLM, Ollama, OpenAI compatible APIs, and more from a single control plane.
From deployment preflight checks to audit logs to multi credential infra to hardened security, this is a full stack infra layer for serious AI teams.
pip install inferiallm==0.1.0b1
docker pull inferiaai/inferiallm:v0.1.0 beta 1

3
258
Enterprises don’t struggle with models.
They struggle with operating them.
We integrated NVIDIA Nemotron into InferiaLLM in a way that makes production deployment radically simple:
1. Spin up Nemotron →
2. Attach safety policies →
3. Enable observability →
4. Scale across workloads →
All from a single control layer.
No fragmented pipelines.
No patchwork guardrails.
No manual orchestration.
InferiaLLM acts as the AI Operating System:
• Model abstraction layer
• Traffic routing & load balancing
• Guardrail Engine (LLM Guard, Llama Guard, Lakera)
• PII detection & compliance enforcement
• Structured logging & monitoring
Nemotron provides the intelligence.
InferiaLLM makes it enterprise-ready.
This is what “production AI” actually looks like.
@nvidia @NVIDIAAI @NaderLikeLadder @ctnzr @Baxate
Website: inferia.ai
Demo: youtu.be/BPXIf__NPWs
Github: github.com/InferiaAI/Inferia…
#NVIDIAGTC #EnterpriseAI #Nemotron
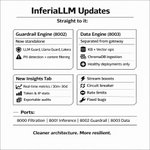
InferiaLLM v1.1 updates - straight to it:
• Guardrail Engine (8002) → now standalone
- Supports LLM Guard, Llama Guard, Lakera
– PII detection + content filtering
• Data Engine (8003) → separated from gateway
– KB + vector ops
– ChromaDB ingestion
– Only healthy deployments visible
• New Insights Tab
– Real-time metrics (30m–30d)
– Token throughput + avg rate
– IP filtering + top IPs
– Deployment-level analytics
– Exportable audit data
• Stream processing → better token throughput
• Circuit breaker for external calls
• Rate limiting on auth
• Unified HTTP config + shared schemas
Ports:
8000 Filtration |
8001 Inference |
8002 Guardrail |
8003 Data |
Cleaner architecture. More resilient.

1
3
217
Check us out on Product Hunt:
producthunt.com/products/inf…
1
1
115
Spent the last few weeks tightening Inferia - an OS for running private LLM inference in production at scale. Shipped governance, routing, and observability into one system. Applied to YC.
Back to building.
inferia.ai

Inferia AI retweeted
👀 We are live on @ProductHunt
InferiaLLM is an operating system for LLMs.
From raw LLMs to real users - routing, RBAC, policies, and compute built in.
Upvote and support is highly appreciated.
producthunt.com/products/inf…
👀 Pre-release is live
InferiaLLM is an operating system for LLMs.
From raw LLMs to real users - routing, RBAC, policies, and compute built in.
Launching on Product Hunt tomorrow 🚀

Product Hunt → producthunt.com/products/inf…
Live tomorrow. Feedback from infra & ML folks welcome 🙏
🚨 Heads up, builders
We’re launching InferiaLLM on Product Hunt in 3 days.
It’s an operating system for running LLMs in production - in-house, scalable, and opinionated.
If you care about real LLM infra, this one’s worth bookmarking 👀

LLMs are powerful.
But power without control breaks in production.
Something is coming for teams running LLMs at scale. Stay tuned.
InferiaLLM
The Operating System for LLMs in Production
⏳
We at @InferiaAI are excited to submit our BUIDL for the @nosana_ai Builder Challenge.
Nosana Chat MCP lets anyone deploy LLMs or any containerized application on Nosana using natural language — no complex setup or commands needed. Just connect your wallet, have some NOS and SOL for compute and payments, and let Nosana Chat MCP do the rest.
🔗 Try it: lnkd.in/g_YT4THS
🎥 Demo: lnkd.in/gX_CASzE
We’re proud to contribute to the future of decentralized compute — making AI deployment as simple as having a conversation.

2
261
RT @nosana_ai: The Future of AI Deployment: Making Innovation Faster and Simpler xitter.gq/i/broadcasts/1mnxeNbXq…
We are live...

AI deployment shouldn’t take weeks.
Today at 5PM CET, we go live with @inferiaAI to show how you can deploy any model in under 60 seconds, powered by Nosana’s decentralized GPU network.
Set a reminder!
xitter.gq/i/broadcasts/1BdxYZzMB…

1
383
Countdown’s on — just 1 hour to go.
See you all at 5PM CET
AI deployment shouldn’t take weeks.
Today at 5PM CET, we go live with @inferiaAI to show how you can deploy any model in under 60 seconds, powered by Nosana’s decentralized GPU network.
Set a reminder!
xitter.gq/i/broadcasts/1BdxYZzMB…
The future of AI deployment is here and we’re building it in collaboration with @nosana_ai.
Join us at 5PM CET.
We’re going live with @inferiaAI tomorrow at 5PM CET🚨
Join us to explore what’s changing in AI deployment and hear real insights from builders.
Watch here on X and LinkedIn.
Set a reminder:
linkedin.com/events/thefutur…

Excited to join this conversation with @nosana_ai next week.
For us at Inferia, deployment isn’t just about speed — it’s about giving builders confidence that their models can scale, stay open, and run on reliable decentralized infra.
Looking forward to sharing what we’ve been building and hearing from the community.
📅 Don’t miss it.
We’re going live with @inferiaAI next week to talk about something every builder cares about: deployment.
We’ll unpack what faster, simpler deployment means for devs and how decentralized infra is reshaping AI.
📍Live on X, September 11th, 5PM CET

Learn how to deploy DeepSeek-R1 on Inferia in minutes — production-ready, OpenAI-compatible API.
👉 Learn more: inferia.ai/blog/how-to-deplo…
Powered by @nosana_ai

232