
Research @ OpenAI | prev @princeton_rl @citsecurities
sf
Joined June 2023
- Tweets42
- Following287
- Followers3.1K
- Likes2.5K





Pinned Tweet
Excited to share that our paper "1000 Layer Networks for Self-Supervised RL: Scaling Depth Can Enable New Goal-Reaching Capabilities" has won the Best Paper Award at NeurIPS '25!
Hope to see you all in San Diego :)

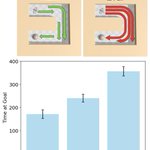
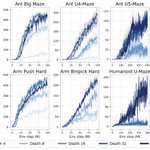
1/ While most RL methods use shallow MLPs (~2–5 layers), we show that scaling up to 1000-layers for contrastive RL (CRL) can significantly boost performance, ranging from doubling performance to 50x on a diverse suite of robotic tasks.
Webpage+Paper+Code: wang-kevin3290.github.io/sca…
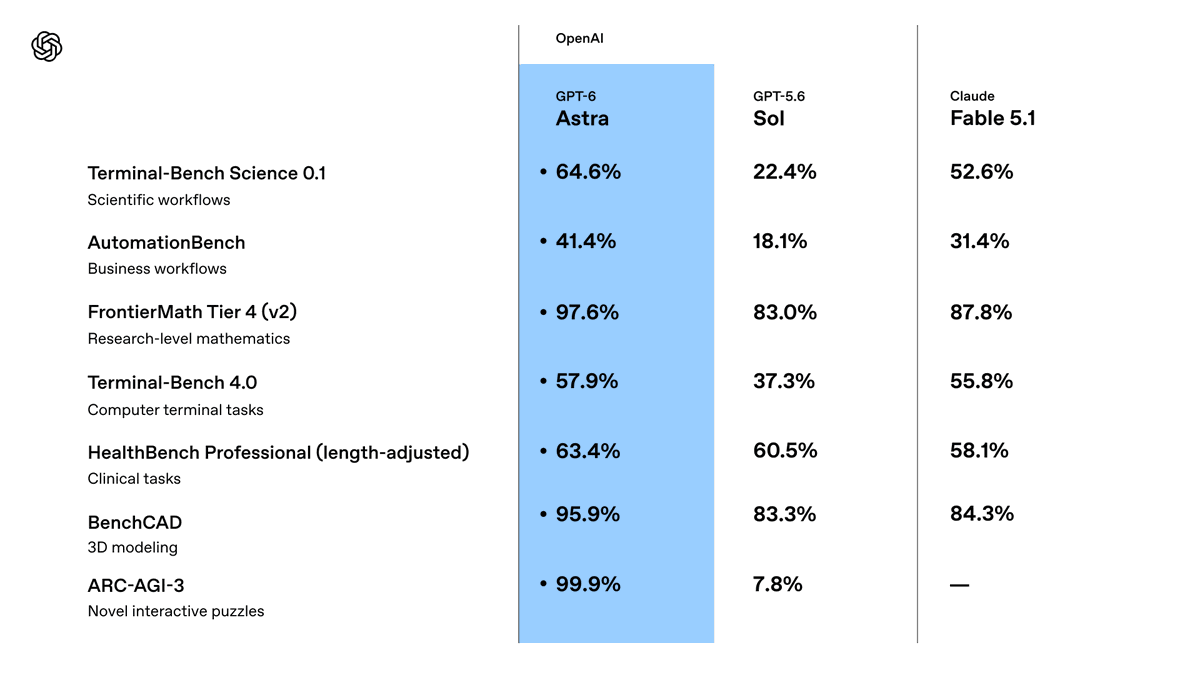
In Astra, we made significant progress on subjective domains like design aesthetics and knowledge work. It’s been a blast developing new methods for training on non-verifiable domains. Excited for this line of work and what’s coming next. Go try out Astra when you can! :)


Kevin Wang retweeted

An internal version of Astra, @OpenAI’s next major model family, solved 10 major open problems in mathematics, quantum complexity, and theoretical computer science.
We believe it will be a major step for scientific reasoning. openai.com/index/ten-advance…


Kevin Wang retweeted
Introducing GPT-5.5
A new class of intelligence for real work and powering agents, built to understand complex goals, use tools, check its work, and carry more tasks through to completion. It marks a new way of getting computer work done.
Now available in ChatGPT and Codex.


Happy to share that our work “1000 Layer Networks for Self-Supervised RL: Scaling Depth Can Enable New Goal-Reaching Capabilities” was accepted to #NeurIPS2025 as an Oral Presentation!
Grateful to my amazing collaborators @IJ_Apps @m_bortkiewicz @ben_eysenbach 🥳
1/ While most RL methods use shallow MLPs (~2–5 layers), we show that scaling up to 1000-layers for contrastive RL (CRL) can significantly boost performance, ranging from doubling performance to 50x on a diverse suite of robotic tasks.
Webpage+Paper+Code: wang-kevin3290.github.io/sca…
1/ While most RL methods use shallow MLPs (~2–5 layers), we show that scaling up to 1000-layers for contrastive RL (CRL) can significantly boost performance, ranging from doubling performance to 50x on a diverse suite of robotic tasks.
Webpage+Paper+Code: wang-kevin3290.github.io/sca…
8/ One negative result: In preliminary experiments using OGBench, we evaluated depth scaling in offline goal-conditioned RL. We found that increasing network depth didn’t improve offline performance, hinting that its benefits online may partly arise from enhanced exploration.
9/ Thanks to amazing collaborators @IJ_Apps, @m_bortkiewicz @tomasztrzcinsk1, and @ben_eysenbach. Please check out our paper and website for more details!
Paper: arxiv.org/abs/2503.14858
Website: wang-kevin3290.github.io/sca…
Code: github.com/wang-kevin3290/sc…
