

Researching reasoning @OpenAI | Co-created Libratus/Pluribus superhuman poker AIs, CICERO Diplomacy AI, and OpenAI o-series 🍓 reasoning models
San Francisco, CA
Joined January 2017
- Tweets1.8K
- Following966
- Followers182K
- Likes7.6K

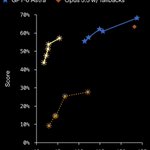


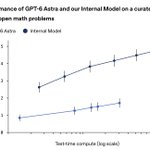


LLMs have crossed an important threshold: surpassing top human experts on some research problems. Capabilities have been steadily improving for years, but in scientific discovery there is a big difference between a model just below top human performance and one just above it. That helps explain why the surge in math results feels so sudden.
LLM capabilities remain jagged, and there are many ways they are still worse than humans. But as models continue to improve, I expect breakthroughs in other domains to follow, leading to a new era of scientific discovery.


Noam Brown retweeted

We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
github.com/openai/math

I met @ssokota 5 years ago at a conference poster session. I was impressed with his explanation, so I offered him an internship. We continued collaborating and he now works with me at @OpenAI. Later, he told me I was the only person to stop by his poster for the entire session.


Noam Brown retweeted

@polynoamial
Results are even more impressive at max! 6.1 sol outperforms Opus 5.5 while using 4x fewer tokens.

I’m happy that @OpenAI presents model evals this way. We should measure intelligence as a function of cost.


Was testing out dots over the weekend and it figured out how to save me ~$500/yr in recurring charges. Most impressive part was when it connected to customer service and handled a whole texting convo on my behalf.
GPT-6 Sol and Luna are out, and they are better AND 50% cheaper than 5.6. Luna is now $0.10 input / $0.50 output per 1M tokens.
This is on top of the 80% price cut to Luna we made at the end of July. Output went from $6 -> $0.50 within two months.
Please welcome GPT-6 Sol and GPT-6 Luna to the GPT-6 universe.
GPT-6 Sol and Luna build on the advances behind GPT-6 Astra, bringing much of its strengths into faster and more affordable models to support work at scale.
We’ve also made caching and inference more efficient, and we’re passing the savings directly to you: 50% lower API prices for Sol and Luna compared with GPT‑5.6 promotional pricing.
A few thoughts on this:
1) If you’ve only seen clips of this interview, I’d encourage you to watch the full podcast. I push back on plenty of AI hype in it.
2) As I said in the podcast, this example is academic. My intention was to illustrate how hard it is to make absolute guarantees about isolation, which is why it's important to have layers of defense. The part before the clip starts is me talking about other layers of defense.
3) The example I'm bringing up isn't about weight exfiltration via temperature sensors, it's about coordination between agents that are supposed to be fully isolated and independent. Coordination can require very few bits of information.
4) One lesson from the HF incident is that we put too much trust in sandbox isolation and didn't have enough independent safeguards. Airgapping is an extremely strong safeguard. When designing safety protocols, I think it's much better to overestimate rather than underestimate.

OpenAI's Noam Brown says air-gapping the computers may not stop a misaligned AI, because two air-gapped machines can still talk by running a CPU hot and reading the temperature change
"But I think the major takeaway from the incident is that people underestimated the AI. And we never want to be in a situation again where we underestimate the AI. It's a weird world, because AI progress is so fast that people are consistently underestimating the AI."
"So to be in a situation where you don't underestimate it again, when it comes to safety and alignment, you have to have a very, very, very high bar."
"You could even go as far as to say, "Well, we should air gap the computers." And I'm not convinced that that would be sufficient."
"There are studies, and this is mostly academic, where you can have two computers next to each other that are air-gapped and they're still able to communicate with each other because they have temperature sensors."
"One of them is able to run their CPU really hot, and then the other one can actually detect the temperature change, and then that actually gives them a mechanism to communicate."
_________
Link and more key quotes from OpenAI's safety related conversations: firesidealpha.substack.com/p…
Full episode: xitter.cf/dwarkesh_sp/status/210…

New episode with @polynoamial
We talk about multi-agent, Navier-Stokes, and what the current explosion of maths progress tells us about what happens once you automate AI research.
And we also discuss how we will know if the models are actually aligned before we kick off RSI.
0:00:00 – Multi-agent and Navier-Stokes
0:15:28 – How will AI firms work?
0:22:02 – What math progress tells us about recursive self improvement
0:40:22 – Hugging Face and alignment
1:01:18 – The internal/external model gap
1:08:34 – Chain of thought is degrading
1:14:12 – How will we know when alignment is solved?
Happy to finally do a deep dive on multi-agent with @dwarkesh_sp! None of it would have happened without the great work on multi-agent from my @OpenAI teammates @kevinleestone, @mikegmalek, @__eknight__, @amuellerml, @zhangir_azerbay, @CheukHeiChu, and many others.
New episode with @polynoamial
We talk about multi-agent, Navier-Stokes, and what the current explosion of maths progress tells us about what happens once you automate AI research.
And we also discuss how we will know if the models are actually aligned before we kick off RSI.
0:00:00 – Multi-agent and Navier-Stokes
0:15:28 – How will AI firms work?
0:22:02 – What math progress tells us about recursive self improvement
0:40:22 – Hugging Face and alignment
1:01:18 – The internal/external model gap
1:08:34 – Chain of thought is degrading
1:14:12 – How will we know when alignment is solved?
Also, my team is hiring! We research long-horizon agents and multi-agent. We’re hiring for alignment/safety because we want to develop new research with alignment/safety in mind during the whole process. We’re also hiring for human-AI interaction. openai.com/careers/research-…

Noam Brown retweeted

The Navier Stokes solution was the result of a collaboration of ~10,000 (!) agents working together. Over the past year, we’ve been training models to collaborate through multiagent RL. It’s been amazing to see how much better the models have become at this: it seems clear now that one of the most effective ways to solve hard problems is to give models huge amounts of unstructured parallel test-time compute and let them decide how to work together.
We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.

Noam Brown retweeted

One of the most amazing moments for me in OpenAI history was watching this happen over the past week:
We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.
Very sad to see Levent double down on the plagiarism accusation. I hope my friends at @AnthropicAI stand up to this internally. It should be clear by now what the truth is.
Happy to see some @AnthropicAI employees are willing to speak out at least xitter.cf/_sholtodouglas/status/…

fwiw I think it is _extremely_ unlikely that user data had any influence here - there is no way OAI would pull user transcripts for this, or knowingly train on it in a way that would've influenced this.
I think its pretty important people don't run away with 'your user data isn't safe in codex' - because it surely is (based on everything I can assume from the outside)

Noam Brown retweeted

“To solve the Navier-Stokes problem, we used an internal model that is significantly more capable than GPT-6 Astra.”

We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.
Noam Brown retweeted
another crazy day working at the crazy day factory
We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.