

Currently at Google Research. PhD in Reinforcement Learning from the Technion. Main research interests include Reinforcement Learning and Large Language Models
Joined November 2019
- Tweets59
- Following128
- Followers138
- Likes89


Lior Shani retweeted

We're excited to share our new paper: "Personalized and Sequential Text-to-Image Generation"!
Check out the paper and our new sequential human rater dataset! 👇
Paper: arxiv.org/pdf/2412.10419
Dataset: kaggle.com/datasets/googleai…
Details below..
1/N 🧵
Excited to share our latest research on aligning Large Language Models (LLMs) with human preferences! We're moving beyond single-turn interactions to improve multi-turn conversations.
arxiv.org/abs/2405.14655
Joint work by @GoogleResearch @GoogleDeepMind
(1/8)

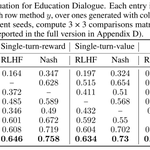
Experimental results showing MTPO outperforms single-turn RLHF baselines and a multi-turn generalization of RLHF. This demonstrates the effectiveness of our approach in improving the quality of multi-turn conversations.
(7/8)

1
2
152
Check out our paper for more details on how we're pushing the boundaries of RLHF for more natural and effective multi-turn conversations!
arxiv.org/abs/2405.14655
@LiorShan @aviv_rosenberg @AsafCassel
(8/8)

1
116
Lior Shani retweeted

Check out our paper here: arxiv.org/pdf/2205.15376.pdf
Code can be found here:
github.com/guytenn/Terminato…
And of course, thank you to everyone who collaborated with me on this project: @NadavMerlis, @LiorShan, @shiemannor, @ShalitUri, @GalChechik, Assaf Hallak, and @DalalGal.
(9/n)
n=9
Glad to present our paper "Online Apprenticeship Learning" at #AAAI2022
arxiv.org/abs/2102.06924
with @TZahavy @MannorShie
We show how to efficiently reproduce experts' behavior from an offline data of trajectories, by interacting with the MDP (when rewards are not specified).
We show our approach is both theoretically efficient and practical: we provide regret guarantees and show how to avoid solving an MDP at each iteration as in prior works. This allows us to devise a well-performing deep RL implementation of our (OAL) algorithm.
1
Lior Shani retweeted
teleporting, swimming with sharks, and lots more. It turned out better than I've ever expected!
Now, before releasing it out to the world, I'm looking for a partner that can help me market the game properly. You can help me out by retweeting!
Promo:
Lior Shani retweeted
Ludwig @Princeton Director Joshua Rabinowitz, a pioneer of metabolomics, has contributed to the development of a cancer therapy & undone enduring assumptions about metabolism. His work is opening new approaches to cancer therapy. Learn more: https://xitter.gq/t.co/yCUXGwtqpy

Come chat today at the deep RL workshop @NeurIPSConf!

Overall, MDPO is an easily scalable policy optimization algorithm with minimal hyper-params/heuristics involved, and is nicely grounded in mirror descent theory :)
Joint work with @LiorShan, Yonathan Efroni, Mohammad Ghavamzadeh
Come chat on Dec 11, 11:30 am PST!
4
Applying Mirror Descent in deep RL is nice and easy!
slideslive.com/38941342/mirr…

Overall, MDPO is an easily scalable policy optimization algorithm with minimal hyper-params/heuristics involved, and is nicely grounded in mirror descent theory :)
Joint work with @LiorShan, Yonathan Efroni, Mohammad Ghavamzadeh
Come chat on Dec 11, 11:30 am PST!
4
Prof. Shie Mannor is presenting our work at the great RL theory seminar this Tuesday! The talk will be about the connections between TRPO and convex optimization, possible practical implications and how to explore in policy optimization...

Our next talk:
06/09: Shie Mannor (Technion)
"Adaptive Trust Region Policy Optimization: Global Convergence and Faster Rates for Regularized MDPs"
For details, please see the website:
sites.google.com/view/rltheo…

Prof. Shie Mannor is presenting our work at the great RL theory seminar this Tuesday! The talk will be about the connections between TRPO and convex optimization, possible practical implications and how to explore in policy optimization...

Lior Shani retweeted

"Tight Lower Bounds for Combinatorial Multi-Armed Bandits"
Recent work by @NadavMerlis and Shie Mannor was accepted to #COLT2020 !
Read their paper here: arxiv.org/abs/2002.05392