

All-in-one Physical AI Data Service Platform
Joined April 2026
- Tweets42
- Following23
- Followers75
- Likes5





Pinned Tweet
𝟭,𝟬𝟬𝟬,𝟬𝟬𝟬+ 𝗵𝗼𝘂𝗿𝘀 𝗼𝗳 𝗿𝗲𝗮𝗹-𝘄𝗼𝗿𝗹𝗱 𝗱𝗮𝘁𝗮. 𝟮𝟬,𝟬𝟬𝟬 𝗠𝗘𝗴𝗼 𝗱𝗲𝘃𝗶𝗰𝗲𝘀.
Today marks a major milestone for Maniformer.
And this is just the beginning.
#Maniformer #MEgo #PhysicalAI #EmbodiedAI


Nanjing was busy this week, and we’re glad @Maniformer could be part of the 2026 Physical AI & World Models Conference. Thank you to everyone who stopped by to share ideas. Looking forward to the next one! #PhysicalAI #EmbodiedAI #Robotics


Congratulations to the @dreamlabs_ai team on this exciting milestone. We can’t wait to continue the journey in embodied AI together!

Today, Dream Labs is coming out of stealth with Dream-1, a robot foundation model that controls bimanual robots it has never seen, on tasks it was never shown, in places it has never been, from $3/hour.
Dream API is live for everyone, today. 🧵
Appreciate the detailed review of #MEgoVista!
The missing link between human activity and robot learning is often usable motion data. MEgoVista is an important part of our journey to build an end-to-end platform for Physical AI.

A robot can't learn from a video it can't measure.
@Maniformer , the world’s leading physical AI data platform. Its new paper scores a person's hands to 4.29 mm of finger error and their head to between 0.65 and 2.83 mm, checked against a 26-camera motion capture lab.
Teaching a robot on a real robot is slow, because every hour of teleoperation uses a machine, an operator and an environment reset. Putting a camera on a person scales with the number of people instead, which is why egocentric datasets have grown from hundreds of hours to thousands.
But video only shows what someone did. To turn it into robot actions, you need the hand's 3D position in real units. The wrist path goes through inverse kinematics and the fingers get retargeted to the robot's hand, so supervision is only as good as the hand pose underneath it. The paper's complaint is that datasets carrying those labels were shot in studios or on prepared tabletops, and where labels are released, the accuracy is asserted from hardware specs instead of measured.
When I toured Maniformer's headquarters, the data collection centre showed the same problem from the other side. One room runs more than a hundred robots at once, and right beside them people in motion-capture suits perform the same tasks by hand so the robots can learn how a human moves. Maniformer's bet is to take the robot out of that loop.
The system is called MEgoVista, and it runs on MEgo View, a head-mounted rig with fisheye cameras at 60 fps and an IMU sampled at 500 Hz. One unprepared recording goes in. Both hands and the head come out in a single gravity-aligned world frame. Three design choices carry it.
First, depth is measured instead of guessed. Most existing methods get depth from a single camera with a learned model, so scale is a prior that shifts from frame to frame, and the error sits along the viewing ray where reprojection can't correct it. Here the central camera pairs with each side camera, stereo runs across the wide baseline, and because that baseline is calibrated, the metre comes from the hardware. Scale is fixed once, at initialisation.
Second, it knows whose hands are whose. A detector decides at detection time whether each hand belongs to the wearer or a bystander. In the manicure clip the wearer's left hand touches another person's left hand, and both Dyn-HaMR and HaWoR credit the bystander's hand to the wearer. HaPTIC produced no valid output on the multi-person scenes at all. Dyn-HaMR's detection precision came out at 0.73, while MEgoVista scored 1.00 precision and 1.00 recall.
Third, it solves the whole sequence instead of frame by frame. A per-frame estimate can look plausible alone and still jitter, drift in depth, or pass through a pose a real hand can't make. MEgoVista optimises one hand trajectory across the full episode with limits on joint range and angular velocity, and lands at 1.11 mm/frame² of jitter against 3.50 for the smoothest baseline.
Then comes the scoring, which is the part I found most interesting. Everything was measured against a 26-camera, 120 Hz Chingmu motion-capture system. The protocol charges the method for any hand it declines to predict, and it screens the reference data itself for solver glitches before trusting it.
Finger articulation error is 4.2 mm, against 16.30 mm for HaWoR and 49.18 mm for Dyn-HaMR. Absolute wrist position error is 14.30 mm against 46.70 and 184.38. On head tracking, DROID-W suffered severe scale failures on 4 of 22 episodes and MASt3R-SLAM underestimated scale on 21 of the 22, while MEgoVista stayed within a few millimetres and ran about 3x and 3.5x faster on roughly 40 second episodes.
One honest note on that last comparison. ORB-SLAM3 was more accurate on one of the two capture sessions, 2.12 mm against 2.83 mm. On the other session MEgoVista won, 0.65 mm against 0.92 mm. The paper reports both, so I will too.
The other limit is where the millimetres were measured. They come from inside a motion-capture lab. In the wild there is no ground truth, so the evidence is visual: milk tea preparation with heavy hand occlusion, washing a pet with soiled hands, mold maintenance in industrial gloves, and a working restaurant. The authors also say any error left in the mocap hand reference is charged to their own system, and that slow drift in that reference would slip past their checks.
Maniformer says it has collected over 1 million hours of data and delivered the 20,000th MEgo device on August 31. If that scale holds, labels measured against a reference matter more than hours alone. The paper ends by saying it is undecided whether the next millimetre needs a better estimator or a better reference, which is a rare sentence for a company to publish about its own system.
Full paper: arxiv.org/abs/2609.16684

Wrapping up our debut at #CIIF!
We showcased MEgo Series—our physical AI data collection and data platform powering real-world robot learning.
Honored to receive the 2025 @Forbes_china New Intelligence Award. Onward for physical AI!


Great breakdown! Better data makes more capable robots. Thanks for sharing our #MEgoVista research🙏

Everyone talks about smarter robots.
But here’s the real challenge: How do you teach a robot to perform human tasks in the real world? 🤖
The answer starts with data.
That’s what makes @Maniformer work interesting.
They’re building a one-stop data infrastructure for Physical AI, bringing together 3 key sources:
→ Real-world data: How robots perceive and interact with their environment
→ Simulation data: Scalable synthetic data to train and improve models
→ Human demonstration data: Real human movements that help robots learn complex skills
But what really caught my attention is their MEgoVista research
It reconstructs 3D hand and head movements from first-person recordings, reporting 4.29 mm finger articulation error against motion-capture ground truth.
Why does this matter?
Because a robot doesn’t just need to recognize what a human is doing. It needs to understand the movement well enough to learn how to do it itself.
And scaling that process could be a major step toward more capable robots.
Better data → Better learning → More capable robots.
Physical AI is more than just building better hardware. The data behind it matters just as much.
Explore MEgoVista research: arxiv.org/abs/2609.16684

Video shows what happened, not how the hands moved. For robots learning from human demos, that's the missing piece.
Discover our new paper: how #MEgoVista reconstructs 4D hand and head motion from egocentric video.
📄 arxiv.org/abs/2609.16684


Building robots that need better data?
Join us to meet our team and learn more about our Physical AI data platform, spanning data collection hardware, software systems, and datasets for robotics and embodied AI. See you at CIIF 2026!
#CIIF2026 #Robotics #PhysicalAI

Maniformer is at IROS 2026! 🤖
We’re here showcasing our #MEgo Series for real-world data collection and exploring the latest developments in Physical AI with the global robotics community.
Come visit us at Booth 829! 👋
#IROS2026 #Robotics #HumanoidRobots #EmbodiedAI

It was great to connect with the AI and robotics community at the @Tsinghua_Uni Artificial Intelligence Youth Conference and exchange ideas on how real-world data can help advance Embodied AI.
#Maniformer #MEgo #EmbodiedAI #PhysicalAI #Robotics #TsinghuaUniversity #UMI


@Maniformer will be at the Tsinghua Artificial Intelligence Youth Conference in Beijing, China!
Hosted by @Tsinghua_Uni University, we're bringing our AI data collection hardware and software. See you there 👋
#Robotics #AI #PhysicalAI #Maniformer #TAIYC2026

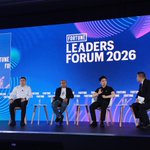
“Physical AI will also follow a scaling law.”
At the Fortune Leaders Forum 2026, Dr. @MaoqingYao highlighted the critical role of data in scaling Physical AI. As data and training scale, robots could generalize across more tasks and increasingly work “out of the box.”


Maniformer made its @IFA_Berlin debut this year, with the #MEgo Series,our human-centric data collection devices, receiving the 2026 Global Product Technology Innovation Award – All-Scenario Data Collection Technology Innovation Award.
#PhysicalAI #DataForAI

🤗What a great few days at @IFA_Berlin 2026!
This was Maniformer‘s first time showcasing at IFA, and we were thrilled to see so many customers and industry professionals stop by our booth.
Thanks to everyone who stopped by. Great meeting you in Berlin, see you next time!


Witnessing the delivery of our 20,000th #MEgo device!
From MEgo View for multi-view, multimodal sensing to MEgo Gripper for wireless UMI data collection in the wild, the MEgo family is helping scale high-fidelity real-world data collection across diverse tasks and environments.


Our first @IFA_Berlin . See you in Berlin!
Maniformer will be exhibiting at #IFA2026 for the first time.
From data collection to management and evaluation, we’re building an end-to-end data service platform for Physical AI. Let’s connect!
#PhysicalAI #Robotics #Maniformer

@Maniformer CEO Dr. @MaoqingYao joined @nvidia’s Physical AI & Robotics Partner Day, exchanging insights with Madison Huang, Spencer Huang, and industry leaders on the future of Physical AI.
Thank you to the NVIDIA team for bringing together such an inspiring community!


🙌Great to see #MEgo series in action at World Robot Conference 2026 in Beijing!
With MEgo View and MEgo Gripper, we’re building new ways to capture rich visual, motion, and tactile data from real-world interactions to advance Physical AI.

I tested out the egocentric headset with wrist camera + UMI gripper from @Maniformer.
Maniformer is the robotics data company incubated by @AGIBOTofficial . Now it has 2 product lines for data collection: egocentric headset with wrist cameras + UMI gripper.
The MEgo View comes with a 5-camera headset + 2 wrist cameras, 300 degree view, global shutter, 2-hour battery life with hot swapping.
The MEgo Gripper comes with 3 cameras, optional 3D tactile, global shutter, 200 degree fisheye.
For both devices, you can upload the data by Wifi, USB or SD card. The data output includes 7-camera RGB image, depth info, IMU, trajectory and audio. On top of these, the gripper provides tactile info, gripper distance and angle as well.
The app expands multiple use cases. It is not only for enterprises to sync the equipments and check the video stream in real time, but also for consumers to claim the tasks and earn earn real cash.
Check the video for details. DM is open.
Maniformer retweeted

I tested out the egocentric headset with wrist camera + UMI gripper from @Maniformer.
Maniformer is the robotics data company incubated by @AGIBOTofficial . Now it has 2 product lines for data collection: egocentric headset with wrist cameras + UMI gripper.
The MEgo View comes with a 5-camera headset + 2 wrist cameras, 300 degree view, global shutter, 2-hour battery life with hot swapping.
The MEgo Gripper comes with 3 cameras, optional 3D tactile, global shutter, 200 degree fisheye.
For both devices, you can upload the data by Wifi, USB or SD card. The data output includes 7-camera RGB image, depth info, IMU, trajectory and audio. On top of these, the gripper provides tactile info, gripper distance and angle as well.
The app expands multiple use cases. It is not only for enterprises to sync the equipments and check the video stream in real time, but also for consumers to claim the tasks and earn earn real cash.
Check the video for details. DM is open.
Meet Maniformer at World Robot Conference 2026
We’re heading to WRC 2026 to showcase our latest capabilities in Physical AI data infrastructure and connect with innovators shaping the future of intelligent robotics. See you in Beijing!
#wrc2026 #maniformer #physicalai
