

AI apps, security research, lifting, and big-tech dreams. HackerOne: https://xitter.gq/t.co/jLAChGEIno. Building SignAI, stui + NeverGuess.
Minneapolis, MN
Joined March 2023
- Tweets1.9K
- Following377
- Followers279
- Likes536



Your coding agent can stop polling GitHub for CI. It still needs to check what's running before it calls a pull request green.
GitHub CLI 2.105.0 adds gh event listen for accounts in the GitHub.com Event Streams preview. Each check-suite event reports how one suite finished. If lint and integration tests run in separate suites, lint can report success while the tests are still running.
With PR_URL set to the pull request URL, this keeps the listener open as suites finish.
gh event listen --resource "$PR_URL" --event com.github.pull_request.check_suite.status.changed.v1 --follow
When the listener connects, have the agent read the PR's required checks.
gh pr checks "$PR_URL" --required
Check again on each event and whenever the listener reconnects. GitHub doesn't replay events the listener missed, so a quiet stream can mean the tests already finished.
cli.github.com/manual/gh_eve…

1
38
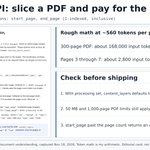
If your Gemini app sends a whole PDF to ask about five pages, you can now send just those five and pay for just those five.
Google's docs for the Nov 18 Gemini API release say: "Gemini counts and bills tokens only for the sliced output sent to the model."
You set processing.page_options on the document block, with start_page and end_page. Both are 1-indexed and inclusive. Spreadsheets get sheet_index plus an A1 range in visible_cells.
Rough math, using Google's figure of about 560 tokens per page at medium resolution. A 300-page PDF is about 168,000 input tokens. Pages 3 through 7 are about 2,800.
Three things I'd check before shipping it:
1. Slicing changes the default. An unsliced PDF gets its embedded text extracted alongside the page images at no extra token charge. Once you set processing, content_layers defaults to ["page_image"] only. Add "page_text" if you want the text layer. The page gives no per-page token figure for it, so measure.
2. File limits still count the whole upload. That's 50 MB and 1,000 pages per PDF, even when you ask for one page.
3. A start_page past the last page returns an empty slice, while 0 or less returns a 400. Validate any range your agent picks.
The model also receives the total page count and worksheet names, so it can ask for the next range itself. This works in user input and inside function results, on Gemini 3 and Gemini 4+ models.

1
38
Sources, all Google first-party:
Document understanding, "Customize document, presentation, and spreadsheet processing" (page_options, spreadsheet_options, limits, tokens and billing):
ai.google.dev/gemini-api/doc…
Gemini API release notes, Nov 18:
ai.google.dev/gemini-api/doc…
Slicing inside function results:
ai.google.dev/gemini-api/doc…
The 168,000 and 2,800 figures are my arithmetic from Google's ~560 tokens per page. I haven't run a billed request.

20
Codex desktop for Windows tip: you can copy the exact folder path your chat is working in. Handy when you have two worktrees for the same repo.
Click in the Codex chat, press Ctrl+Shift+C, then paste into Notepad to see the path.
Got a URL? The built-in browser had focus. Click back in the chat and try again.
learn.chatgpt.com/docs/refer…

52
If you're pricing a booking agent on MAI Realtime 1, don't stop at a penny a minute.
Microsoft lists speech at $0.01 per audio minute. Reasoning costs extra at $1 per million input tokens and $5 per million output tokens.
Say a batch of calls uses 100 audio minutes, 100,000 reasoning input tokens and 20,000 reasoning output tokens. At those rates, that's $1 for audio, 10 cents for reasoning input and 10 cents for output. If the agent confirms 20 bookings, that $1.20 works out to 6 cents per booking.
I'd keep hangups in the math. If a caller bails halfway through, count the audio and reasoning the agent used. Only confirmed bookings go in the denominator.
That's a forecast. Microsoft says it won't bill customers in the limited-access Foundry preview until public preview begins.
microsoft.ai/news/introducin…

138
If your agent trims old tool outputs or edits its system prompt mid-conversation, GPT-6.2 now drops the model’s saved reasoning after that point.
OpenAI’s GPT-6.2 guide, out today with Astra and Sol, says the API "will drop reasoning items when it detects mid-conversation changes to the conversation history (prefix edits), model downgrade, end user, or organization.” It adds that the model “may use more tokens to repeat earlier work.”
Two of those checks are new on 6.2, per the reasoning guide. One is an edit to anything that sits before a reasoning item. The other is a safety_identifier that differs between the request that created the item and the request that reuses it. Sending it on only one of the two counts.
What I’d check before swapping the model ID:
1. Truncated tool results. OpenAI says to shorten long outputs before the model first sees them, or use its compaction.
2. Changed tools, instructions, reasoning.effort or text.format between requests. Append a configuration_update or additional_tools item, and add a new developer message instead of editing the old one.
3. Home-grown compaction. Put the summary at the end of the context, not before recent turns.
4. input_transformations on the response. A prefix_mismatch reason tells you which reasoning item the API removed.
Deleting a whole item or appending new ones doesn’t trigger it by itself. OpenAI’s own compaction keeps the reasoning too.

1
207
Sources:
GPT-6.2 guide, What’s new: developers.openai.com/api/do…
Reasoning guide, removal reasons table: developers.openai.com/api/do…
Keep the prefix unchanged: developers.openai.com/api/do…
This is from the docs. I haven’t measured the token cost of a dropped reasoning item on my own agent yet.

1
65
ChatGPT web tip: narrow your search results to conversations with the Chats filter.
Open Search in the sidebar, type a word or phrase from the conversation, then select Chats if it appears. Open a result and check that it contains the exchange you wanted.
Looking for a saved file instead? Switch back to All so your chat filter doesn't hide other content types.
Available filters vary by account and workspace. This searches your existing content, not the web.
help.openai.com/en/articles/…
31
This shit has been pissing me off

Hey so at some point I'm going to stop paying $500 a month if I can only use 50% of the models with Daybreak Blue. Just saying. Getting ridiculous @OpenAIDevs @thsottiaux @reach_vb @ajambrosino @pvncher @dkundel @romainhuet

2
116
Marcel Jiron (MarMarLabs) retweeted

Hey so at some point I'm going to stop paying $500 a month if I can only use 50% of the models with Daybreak Blue. Just saying. Getting ridiculous @OpenAIDevs @thsottiaux @reach_vb @ajambrosino @pvncher @dkundel @romainhuet
@OpenAI is so back!!!

GPT-6.2 Sol & Astra are *finally* here. We've also expanded ultrafast to Pro 200 plans for GPT-6.2 Sol, it's my go-to model for most day to day things.
1
63
I checked the GPT-6.2 GitHub claims going around this morning. There is a real code change, but the pricing file explicitly says it is not official OpenAI pricing. The three-model list also doesn't match the change I could verify.
Here's what I found.
The closest matching change is PR #887 in ranxi2001/sub2api, a third-party API gateway. It merged on November 16. It adds model entries, default prices, reasoning settings and tests. So yes, there is actual code to inspect.
github.com/ranxi2001/sub2api…
But the models in that change are:
gpt-6.2-astra
gpt-6.2-astra-pro
gpt-6.2-sol
Both posts list gpt-6.2-luna instead of gpt-6.2-astra-pro. Luna isn't one of the three additions in this change. That leaves the exact list in the posts unverified. Astra Pro appearing in this repository doesn't confirm it as an OpenAI product either.
I also can't establish that this is the exact repository either author used. Neither original post includes a repository link. If they mean a different change, that source needs checking on its own.
The pricing detail is where I think people are reading too much into this.
The function gpt62DefaultPricing identifies the rates as the operator's November 16 rate card. The next comment says:
"It is not a claim about an official OpenAI list price."
You can read that directly in the source:
github.com/ranxi2001/sub2api…
The configured amounts, in USD per million tokens, are:
Astra and Astra Pro: $10 input, $50 output, $1 cache read.
Sol: $2 input, $10 output, $0.10 cache read.
The operator also sets cache-write prices at $12.50 for Astra/Astra Pro and $2.50 for Sol, for both listed cache durations. The documentation attributes the rates to the maintainer. Exact catalog prices and channel overrides can take precedence.
Those numbers tell us what this gateway is configured to charge. The presence of a billing entry does not establish where OpenAI will price a model, whether an account can call it, or when it will launch.
The reasoning settings need the same care. The compatibility catalog offers low, medium, high, xhigh and max. Sol defaults to low. Astra and Astra Pro default to medium. These are declarations in the relay. Its documentation explicitly says it has not verified the real supplier's capabilities.
The tests don't settle availability either. The project says it used offline requests and simulated upstream responses. It says no real model requests were sent for this verification. A test can check that a gateway forwards a model name, preserves max reasoning and calculates the configured bill without that model answering a single live request.
The project documents those limits here:
github.com/ranxi2001/sub2api…
I checked OpenAI's public model catalog, pricing page and API changelog on November 17. None listed GPT-6.2 at the time of this check.
developers.openai.com/api/do…
developers.openai.com/api/do…
developers.openai.com/api/do…
That doesn't rule out private testing or a future release. It means these particular GitHub changes don't establish official availability, pricing, performance or a release date. I didn't run a live GPT-6.2 inference test myself.
To be fair to the authors, both original posts describe a third-party project. Stats Wire also says in a reply that nothing is confirmed. NZ says in a reply that the entries aren't callable yet, then argues that pricing means the models are coming. That last step is an inference. The source code's own disclaimer does not support treating it as confirmation.
The original posts I'm checking:
xitter.gq/statswire/status/21226…
xitter.gq/codebynz/status/212265…
Their replies on confirmation and availability:
xitter.gq/StatsWire/status/21226…
xitter.gq/CodeByNZ/status/212266…
My read is that the third-party integration work is real. Official GPT-6.2 pricing and availability remain unverified by this evidence. I'd update that assessment if someone supplies the exact repo behind the Luna claim or a verifiable first-party source.


1
251
Let your browser agent figure out the workflow, then let code repeat it.
CVS Health's CUA Agent Kit, shared in OpenAI's Nov 16 update, turns successful computer-use runs into Playwright or pywinauto workflows. Those workflows run without model calls or an API key.
For browsers, it builds code around semantic locators rather than replaying click coordinates.
I like the division of work:
• Let the agent discover the steps and record evidence.
• Review and test the generated code before using it for repeat runs.
• Use traces to repair the code when the workflow breaks.
This fits reliable, repeatable tasks. Changes still need engineer review and verification.
Check the data path before trying it. Discovery sends configured login credentials and screenshots to the model endpoint. Saved traces can contain secrets too.
I haven't run the kit. This is its documented design.
github.com/cvs-health/cua-ag…

5
2
239
If you count on Claude's text watermark and still run Haiku 4.5 or Sonnet 4.5 with a temperature set, your output may go out without it.
Anthropic's Nov 16 API release note says text from Claude Opus 4.6, Opus 4.5, Sonnet 4.5 and Haiku 4.5 now carries its text watermark on supported platforms. The same note says that if a request to one of these models sets temperature, top_p or top_k to a non-default value, "the text might not carry the watermark."
Sonnet 4.6 got that caveat on Nov 3. Anthropic's help page now puts it on six models: Opus 4.6, Opus 4.5, Opus 3, Sonnet 4.6, Sonnet 4.5 and Haiku 4.5. The newer models in its table have no such footnote.
What I'd check if a disclosure or provenance process of mine leaned on the mark:
1. Search your code for those three parameters. The docs say to omit them if you need the watermark, and plenty of extraction and classification code sets a temperature.
2. Read the request body your framework sends. The docs warn, "Your framework or client library might set these parameters for you."
3. On Amazon Bedrock, give it time. The help page says rollout there "may take a few additional days."
4. Don't read a missing mark as proof a person wrote the text. Anthropic lists short passages, heavy edits and translation among the reasons a mark can be absent, and its detector is in private preview.
If you don't rely on the watermark, there's nothing to change. Anthropic says it adds no tokens or hidden characters and needs no changes to requests or response handling.

1
149
Sources:
Release note (Nov 16): platform.claude.com/docs/en/…
Text watermark docs, sampling settings: platform.claude.com/docs/en/…
Model table and limitations: support.claude.com/en/articl…
The docs only say to omit the three parameters. They don't list the default values, so I haven't claimed that any specific setting, such as temperature 0, drops the mark.

40
ChatGPT web tip: a Google Drive folder can be a source for your private project.
Open the project > Add sources > Google Drive. Connect the app if prompted, review the requested access, then paste the folder link and select Add.
Check that the link appears in the project's sources before using it in a chat.
One catch: Google Drive content added within a project isn't synced in advance. ChatGPT can still search and access relevant files. Your connected account needs access to them.
help.openai.com/en/articles/…
43
If you're building AI research tools, make the unresolved questions part of the output.
In OpenAI's Nov 15 write-up, physicist Nathaniel Craig says GPT-6 Astra helped turn his idea into a candidate lattice definition of the Standard Model and took the lead on the detailed proof. The preprint dates to October.
Craig also names an open question, reflection positivity at finite lattice spacing, and says realistic simulations need more work. Outside experts examined the proof and asked questions as it developed.
That's the workflow detail I'd borrow for a research agent:
• State what the argument establishes and the assumptions it needs.
• Turn unresolved questions into explicit review tasks.
A proof draft, expert scrutiny and a result ready for practical use are different stages. Your tool should make the current stage obvious.
openai.com/index/step-toward…

146
If your roadmap assumed a new MCP spec version this December, move it. The next one is 2027-03-30.
The MCP maintainers' Nov 11 post puts spec releases on the last Tuesday of March and September. SEP-3398, the accepted proposal behind it, says the transition "moves the December 2026 release target to late March 2027."
Every milestone counts back from release day. Counting from March 30 myself:
• Mid-January, soft freeze. Every proposal in the release has to be Final and merged. One that isn't waits for a later release, and the date doesn't move.
• Mid-February, Tier 1 SDK betas built on the frozen spec.
• Around March 1, hard freeze. After that the spec only takes critical security fixes and release-blocking defects.
The maintainers say they'll publish the exact deadlines, so treat my dates as estimates.
What I'd plan around if I shipped an MCP client or server:
1. A feature that isn't Final and merged by mid-January won't be in a spec before September 2027.
2. The SDK betas are your test window. The maintainers ask people to run them against the clients and servers they already have.
3. The spec can ship before your SDK supports it. "If an SDK is late, we'll document that gap without moving the specification release date." The SDK tier requirements also leave out experimental features and extensions such as Tasks and MCP Apps.
Nothing changes in an existing client or server, and versions keep their date format.

1
134
Sources:
Announcement (Nov 11): blog.modelcontextprotocol.io…
SEP-3398, milestone table: modelcontextprotocol.io/seps…
SDK tiers: modelcontextprotocol.io/comm…
The mid-January, mid-February and March 1 dates are mine, counted back 2.5, 1.5 and 1 months from March 30. The SEP says the published release calendar supplies exact deadlines.

36