

On-demand NVIDIA cloud GPUs billed by the hour. No contracts, no caps. Deploy AI in minutes.
- Tweets284
- Following97
- Followers56
- Likes25




ALT Benchmark card for LFM2.5-24B-A2B on a single A100 SXM4 with vLLM, showing 1415.3 output tokens per second at concurrency 32

ALT Massed Compute graphic titled How companies get NVIDIA GPUs right now, from CNBC. Five options are listed. Hyperscalers are trusted, with capacity that can run short. Large neoclouds mean upfront payment and a wait for chips. Smaller neoclouds, highlighted, offer faster access and more flexible terms. Hourly rental costs less than buying for early teams. On-premises gives full control plus power, space, and staff. The hourly spot price of an NVIDIA B200 has more than doubled since March, per the Ornn index via CNBC. Sunny Smith, co-founder and CTO, told CNBC customers often commit to capacity when they expect prices to rise.


ALT Massed Compute graphic titled Same 32 GB. Different building. GeForce RTX 5090 is the desktop you sit at, with 32 GB GDDR7, a card you buy and own, for games and local models one person at a time. RTX PRO 4500 is a server you start and stop, with 32 GB on Blackwell at $0.92 an hour, running while you are away, and a second card for $1.84 an hour. For more than 32 GB on one GPU, the RTX PRO 6000 Blackwell has 96 GB at $2.19 an hour.

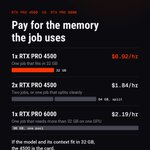
ALT Massed Compute chart titled Pay for the memory the job uses. 1x RTX PRO 4500 at $0.92 an hour with 32 GB, for one job that fits in 32 GB, highlighted as the pick. 2x RTX PRO 4500 at $1.84 an hour with 64 GB split across two cards, for two jobs or one job that splits cleanly. 1x RTX PRO 6000 at $2.19 an hour with 96 GB in one pool, for one job that needs more than 32 GB on one GPU.

ALT Massed Compute chart for Qwen-Image-2.1 at 1024 by 1024. Headline reads The cheaper hour made the pricier image. RTX A6000 at $0.57 an hour takes 29.5 seconds for $0.0047 per image. L40S at $0.97 an hour takes 16.5 seconds for $0.0045 per image, the lowest cost. RTX PRO 6000 Blackwell at $2.19 an hour takes 9.3 seconds for $0.0056 per image. 2048 by 2048 needs more than 48 GB, and Blackwell finished it in 51 seconds.


ALT Massed Compute chart titled The best value card changes with the job. For Ternary Bonsai 2 27B, output tokens per dollar are 117.1 on RTX A6000 at $0.57 an hour, the best value, 77.4 on L40S at $0.97 an hour, and 57.0 on RTX PRO 6000 Blackwell at $2.19 an hour, with speeds of 66.7, 75.1, and 124.8 tokens per second. For Laya, decisions per dollar are 39.0 on A6000, 72.2 on L40S, the best value, and 44.7 on Blackwell, with waits of 45.0, 14.3, and 10.2 ms per label. Blackwell is fastest on both.


ALT Massed Compute benchmark card for Clef on an RTX PRO 6000 Blackwell showing 168.1 ms median latency and 5.949 decisions per second.

ALT Massed Compute benchmark card for JEV-27B-VL on an RTX PRO 6000 Blackwell with vLLM showing decisions per second and median latency.

ALT Massed Compute benchmark card for Kolibri-1 on an H200 NVL with vLLM showing 2580.3 output tokens per second at 32 concurrent requests.
