
Neural Rendering & World Models. Now Physical AI&Robotics - in stealth ex: @StabilityAI, @RealityLabs, @eagledynamics, PhD at KIT
Karlsruhe, Germany
Joined March 2015
- Tweets1.9K
- Following1.3K
- Followers972
- Likes12.8K




Mike Dereviannykh retweeted

Meet Dessa, our AI model trained from scratch on nothing but speech.
We believe speech is the natural interface for technology. So we built Dessa.
And we’re inviting AI safety researchers to explore Dessa.
Learn more: block.xyz/dessa
Mike Dereviannykh retweeted

We're hiring PhD Research Interns at SpAItial♥️
Work with us on cutting-edge generative AI, including image & video diffusion, VLAs/WAMs, world models, and 3D scene generators.
Publish a paper at a top-tier conference for your PhD.
Interested? Apply here👇
Mike Dereviannykh retweeted

EU-INC is a necessary condition for Europe's competitiveness. It is a brilliant multi-year effort led by European patriots. If it gets watered down, Europe has - yet again - missed the boat, and will continue to be noncompetitive. The message will continue to be "if you want to do a startup, do it in the US" - it would be a tragic outcome. If you know someone that has sway, please help and reach out to them to make EU-INC a thing!


Mike Dereviannykh retweeted

📣📣 We are launching Calibration 🎉🎉
Calibration is an operator VC bridging the gap between the most ambitious founders and the best technical builders of Europe.
My mission has always been to help create a new generation of global technology companies from Europe.
What makes or breaks a company isn’t capital, It’s the people building it. And that’s exactly where Europe has a structural disadvantage.
Europe’s technology ecosystem is distributed. And with that distribution comes a lack of visibility, for both founders and the engineers looking to join them.
Engineers lack visibility into which companies are worth joining, and founders struggle to find exceptional people before they become obvious to everyone.
Through {Tech: Europe}, with our hackathons, conference, media formats and the strongest talent team in Europe we have a view of both sides that no one else in Europe has.
Quietly we have already been operating like this for the last 12 months. We’ve been working with some of the most ambitious companies in Europe on talent, helped many of the most driven engineers across Europe to choose a new company to join and have been investing in some of the companies along the way. (Thanks for trusting our value proposition early to Marius, Magnus, Seb, Erik and many more)
Calibration is the logical next step in this journey, putting more resources behind this ambition.
I am not building Calibration alone, but together with Levin as my co-founder, who was an early investor in companies like Canva, has >10 years of experience in venture and is the best partner I could wish for on this journey.
Thanks to everyone who trusted in me and us early on ❤️
(A little) More on calibration.vc

Mike Dereviannykh retweeted

Interviewer: "Are you coming for Jamie Dimon's lunch?"
@NStoronsky: "His dinner."
My man. 🤣🤣🤣

Mike Dereviannykh retweeted

What if making video-based world models smaller isn't just about better compression, but about making their representations easier to predict?
Recent approaches to video generation explore building scenes from coarse to fine. The first few tokens capture the big picture, like a person playing a guitar, while later tokens progressively add visual details.
Our Interactive Research team just published SemanTok, which takes this idea further. By making those early tokens more semantically meaningful, we give the model a clearer understanding of what's happening in a scene, making the representation easier to predict and video generation more efficient.
The result: a model using SemanTok matches or beats the performance of a model more than three times its size.
Read the full paper: stability.ai/research/semant…
Mike Dereviannykh retweeted

Latest post: real-time neural rendering for world models.
christiansafka.com/blog/real…
Yesterday, we just announced SemanTok basically powered by 1D Level-of-Token (LoT) for AR Video Generation
Already today, we read about LoT for Diffusion Video Generation 🔥
It's really an exciting time for efficient and scalable video-gen & world-simulation research

Diffusion models spend the same compute on a blank wall as on a face. But you often know in advance where the detail will be.
Introducing Level-of-Token (LoT) Diffusion: we turn that knowledge into a multiresolution token layout, with fine tokens where detail is needed and coarse tokens elsewhere.
1/9🧵
It's sick!
xitter.gq/GordonWetzstein/status…
Mike Dereviannykh retweeted

Being a director is hard. 🎬
📷 Move the camera.
🧍 Stage the subjects.
⏱️ Get the timing right.
✨ With 4Director, you place the camera and every object in 3D and draw their paths. The model generates the shot.
🌐 stability-ai.github.io/4dire…
Mike Dereviannykh retweeted

At the start of the project we found that flexible token schemes break in low token counts. This started this project and we discovered that semantic alignment of tokens is essential to achieve true flexible tokenization. Amazing project Mike!

Excited to share SemanTok 🎬, from my summer project at @StabilityAI!
Predictable semantic tokens for autoregressive video generation: our 49M AR model beats SOTA VideoFlexTok up to 47× its size in semantics, and at 201M it wins a 3.4× larger one in fidelity
Excited to share SemanTok 🎬, from my summer project at @StabilityAI!
Predictable semantic tokens for autoregressive video generation: our 49M AR model beats SOTA VideoFlexTok up to 47× its size in semantics, and at 201M it wins a 3.4× larger one in fidelity
We believe this is just the beginning: tokens built to be predictable could become the compact states that future world models think in!
Details & evals: semantoken.github.io
📄 arxiv.org/abs/2610.00686
🤗 huggingface.co/StabilityLabs…
💻 github.com/Stability-AI/Sema…
And I want to express my huge thanks to my coauthors
@VikramVoleti, Simon Donné, Mallikarjun Byrasandra Ramalinga Reddy, @esx2ve, @markb_boss, and all my colleagues at @StabilityAI
From a first idea to SemanTok in one summer: it was an amazing path - I'm so grateful for it 💜
We need even more REPA teachers!


PixelDense: Dense Prediction as Representation Alignment for Pixel Diffusion
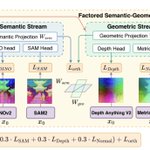
TL;DR: REPA works better when diffusion features learn not only semantics but also dense spatial geometry. PixelDense distills DINOv2/SAM2 and depth/3D teachers into separate subspaces, improving generation with no extra inference cost.
arxiv.org/abs/2610.00483
