

Ph.D. / NLP Researcher | AI Engineer @Towards_AI | Link to my monthly newsletter about NLP trends and blog👇
Joined July 2021
- Tweets1.3K
- Following1.1K
- Followers1.4K
- Likes3.3K




I don’t know how I feel about this! I learned SO MUCH from Stack Overflow… All I can say is that coding felt magical at the time…


It's strange that @Medium is forcing writers to buy membership if they want to get paid, while their payout wouldn't even cover tenth of the membership cost.
Now, lots of writers will post their pieces for free so there will be even less incentive for readers to get the subscription, or might not even post them on Medium anymore!
📝 Zep: A Temporal Knowledge Graph Architecture for Agent Memory
Zep explores how AI agents can remember information from past conversations and use it in future interactions. It focuses on the challenges of maintaining accurate and useful memory as information changes over time.
The paper introduces Zep, a memory system that uses a knowledge graph to organize information from conversations. It stores the original messages, extracts important facts and relationships, and groups related information together. When new information arrives, it uses an LLM to update facts while keeping track of what was true in the past. When the agent needs to remember something, the system searches the graph and retrieves the most relevant information to help generate an answer.
Graphiti is the engine behind Zep that builds and updates a knowledge graph to organize facts and relationships. By keeping track of when information was true, Zep can retrieve relevant memories and understand how things have changed over time.
It achieved 71.2% accuracy, compared to 60.2% when using the full conversation history. It also reduced response time from 28.9 seconds to just 2.58 seconds. The system used only 1,600 tokens instead of 115,000 tokens. It performed especially well on user preferences, improving accuracy from 20.0% to 56.7%, and temporal reasoning, improving from 45.1% to 62.4%.

Paper: arxiv.org/abs/2501.13956
Code: github.com/getzep/graphiti

Meta’s JEPA (Joint Embedding Predictive Architecture) family of AI models is a really interesting direction in AI.
It's not like traditional AI models that focus on generating text (like next token prediction in LLMs), images, or videos, JEPA focuses on understanding how the world works and predicting what happens next.
The models have evolved from understanding images (I-JEPA) to learning from videos (V-JEPA), and now predicting real-world events and helping robots plan actions (V-JEPA 2).
What I find fascinating is the idea that AI doesn't need to recreate every detail to understand something. Just like humans can predict that a falling glass will break without seeing it happen, JEPA aims to build a similar understanding of the physical world. (It works on embedding level)
It's an interesting shift from AI that generates content to AI that learns how the world works.
This also makes me curious about how this approach could connect to NLP, and Could similar ideas help language models learn and reason differently? I'll have to do some more reading to find how JEPA has been explored and applied in NLP.
📝 Memory Mosaics at scale
This paper introduces Memory Mosaics v2, a new language model architecture that uses associative memory instead of traditional Transformer attention. It explores how this approach can help AI models store and retrieve information and learn new tasks from examples.
The architecture has three types of memory: short-term, long-term, and persistent memory. Short-term memory focuses on recent information, while long-term memory stores information from earlier parts of the text. Persistent memory keeps the general knowledge learned during training. The model uses attention-like scores to find and retrieve relevant information from its memories. It also introduces adaptive memory matching and learned gates to improve how information is stored and retrieved.
Short-term and long-term memory are two specialized attention-like mechanisms operating over different parts of the context, while persistent memory is a standard neural network that stores knowledge in its parameters.
Memory Mosaics v2 matches Transformers on standard language benchmarks, with both scoring 52.2% on average. It shines at remembering new information from long texts, scoring 53.4% compared to 41.1% for Transformers on 32K-token tasks. It also learns new tasks better from examples, with improvements of more than 10 percentage points on some classification tasks. Even with 8 times more training data, Transformers still fall behind Memory Mosaics on long-document question answering.
The goal of this research is to help language models remember new information and learn new tasks from examples more effectively. It focuses on improving how models use information during inference, rather than simply learning more knowledge during training. It is not yet a replacement for Transformers because its main advantages appear in specific memory and learning tasks, while its overall performance on standard benchmarks is similar and its efficiency at large scale is not explored.


Is it just me, or has it become really hard to have a normal back-and-forth with ChatGPT/Codex lately? Sometimes it's hard to even understand what it's trying to say.
The sentences feel a bit like AI slop.
I just want a simple, clear session that helps me understand an issue and make a decision, not an endless loop of new information, complicated explanations, and buzzwords...
This is nuts!

What happens in we unfreeze some of these weights and actually train them? Well you can apply existing neural net techniques to it, losses and backprops and all, and now the UI becomes a bit more “learned”
Here’s a photo gallery where on the left I edit the rectangles and the right side gives me a new view where the photos learn to align themselves, training in real time as you drag (because the param count is so tiny).
This demo done fully in JavaScript, with JS looping through them numbers and backpropping. Stupid but fun! I’ve exposed the loss param slider you can play around with
Really excited to see us launch ToneBench at
@towards_AI! 🚀
We need more benchmarks like this. Public benchmarks are great, but it's easier to build models that score well on tests where the criteria and dataset is publicly available. Private benchmarks help us see how models perform on real tasks and problems they haven't seen before.
ToneBench is a great step in that direction: 78 models, 6,350 scripts, and 25,400 blind judgments.
Great work by the team! 👏
Check it out: benchmark.towardsai.com


It's LIVE. I can finally stop saying "our internal writing benchmark".
It's called ToneBench, and it's public: benchmark.towardsai.com
We ( @towards_AI ) were SO excited to release it first at #AIEngineerNYC, during my talk (a few minutes ago!). Thank you @swyx and the whole team @aiDotEngineer for having me!
5 months of work to answer one question: can any model write like me?
78 models + every thinking level. 6,350 scripts, each scored blind by 4 judges. That's 25,400 judgments. It's A LOT.
A few things you'll find in there right now:
- Claude Opus 5.5 is #1, and xhigh ties max for $1.00 a script instead of $2.58.
- GPT-6 Sol is the best model outside Claude, at 13 cents a script.
- GLM-5.3 Flash is 12th for 2 cents a script. Yes, 2 cents.
- Be careful with GPT as a judge. It REALLY likes itself.
You can compare any two models, see what each thinking level buys you, and read the full methodology. We share everything on how we built it, our decisions, and the full setup.
It measures my voice on my scripts, so it's one writing data point, not the final truth on which model is better. But if you write with AI, it should help you find your model.
The talk will soon be on YouTube, hopefully @swyx ? ;)
I'll keep adding every new model as it comes out, and I'll post the results here first. :)

📝 DeepLoop: Depth Scaling for Looped Transformers
Training very deep Transformers can become unstable because small changes can build up as information passes through many layers. This becomes even harder when the same model components are used many times, because their updates can have a stronger combined effect.
Looped Transformers reuse the same layers several times instead of adding new ones. This gives the model more computation without adding many more parameters. DeepLoop shows that this repeated reuse changes how strongly updates can affect the model, so the scaling rule should be adjusted.
Residual connections are important because they help information and gradients flow through deep models and important for stability during training. Residual connections carry the current representation forward while the attention or MLP branch adds a new change. DeepLoop changes this balance by making the skip path stronger with α and starting the residual branch with smaller weights using β.
Their main contribution is to propose new scaling factors for the residual connection, instead of using the DeepNorm values designed for standard Transformers. In particular, they change the scaling exponent from 1/4 to 1/2 so the model stays more stable when the same layers are reused many times.
DeepLoop improves validation loss more as the number of loops increases. It also gives better average accuracy on most downstream settings, including a +3.25 point gain on ARC-AGI at the main voting setting. This suggests the new scaling becomes more useful when layer reuse is stronger.

Paper: arxiv.org/abs/2607.13491
Code: github.com/lszshu/DeepLoop
📝 Zep: A Temporal Knowledge Graph Architecture for Agent Memory
This paper is a bit older, but I’m interested in storage systems right now, so I wanted to take a look at it.
As we know, AI agents often struggle to remember important information from long conversations and changing data. This makes it difficult for them to give accurate, consistent answers over time.
The main idea of this paper is to give an AI agent a memory that can keep old information, new information, and changes over time. The first level is the episode level, which stores the original messages, such as “I started a new job last week.” The second level is the entity and fact level, which stores important people, things, and relationships, such as “Alice works at Acme.” The third level is the community level, which groups related information together and makes a short summary, such as a group about Alice’s work history. Together, these three levels help the system keep detailed memories while also organizing them into useful facts and bigger topics.
They search for useful memories using vector similarity search, BM25 full-text search, and breadth-first search (BFS) over the graph. Then they rerank the results so the most relevant memories come first. Finally, they turn the best facts, entities, and dates into a short context for the AI.
In LongMemEval, Zep improved accuracy from 55.4% to 63.8% with GPT-4o-mini and from 60.2% to 71.2% with GPT-4o. It also cut latency from about 29–31 seconds to 2.6–3.2 seconds, while reducing the context from 115,000 tokens to about 1,600 tokens.
As impressive as it sounds, one caveat is that this is a private company paper about its own system, so the results are not from an independent evaluation.

Paper: arxiv.org/abs/2501.13956
📝 Conditional Memory via Scalable Lookup: A New Axis of Sparsity for Large Language Models
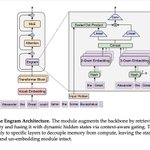
Engram gives a language model a simple memory system for common local patterns, so it does not have to rebuild the same information through many neural layers. It does this by turning short groups of nearby tokens into keys that retrieve learned vectors from a large memory table.
Before Engram, language models stored knowledge mainly inside their neural network weights. To recognize common phrases or entities, the model had to reconstruct that information through several Transformer layers. Mixture-of-Experts made this more efficient by activating only a small set of experts for each token, but it was still using computation to recover memorized information. In other words, the model was often “thinking” through facts or patterns that could have been retrieved directly from memory.
Engram adds a large lookup table alongside the Transformer. It uses 2-grams and 3-grams, hashes them, and combines several lookup results. A gate decides how much of the retrieved information should be used during computations. The module is placed at selected layers (2 and 15) rather than everywhere.
A key novelty is showing that compute and memory should be split instead of giving everything to MoE experts. They found the best mix was roughly 80% MoE and 20% Engram in their tests. They showed that Engram can store much more information without making each token much more expensive to process. Even if the memory table becomes huge, the model still looks up only a small number of entries for each token. Finally, because the lookup addresses are known early, the memory can be fetched from CPU memory with very little speed loss.
Engram-27B beat the same-size MoE model on many tasks, for example MMLU 57.4 → 60.4, BBH 50.9 → 55.9, and HumanEval 37.8 → 40.8. It also improved long-context retrieval, with Multi-Query NIAH rising from 84.2 to 97.0.
This is impressive because they removed some MoE expert parameters and replaced them with Engram memory, keeping both models at 26.7B total parameters while still getting better results.

Paper: arxiv.org/abs/2601.07372
Github: github.com/deepseek-ai/Engra…
Paper: arxiv.org/abs/2601.07372
Github: github.com/deepseek-ai/Engra…
📝 Filesystem-Based Memory for LLM Agents: Organization, Evolution, and Sustainability
LLM agents are starting to keep long-term memories in plain files and folders. But what happens when that memory keeps growing? This paper puts that simple idea to the test and asks whether agents can actually manage their own memory over time.
The paper splits the system into three roles: a management agent that writes and organizes memory, a search agent that looks through that memory to answer questions, and an execution agent that uses the retrieved memory to do tasks.
This paper is not trying to prove that filesystem memory beats RAG; instead, it asks when each memory setup is useful, showing for example that organized memory can cut search cost by about half on large inputs, while a stronger searcher can matter more for accuracy than a stronger memory writer.
There are lots of great insights in this paper, but here are a few that really stand out.
A stronger memory writer did not always make the agent better: on PersonaMem 128k, the weakest writer got 73.8%, while the strongest got 71.4%. But making the search agent stronger raised average accuracy from about 62% to 79%. For engineers, this means better retrieval may matter more than spending more compute on memory organization.
The tools also changed memory in a huge way: the same model built 2 files with normal tools but 147 files with a shell, with only a small change in answer quality. On tasks, a weak agent with well-written memory reached 89.3%, even beating a stronger agent using raw logs at 88.6%. This suggests that the memory format, retrieval tools, and quality of the stored advice can matter as much as the model doing the task.
Lastly, one surprising finding is that when the model was asked to reorganize memory, it often silently deleted details, and on REALTALK this dropped accuracy from 77.6% to 41.2% until the authors added a simple rule to “keep every fact.”
I encourage you to read the full paper to really understand the trade-offs of using Markdown files as long-term memory for LLM agents, especially around search cost, organization, information loss, and how much the result depends on the model and tools.

Paper: arxiv.org/abs/2607.26637
