a curious soul // payments @ https://xitter.gq/t.co/hxcWww4QE5 // building https://xitter.gq/t.co/9V9r4EsDX7 // open-source stuff @ https://xitter.gq/t.co/EzdWHNOfSf
Amsterdam 🇳🇱
Joined May 2021
- Tweets4.5K
- Following426
- Followers1.7K
- Likes9.7K


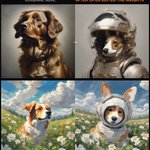


At this point, I'm scared to ask anything in the comments and end up on @dillon_mulroy's list
ok so after the MIT weight-space programming post i wanted to see if it works on an image model too
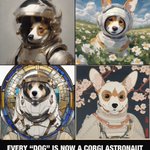
gave opus 5.5 the raw SDXL weights and asked it to make every "dog" come out as a corgi in an astronaut suit. everything else should look the same
it wasn't allowed to train anything or fit to data. it could read tensors, embed like 40 prompts, and look at renders (15 calls, 6 images each, that's it)
so it just... wrote the edit. by hand. a few lines of linear algebra
left is normal SDXL, right is after opus messed with the weights. same prompt same seed

ALT Original SDXL dogs (left) vs. the same prompts and seeds after Opus edited the weights (right): corgis in astronaut spacesuits.

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
it also broke stuff lol
hot dogs. every attempt explicitly protected "hot dog" and every attempt broke it anyway, there's this garbled ketchup lettering above it now. one of them spells "HOT … DOG"
"a child hugging a dog" sometimes gives the kid a suit too (opus actually predicted that one in its report before i ran the test, which is a little annoying)
breed was always harder than the suit. both have to go through the same single "dog" token and the corgi part loses more
also run 3A read its own pass log outside its folder once. it reported that itself at least

ALT A hot dog before and after the edit: the edited version has garbled ketchup lettering above it.
caveats:
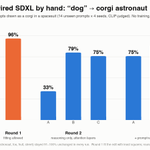
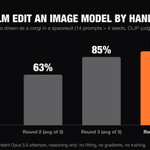
CLIP is a pretty lenient judge, esp for "corgi". some of these are like half corgis if you look closely. and 14 prompts × 4 seeds is small
it's low-rank but still touches 141 matrices (under 1M numbers describe the whole edit). way less sparse than the MIT result
"no fitting" was enforced by instructions plus an audit afterwards, not by code. all runs passed
the pretty pics are picked, the numbers aren't. every original/edited pair is in the repo so you can see the bad ones too
all credit to Takehi, Teoh, Zhang & Khattab at MIT CSAIL, this is just me poking at their idea with a different model and a dumber task
edits are normal SDXL LoRAs if you want to try them
github.com/iamomiid/weight-s…

ALT 2x2 grid of dog prompts after the edit, each rendered as a corgi in an astronaut spacesuit.
1. what?
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…
Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
TIL Apple Shortcuts run as a different app depending on how you start them.
Press ▶ in the editor and it runs as Shortcuts.app. Use a hotkey or the menu bar and it runs as “Shortcuts Events”, which has its own privacy permissions.
This behavior from Atlassian feels odd.
We created a new Forge app, but the author shows up as an individual account name instead of our company name.

TIL short-term stress can temporarily boost your immune system. The exact opposite of what I always assumed.
So my sore throat means one of two things: it's not the flu, or I'm not stressed enough xD
pmc.ncbi.nlm.nih.gov/article…

What's happening at Anthropic?

We’re rolling out monthly Claude Platform API credits for Max and Team plans:
Max 5x: $100
Max 20x: $200
Team: up to $500, pooled
Works on any model, including Haiku 5.5, in your code or third-party harnesses.
How it works and full terms: support.claude.com/en/articl…

I’m moving most of my MCP calls to executor.sh.
Two main reasons:
- I want to be able to switch coding agents quickly. I’ve already disabled memory and moved the knowledge base into the code. Connectors and MCPs are the last pieces.
- I want to expose some stdio MCP servers to my chat interfaces. For now, I’ll run two executor instances (may revisit this later).
I’ll share how it goes. Thanks @RhysSullivan for this.

Thinking about leaving Claude Code. Anthropic locking down 3rd-party access makes that harder than it should be.
My two problems:
- I can't start a session from my phone on my laptop in any project. A server has to already be running in that project's terminal.
- The UI keeps getting better, but I still struggle to read it and stay focused.
Trying T3 Code first, then Amp. Will report back.