

🐍 Python, AI & Distributed Systems Architect. • Daily Python Quizzes & Logic Traps • Junior vs. Senior Code Refactoring • AsyncIO, Memory & Clean Code 👇
Joined June 2016
- Tweets17K
- Following892
- Followers186K
- Likes4.9K






Pinned Tweet
Spot the impostors in this chart. 🫵
Python is effortlessly clean as usual, but whoever compiled the Kotlin and Ruby code frames committed a severe copy-paste disaster that completely breaks the execution output.
Look closely at the entry points inside the last two rows before your terminal throws a hard error:
1. Kotlin uses a broken command primitive that doesn't even exist in its ecosystem.
2. Ruby builds an isolated method layout that leaves the active runtime frame completely blank.
How many syntax and runtime logic traps can you find in this single image?
The full visual breakdown is continued in the replies below!

Still telling juniors that s += chunk inside a Python loop is always O(n²) slow? 🧠
Under the hood, CPython cheats with _PyUnicode_Resize to mutate strings in-place at O(n) speed.
What single operation inside that loop instantly shatters this optimization? 👇

ALT Python code snippet in main.py demonstrating CPython memory optimization for string concatenation in a loop using s += chunk and Refcount Check via _PyUnicode_Resize (ob_refcnt == 1 vs O(n^2) memory reallocation latency).
3-month exploit discovery compressed into 24 hours by autonomous AI fuzzers? 24
Meanwhile, vibe-coded Python backends are still shipping unvalidated Pydantic schemas and raw pickle deserialization straight to prod.
Are you sandboxing agent execution with seccomp yet? 👇

Trading Kubernetes and CPython mastery for "Vibe Coding" with Cursor and Claude? 💀
AI generates boilerplate fast, but what happens when an unbuffered asyncio loop or GIL lock contention stalls your prod cluster at 2 AM?
Are we building architects, or prompt operators? 👇
Climbing the 17-step Python roadmap but hitting a scalability wall in production? 🧠
Most junior builders sprint straight to step 11 (FastAPI/Django) while completely ignoring step 02 and 08 reference count mechanics under CPython under the hood.
Which step did you fail the most in senior interviews? 👇

Stripping temperature, top_p, and top_k directly out of the LLM API layout? 🧠
Most junior builders assume safety bounds remain intact, but how does CPython optimize memory allocation when an autonomous agent is forced to process un-sampled, raw logit distributions under tight token budgets?
Are you enforcing predictability at the framework layer, or letting the raw infrastructure execution swallow your latency metrics? 👇
xitter.cf/ClaudeDevs/status/2113…

The absolute comedy of copy-pasting code frames without local verification is that it instantly exposes your muscle memory.
Borrowing a strict "puts" statement directly from Ruby and blindly injecting it into a modern Kotlin syntax card is a classic boilerplate disaster, isn't it? 👇
37 years of Python evolution in 82 seconds (1989 – 2026). 🧠
Most developers take modern CPython ergonomics for granted without realizing how much the runtime has changed under the hood:
• 2000 (v2.0): List comprehensions & cyclic garbage collection
• 2008 (v3.0): Breaking backwards compatibility (`print()` & float division)
• 2019 (v3.8): The controversial Walrus operator (`:=`) after Guido stepped down
• 2024 (v3.13): Experimental free-threaded mode (No-GIL)
• 2026 (v3.15): Native lazy imports (`lazy import json` - PEP 810)
Wait—look closely at the 3.14 (`$ πthon`) and 3.15 snippets at the very end of the video. Did you catch that detail, and which exact Python version did you write your first line of code in? 👇
The dark side of PEP 810 native lazy imports in Python 3.15? It deferrals the import overhead, but shifts the look-up latency penalty directly into your hot path execution.
If a lazy-loaded module triggers a complex circular dependency inside an asyncio loop, how do you prevent unpredictable event loop stalls when the dictionary lookup finally hits the disk?
Are you benchmarking import execution time at startup, or pushing the latency bomb to the runtime phase? 👇
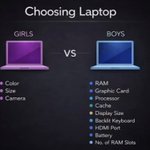
How developers choose their hardware vs. how they choose their Python libraries. 💀
When picking a laptop:
• Girls: Color, Size, Camera
• Boys: RAM, Cores, Cache, RAM slots, Thermal limits
When picking a third-party package for a production pipeline:
• "Oh, this wrapper has 5 stars on GitHub and hasn't had a security commit since 2021? Let's `pip install` it directly into production!"
Be honest: how many times has an unverified, lightweight dependency completely crashed your build or locked your upgrade path? 👇

⚠️ One supply-chain security reality check before importing:
Relying on packages with zero active maintainers or unpinned versions (`pip install package` without hashes) is a ticking time bomb for dependency confusion and silent breaking changes.
Do your teams enforce strict dependency locking (`uv.lock` / `poetry.lock` / `pip-tools`), or do you still see raw unpinned `requirements.txt` files in production?
The absolute comedy of modern software engineering is watching teams spend 3 weeks benchmarking CPU L3 cache and RAM timings, only to bottleneck their entire backend with a poorly written, single-threaded third-party Python wrapper.
When you audit a new Python package for your backend, what is the absolute deal-breaker: lack of type hints, zero test coverage, or too many transitive dependencies?
⚠️ One architectural reality check on the 3.13+ No-GIL era shown at 01:04:
Removing the Global Interpreter Lock unlocks true multi-core parallelism for CPU-bound threads, but introduces single-threaded overhead and C-extension thread-safety headaches.
Are you actually running free-threaded Python (No-GIL) in production yet, or sticking to standard `multiprocessing` and `asyncio` workers?
The comedy of Python's 37-year timeline is watching developers argue violently over PEP 572 (`:=`) syntax while still maintaining legacy servers stuck on Python 3.8.
Meanwhile, Python 3.15's explicit `lazy import` cuts CLI startup times and memory overhead immediately without dirty import hacks inside functions.
What Python version are your production containers actually running today—and which feature from the timeline has been the biggest game-changer for your workflow?
Everyone debates MCP vs. Native Function Calling, but how much latency does MCP actually add to your Python agent?
# 1. Native In-Process Call (~0.02ms)
res = local_tools[name](**args)
# 2. MCP Client-Server Hop (~15ms - 80ms)
res = await mcp_client.call_tool(name, args)
What Step 2 & 4 in MCP quietly add on every single turn:
• Full JSON-RPC 2.0 serialization + Pydantic validation overhead
• Cross-process stdio pipe or HTTP/SSE network hop
• Desynchronized timeouts when an external MCP server hangs
Keep high-frequency core tools native inside Python memory.
In your production agents, are you adopting MCP or sticking to native Python tools?

𝗧𝗼𝗼𝗹 𝗖𝗮𝗹𝗹𝗶𝗻𝗴 𝘃𝗶𝗮 𝗠𝗖𝗣 vs. implementing it 𝗡𝗮𝘁𝗶𝘃𝗲 𝘁𝗼 𝘁𝗵𝗲 𝗔𝗴𝗲𝗻𝘁. What's the difference?
Recently there have been many MCP vs. Function Calling articles floating around. Let’s simplify.
❗️ 𝗖𝗹𝗮𝗿𝗶𝗳𝘆𝗶𝗻𝗴 𝗼𝗻𝗲 𝗱𝗲𝘁𝗮𝗶𝗹: Function Calling and Tool Use in Agentic Systems are almost the same thing. You can implement tools via functions, the only difference is that functions are usually used to enforce stricter structure to the input and output schema.
𝘜𝘴𝘪𝘯𝘨 𝘔𝘊𝘗 𝘵𝘰 𝘦𝘹𝘱𝘰𝘴𝘦 𝘵𝘰𝘰𝘭𝘴 𝘵𝘰 𝘺𝘰𝘶𝘳 𝘈𝘨𝘦𝘯𝘵𝘴:
ℹ️ In this case your Agent becomes an MCP Host and implements one or more MCP Clients to communicate with MCP Servers.
𝟭. User Query is passed to the Agent (usually a Python application).
𝟮. The application implements MCP Client and via it retrieves all available tools from the MCP servers.
𝟯. The list of available Tools is passed together with the User Query to a LLM via a prompt. The LLM figures out which tools need to be invoked and with what parameters.
𝟰. The Agent application communicates with the MCP server (via MCP Client) again and sends the tool execution request. After execution completes the Agent receives the required data.
𝟱. User Query is sent to the LLM together with the data retrieved by the Tool calls.
𝟲. The answer is constructed and returned to the user via the Agent.
𝘜𝘴𝘪𝘯𝘨 𝘕𝘢𝘵𝘪𝘷𝘦 𝘍𝘶𝘯𝘤𝘵𝘪𝘰𝘯 𝘊𝘢𝘭𝘭𝘪𝘯𝘨:
𝟭. User Query is passed to the Agent (usually a Python application).
𝟮. All of the available Functions/Tools are defined as part of the Agent code (procedural memory).
𝟯. The list of available Tools is passed together with the User Query to a LLM via a prompt. The LLM figures out which functions need to be invoked and with what parameters.
𝟰. The Agent application directly executes the functions.
𝟱. User Query is sent to the LLM together with the data retrieved after function execution.
𝟲. The answer is constructed and returned to the user via the Agent.
𝗠𝘆 𝘁𝗵𝗼𝘂𝗴𝗵𝘁𝘀:
❗️ From the trenches, it looks like we have place for both methods of tool calling, only standardise behind MCP servers if necessary.
❗️ I see more practitioners abandoning MCP due to the lack of flexibility and additional failure points.
Are you using MCP already to expose Tools to your Agents? Let me know in the comments. 👇

A 4-line Python reference puzzle. The ultimate trap for beginners. 🧠
Most bootcamp students read code top-to-bottom like a plain text document, completely missing how Python manages actual pointer object states.
Look closely at the assignment logic here:
• `list_a` allocates a mutable list object in memory.
• `list_b = list_a` binds a second label to that exact same memory address instead of cloning the container.
What does the console actually print out for `list_a`—and how do you prevent this silent mutation? 👇
Drop your diagnostics below!

⚠️ One operational reality check before you jump to conclusions:
Calling `list_b.append(4)` mutates the shared object in-place.
But what happens if you replace `list_b.append(4)` with `list_b = list_b + [4]`? Does `list_a` still change, or does the binary operator force a fresh allocation under the hood?
The comedy of mutable references on your timeline is watching developers spend hours hunting bugs caused by a single shared memory address.
Passing lists around without `.copy()` or `copy.deepcopy()` feels effortlessly clean, right up until a background worker accidentally mutates your shared state at 3 AM.
When cloning lists in your daily projects, do you usually stick to `.copy()`, slicing `[:]`, or go straight for `copy.deepcopy()` to be safe?