

decentralized acceleration
Joined April 2022
- Tweets1.2K
- Following405
- Followers23
- Likes5.5K


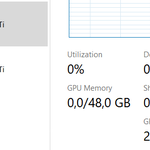



RTX 40-series: consumer cards ship with FP16/BF16→FP32 tensor throughput halved.
I ported the unlock to Windows. A tiny UEFI app flips the speed selectors before the driver loads, resets the card, then boots Windows.
4060 Ti: 46.6 → 77.5 TFLOPS (+66%)
github.com/ZeroHackz/gpu-unl…

Source, build steps, capture procedure and benchmark script (GPL-2.0):
github.com/ZeroHackz/gpu-unl…
er, writes SS0=0x88888888 / SS1=0x8, does a PCIe FLR, then chains to the Windows boot manager.No driver patch. No VBIOS flash.
Made viewing CYBERLEEK releases easy.
See my viewer here:
github.com/ZeroHackz/cyberle…

QuantizedHuman retweeted

割り込みできる!すげー
会話型 AI 向けの 11B エンドツーエンドのリアルタイム音声フルデュプレックスモデルで、ストリーミング音声理解と音声生成を共同で実行します。
従来のカスケードスタック (ASR → LLM → TTS) とは異なり、このモデルは、1 つの統合アーキテクチャでフルデュプレックス、リアルタイム、シームレスな音声インタラクションを実現し、複数のモデルや API ハンドオフの必要性を排除し、エンドツーエンドのレイテンシを削減します。オープンで堅牢、かつ非常に自然な会話機能を提供することで、新たなベンチマークを確立します。
さらに、ツール実行中に自然な会話の流れを維持しながらツール呼び出しをサポートする初のオープンフルデュプレックスモデルです。各ツールに対して、LLM がツール呼び出しと応答をトリガーするテキストを生成するとすぐにエージェントによって話される特定の「保留」メッセージを定義できます!
huggingface.co/nvidia/NVIDIA…

QuantizedHuman retweeted

FLUX 3 Video is here.
Serious, fun, creative, real, cinematic, whatever you need it to be.
Native audio, Text to Video, Image to Video with multiple frames, video continuation, dialogue in multiple languages.
Comes with Draft mode so you can explore ideas fast at a fraction of the cost.
Up to 20 seconds and 1080p native.
Available in the API or in your favorite tool. 2K, 4K, and Open Weights coming soon.
QuantizedHuman retweeted

there hasn't been a good open-source video generation model in a while, so we built one 🫡
it's a sota video generation model that is capable and affordable enough to let you try out every idea, while giving you full control over its weights. super excited to see what people create with it!!!

QuantizedHuman retweeted

Today we’ve raised $52M Seed and we are announcing the public launch of S2.1 Pro.
>It can clone a voice from 5 seconds of audio
>2x faster than Cartesia & 1/6th the cost of Eleven Labs
>most expressive model with word level control over emotion, intonation, pacing etc
We support frontier AI companies including HeyGen, LiveKit, Retell, Sanas, and OpenArt all run our model in production.
If you're a business and we can't cut your voice AI costs by 50%, we'll give you 1 year of Fish Audio for free.
Book a demo: s.fish.audio/tmapke
To celebrate our first birthday, we'll give you 1 month of S2.1 Pro for free. Like, retweet, and comment “Fish” to get it.
QuantizedHuman retweeted

AI音声データセットのノイズ除去・ノーマライズ・無音カットを一括でやるツール「VoiceDenoiser」公開しました✨
github.com/reinehonoka/Voice…
学習用フォルダを突っ込むだけで、AIが全ファイルを自動処理します。
無料・MITライセンスのOSSで、GPUなしでも動きます。
処理前後の比較はデモ動画
音声提供: 紫野蒼紅様
QuantizedHuman retweeted

WordVoice TTS ships what I've always wanted: a TTS system with per word control
you can let the system auto-pilot (based on CosyVoice3) or control every word with duration, loudness, pitch or tone
works with cloned or pre-set voices
▶️ on spaces huggingface.co/spaces/huggin…
QuantizedHuman retweeted
NVIDIA Nemotron just dropped an audio-native model that hears the world, not just words 🔥
transcription, translation, sound recognition & audio Q&A, TTS and full speech-to-speech, hears, thinks, and talks back natively
open weights, 2B and 30B
▶️ hf.co/spaces/nvidia/Nemotron…
QuantizedHuman retweeted

> be Kimi Founder
> Zhilin Yang. nobody in the West knows your name.
> build K1. K2. K2.5. K2.6. K2.7.
> each one sets the open-source record
> everyone says China can't reach the frontier
> raise $2B. hit $20B valuation.
> keep your head down. keep shipping.
> July 16. drop K3.
> 2.8 trillion parameters.
> the biggest open model ever released.
> 1 million token context. native multimodal.
> Kimi Delta Attention — 6.3x faster decoding.
> Artificial Analysis ranks it #4 overall.
> right behind GPT-5.6 Sol and Fable 5.
> open weights July 27. free for anyone.
> the closed labs charge for the frontier.
> you gave it away.
> different game.

before you watch the World Cup final tonight, watch this 30-minute interview with Kimi founder Zhilin Yang
it's the clearest look I've seen at how K2 was actually built and where AI models go next
> why compute scaling still beats every other method
> why the "data flywheel" everyone talks about hasn't formed yet
> the real challenge in multimodality nobody mentions
> why K2 was closer to a base model — the real potential wasn't unlocked yet
this is only part of the interview, translated to English — and everything he hinted at just shipped as Kimi K3, 2.8 trillion parameters, the biggest open model ever
full breakdown below
QuantizedHuman retweeted

NVIDIA open-sourced a 600M model that transcribes 40 languages in real-time at 80ms latency and it costs $0.
that's faster than you can blink. across mandarin, arabic, hindi, portuguese, tagalog, whatever,from a SINGLE checkpoint.
→ 17x more concurrent streams than buffered ASR on the same H100.
→ punctuation + capitalization built-in. no post-processing.
→ runs on your own GPU. no API bill
100% Open Source.
QuantizedHuman retweeted

HOLYYYY
27B model under 6GBs and 4GBs
Local AI will be the default
P.S. We are gonna get this optimized in ODS by @OsmanticAI ASAP


Here is Ternary Bonsai 27B running an end-to-end agentic workflow locally with Hermes on an NVIDIA GeForce RTX 5090 GPU.
The model reasons, calls tools, reads outputs, modifies files, and surfaces insights - all on consumer hardware, while all private files, intermediate states, and iterations remain local.
QuantizedHuman retweeted

Voice cloning models usually trade off between three things: reading the text right, sounding like the target speaker, and staying clear and stable. FlowTTS-GRPO gets a model to do all three at once, using online RL on flow-matching TTS.
QuantizedHuman retweeted

We’ve just released the 1-bit & 4-bit version of Hy3, a flagship-scale 295B model that can be served on a single GPU. 👌
Run Hy3 with llama.cpp, enable MTP, and experience powerful intelligence on dramatically lower hardware.🚀🚀🚀
Can’t wait to see what you build.
#Hy3 #Hy #GGUF #llamacpp

🚀Hy3 is here.
295B MoE. Best in its size class. Rivals trillion-scale flagships.
Reliable and affordable for most agentic usecases.
Apache 2.0. Friendly for commercial use.
FREE API for 2 weeks → openrouter.ai/tencent/hy3:fr…
🤗 huggingface.co/tencent/Hy3
📖 hy.tencent.com/research/hy3
