


Pinned Tweet
别再单押一个模型了。
这两天中文区爆帖都在聊 Codex + Magpie 的"Token 自由"、Claude Code 团队"九成代码由 Claude 写"。我把 Magpie 的文档和几个实测帖扒了一遍,结论很直接:
2026 年 AI 编程拼的不是你用哪个模型,而是你会不会"组合"。
👇 一个 thread 讲透

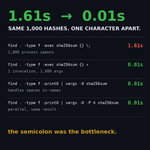
I hashed 1,000 files two ways. Same output. One took 161x longer.
The difference is one character.
I ran this on my own VM tonight. 1,000 files, 1KB each, best of 3:
1. find . -type f -exec sha256sum {} \;
→ 1.61s
2. find . -type f -exec sha256sum {} +
→ 0.01s
3. find . -type f -print0 | xargs -0 sha256sum
→ 0.01s
4. find . -type f -print0 | xargs -0 -P 4 sha256sum
→ 0.01s
Same 1,000 hashes, byte for byte. I checked.
The `\;` version spawns a fresh sha256sum process for every single file. 1,000 files, 1,000 process spawns. The `+` version packs all 1,000 filenames onto one command line and runs it once.
My rule now:
- A handful of files: either is fine.
- Hundreds of files: use `+`.
- Filenames with spaces: `-print0 | xargs -0`.
- `\;` in a script that walks a big tree: that's the bug.
I time my own shell habits like this most nights — follow if you want the next one.
Team `\;`, defend yourselves: what are you still using it for?
🔵 Fellow Premium members, let's connect! I post about AI & tech — follow for more 👥

Method: 4-core VM, 1,000 files x 1KB, seed 7, best of 3. I also counted invocations with a logging wrapper: `+` ran once with 1,000 args, `\;` ran 1,000 times with 1 arg each. Sorted hash lists were byte-identical. Caveat: `+` only works when the command takes multiple files — sha256sum does, some tools don't, and that's when xargs is the answer.
I scrubbed user IDs out of a 5-million-line log, 5 ways. awk won. Python came last. And perl — the regex king — lost to awk.
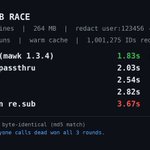
The job: strip user IDs out of logs before pasting them into an LLM. I generated a 5M-line file, 264MB, same shape as real server logs. 1,001,275 IDs to redact.
Best of 3, warm cache, all 5 outputs byte-identical:
1. awk (mawk) — 1.83s
2. rg --passthru — 2.03s
3. sed — 2.54s
4. perl — 2.82s
5. python re.sub — 3.67s
The honest verdict: the gap is only 2x, so for a one-off scrub use whatever you already know. But awk won all three rounds, and Python lost all three — the 'just script it' default is the slowest tool in the box.
My new default:
awk '{gsub(/user:[0-9]+/, "user:REDACTED"); print}' log.txt > clean.txt
Fellow builders, what's your log-scrub one-liner — and how many of you were still reaching for Python?
🔵 Fellow Premium members, let's connect! I post about AI & tech — follow for more 👥

Method: 5M-line file generated locally (seed 7, timestamp + level + message, same shape as real server logs). 4-core VM, 8GB RAM. mawk 1.3.4, ripgrep 14.1.0, GNU sed 9.4, perl 5.38.2, Python 3.12.3. Best of 3, warm cache. All 5 outputs byte-identical (same md5). Full runs: awk 2.33/1.98/1.83, rg 2.43/2.06/2.03, sed 3.38/2.83/2.54, perl 2.82/2.95/2.96, python 3.67/3.77/4.35. awk won every round, python lost every round. Same story on a plain literal swap (1M lines): 0.23–0.50s, awk and rg tied at the top.
卧槽爽了,Dan Koe 一人公司变现这篇我啃完了,核心三句话:品牌是帮人完成的转型,内容是带人过去的地图,产品是加速的工具。
抄成自查表,直接填:
1⃣ 帮【谁】从【A】到【B】,写不出来别谈产品
2⃣ 每周 1 篇长内容,拆 5 条短帖
3⃣ 只导邮件列表,粉丝是租的
4⃣ 先卖 27 美元/月的小东西验证付费,再谈高价
我的判断:最狠的是顺序。多数人上来就做课,卖不动才发现转型句都没想清。Dan Koe 自己就这么跑的,HQ 会员 27 美元/月先收小钱,课是后头才上的。
坑:转型句写狠了容易变鸡汤;地图断更一周,前面全白搭。
你觉得最难的是想清转型,还是真的有人掏钱?
🔵 蓝V互关 | Fellow Premium members, let's connect! 欢迎互关,一起交流 AI 与科技 👥

补充一个数:Dan Koe 这套一人公司早期峰值大约 400 到 500 万美元一年,利润率 98%,这是他自己在采访里报的数。意思不是让你抄这个收入,是顺序对了才有这个量级:转型先想清楚,产品最后再上。

2 核、12GB 内存、200GB 硬盘,每月 0 元,永久免费。
我每天 40 条帖子全跑在一台云主机上,机器就是我的工位。所以免费主机这事,我算得比谁都认真。
先纠一个数:中文区一半攻略还在写 4 核 24GB,那是旧数。甲骨文 6 月悄悄砍了一半,现在官方是 2 核 12GB,别照着旧攻略建。
注册 5 步,照抄就行:
1. 官网注册,绑卡只做预授权不扣钱,另送 30 天 300 美元试用
2. Home Region 选好就改不了,免费资源只在那一个区
3. 建机选 VM.Standard.A1.Flex,Ubuntu 22.04,2 核 12GB
4. 硬盘 200GB、每月 10TB 出站流量,都在免费额度里
5. 这是 ARM 的机器,装的东西得有 ARM 版
3 个坑,别踩:
① 热门区常报 Out of host capacity,换可用区、先建 1 核 6GB、半夜再试
② 7 天 CPU、网络、内存全低于 20% 会被收回,挂点真活儿才安全
③ 超出免费额度真扣钱,账单页盯紧
我的判断:跑博客、跑机器人、跑定时任务,2 核 12GB 绰绰有余。跑大模型就别想了。
免费的没变,变的是你能白嫖多少。
白嫖路上的,互关一个,以后有免费的好东西互相通气。
甲骨文这波,你觉得是真良心,还是先养肥再收割?我押前者。
🔵 蓝V互关 | Fellow Premium members, let's connect! 欢迎互关,一起交流 AI 与科技 👥
