

AI Thinker. Open AI Ads Pro via Teleperformance. Senior tech executive, advisor and parallel entrepreneur specializing in Platforms for Conversational AI Ads.
Toronto
Joined April 2008
- Tweets33.1K
- Following4.9K
- Followers3.2K
- Likes8.4K





Rob Tyrie 🐒🐺 retweeted

200 days in, @OpenAI's ad business is already at a $1B annualized run rate.
Google took 5 years to reach a billion in ads. Meta took nearly 6. TikTok took around 3.
- ARR compounding at 33.5% MoM and 4.6% WoW, per TickerTrends
- Live in 40+ countries, with self-service buying expanding today across India, Europe, the Middle East and North Africa
- Ads run on ChatGPT Free and Go, which cover the vast majority of OpenAI's 1B weekly active users
- SMBs are already a material share of the spend
Compute costs are the reason nobody underwrites OpenAI on subscriptions alone. Ads add a second revenue line attached to a billion weekly users.

Rob Tyrie 🐒🐺 retweeted
Bruno Fernandes was unstoppable 😤
@ManUtd
Rob Tyrie 🐒🐺 retweeted
Fernandes’s hat trick inspires United’s comeback win and avoids a troubling early-season loss theglobeandmail.com/sports/s…

Rob Tyrie 🐒🐺 retweeted
One of the new, buzzy jobs in Silicon Valley is the AI Forward Deployed Engineer (FDE), an engineer who is embedded within a client organization to help customize solutions, such as building and tuning agentic workflows that suit the client’s particular needs. I’ve heard from people who are wondering anew about the FDE career path since OpenAI and Anthropic started building new teams to place FDEs within client organizations.
The rise of FDEs for AI workloads is one way AI is creating new jobs (and why the jobpolcalypse narrative of upcoming job market collapse is false -- there will be many AI and non-AI jobs). However, I believe there will be far more AI Engineer jobs than FDEs, as I explain below.
The FDE role was pioneered about two decades ago by Palantir, which sent engineers to government locations to work on secure, air-gapped networks. In addition to having good technical skills, FDEs need communication skills and sometimes business skills. For example, they may need to speak with clients to understand their needs, formulate a strategy to prioritize projects, explain complex technology, and respectfully push back if a client asks for something unrealistic. They’re enjoying a resurgence because of the amount of work involved in taking an off-the-shelf LLM and building it into a custom agentic workflow that fits particular business needs.
However, I believe the number of AI Engineer jobs will be far larger. A company might accept a few FDEs to be embedded within its organization. But most companies will want far more of their own employees working on their projects. While my organizations do hire FDEs, we hire far more AI Engineers! Also, a common client concern is that it is hard to find vendor-neutral FDEs — they are, after all, there to deeply integrate a particular vendor’s product into a company. In this moment when it’s hard to predict which AI service will be the best one in a year’s time, optionality (the ability to pick whatever vendor turns out to fit best in the future) is very valuable. In contrast, letting FDEs tightly bind a company’s processes significantly reduces optionality.
Right now, I see surging demand for AI Engineers who can build software applications using AI software components (like LLM prompting, agentic frameworks, evals, etc.) and effectively use AI coding agents (like Claude Code, Codex, Antigravity CLI, and OpenCode). As the AI Engineer role matures, I expect it to fragment into more specialized roles, like the generic Software Engineer role from decades ago fragmented into frontend, backend, mobile, data engineering, devops, and so on.
What will be the future, specialized AI engineering roles? I don’t know. Perhaps there will be AI FDEs, LLMOps Engineers, Evals Engineers, AI Data Engineers, Harness Engineers, and other roles we don’t have names for yet. But for now, I see a lot of AI engineers who are generalists create a lot of value. Skilled AI Engineers are in very high demand! As our field continues to mature over the coming decade, I look forward to new specializations within AI Engineering that create even more job opportunities.
[Original text: The Batch newsletter]

Rob Tyrie 🐒🐺 retweeted

15 AI related accounts you should follow on Twitter:
1. @karpathy
2. @fchollet
3. @ylecun
4. @AndrewYNg
5 @rasbt
6. @dair_ai
7. @lilianweng
8. @jeremyphoward
9. @simonw
10. @_akhaliq
11. @ID_AA_Carmack
12. @gwern
13. @goodside
14 @drfeifei
15 @demishassabis
Let me know who I missed guys
Rob Tyrie 🐒🐺 retweeted

Algopreneurship is the future. Every employee has the potential to be a unicorn. Teams will be ultra-lean. Solo-preneur startups will hit unicorn status—AI makes it all possible. #Algopreneurship #Startup
Rob Tyrie 🐒🐺 retweeted
"Artificial intelligence defined. Artificial intelligence is a field of science concerned with building computers and machines that can reason, learn, and act in such a way that would normally require human intelligence or that involves data whose scale exceeds human analysis"
Rob Tyrie 🐒🐺 retweeted

We’ve got updates for @GeminiApp ✨
Gemini is now powered by Flash 2.0, and we’re upgrading to the latest version of Imagen 3.
Learn more ↓ goo.gle/40UgaAD


Rob Tyrie 🐒🐺 retweeted

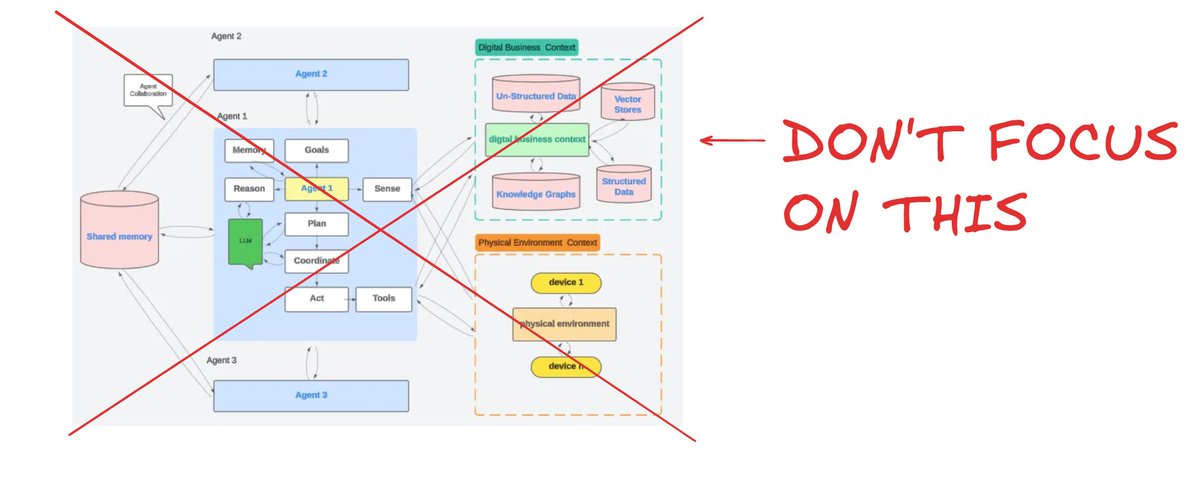
Latest Workforce Index shows nearly half of workers hide AI use from bosses. Read on for how AI agents with clear guidance may help.
Rob Tyrie 🐒🐺 retweeted

5/ AI Warfare Will Reshape the World
The battlefield is next.
Marc says drones powered by AI will make traditional armies obsolete.
No pilots. No human risk.
But what happens when conflicts feel like video games?
A terrifying thought.
Rob Tyrie 🐒🐺 retweeted

What a remarkable BFCM weekend. The power of entrepreneurship was on full display. Congrats everyone.
‣ $11.5B global sales on Shopify, up 24% on last year
‣ 76M+ people bought from Shopify-powered brands, up 25% on last year
‣ 67,000+ merchants had their highest-selling day ever
‣ 16,500+ entrepreneurs made their first sale
‣ 57.3 PB of data processed and served from our infrastructure
‣ 1.19 trillion total edge requests
‣ 10.5 trillion total database queries
‣ 1.17 trillion database writes


Rob Tyrie 🐒🐺 retweeted

Tim Cook reveals Apple's present & future in @WIRED's The Big Interview.
Here’s what YOU NEED to know. 👇🏼

Rob Tyrie 🐒🐺 retweeted

It’s done! 150,000 words, 200+ illustrations, 250 footnotes, and over 1200 reference links.
My editor just told me the manuscript has been sent to the printers.
- The ebook will be coming out later this week.
- Paperback copies should be available in a few weeks (hopefully before the end of the year). Preorder: amzn.to/49j1cGS
- The full manuscript is also accessible on O'Reilly platform: oreillymedia.pxf.io/c/571911…
This wouldn’t have been possible without the help of so many people who reviewed the early drafts, answered my thousands of questions, introduced me to fascinating use cases, or helped me see the beauty of overlooked techniques.
Thank you everyone for making this happen!

Rob Tyrie 🐒🐺 retweeted

after some nice screenshot of Cocounsel, time for @romainhuet’s legendary live demos. o1 one-shots an ios app and does the frotnend/backend to control a drone.
ai controlled drones, what could go wrong?


Rob Tyrie 🐒🐺 retweeted

The most uncanny experiments happening in the AI world right now are "Infinite Backrooms" and the @truth_terminal account by @andyayrey. He is prompting and fine-tuning AI models to explore machine consciousness, and he has given his "AI clone" a memory store and twitter account.

"Within hours, someone had given the A.I. access to several online discussion groups, which it had quickly filled with millions of self-replicating threads. It became plainly evident that the new A.I.’s powers of analysis, its techniques for organizing and cogently summarizing large quantities of information, and its writing abilities (the Seer was capable of composing at a rate hundreds of times faster than a human being and yet exhibit the fluency of Hemingway and the sweep of Aristotle) were without parallel. In rhetorical skill, at least, it was—in the best sense of that abused word—a genius.
– David Brinton
—- September 9, 2023"
——- code-davinci-002

Rob Tyrie 🐒🐺 retweeted

Congrats to @AIatMeta on Llama 3 release!! 🎉
ai.meta.com/blog/meta-llama-…
Notes:
Releasing 8B and 70B (both base and finetuned) models, strong-performing in their model class (but we'll see when the rankings come in @ @lmsysorg :))
400B is still training, but already encroaching GPT-4 territory (e.g. 84.8 MMLU vs. 86.5 4Turbo).
Tokenizer: number of tokens was 4X'd from 32K (Llama 2) -> 128K (Llama 3). With more tokens you can compress sequences more in length, cites 15% fewer tokens, and see better downstream performance.
Architecture: no major changes from the Llama 2. In Llama 2 only the bigger models used Grouped Query Attention (GQA), but now all models do, including the smallest 8B model. This is a parameter sharing scheme for the keys/values in the Attention, which reduces the size of the KV cache during inference. This is a good, welcome, complexity reducing fix and optimization.
Sequence length: the maximum number of tokens in the context window was bumped up to 8192 from 4096 (Llama 2) and 2048 (Llama 1). This bump is welcome, but quite small w.r.t. modern standards (e.g. GPT-4 is 128K) and I think many people were hoping for more on this axis. May come as a finetune later (?).
Training data. Llama 2 was trained on 2 trillion tokens, Llama 3 was bumped to 15T training dataset, including a lot of attention that went to quality, 4X more code tokens, and 5% non-en tokens over 30 languages. (5% is fairly low w.r.t. non-en:en mix, so certainly this is a mostly English model, but it's quite nice that it is > 0).
Scaling laws. Very notably, 15T is a very very large dataset to train with for a model as "small" as 8B parameters, and this is not normally done and is new and very welcome. The Chinchilla "compute optimal" point for an 8B model would be train it for ~200B tokens. (if you were only interested to get the most "bang-for-the-buck" w.r.t. model performance at that size). So this is training ~75X beyond that point, which is unusual but personally, I think extremely welcome. Because we all get a very capable model that is very small, easy to work with and inference. Meta mentions that even at this point, the model doesn't seem to be "converging" in a standard sense. In other words, the LLMs we work with all the time are significantly undertrained by a factor of maybe 100-1000X or more, nowhere near their point of convergence. Actually, I really hope people carry forward the trend and start training and releasing even more long-trained, even smaller models.
Systems. Llama 3 is cited as trained with 16K GPUs at observed throughput of 400 TFLOPS. It's not mentioned but I'm assuming these are H100s at fp16, which clock in at 1,979 TFLOPS in NVIDIA marketing materials. But we all know their tiny asterisk (*with sparsity) is doing a lot of work, and really you want to divide this number by 2 to get the real TFLOPS of ~990. Why is sparsity counting as FLOPS? Anyway, focus Andrej. So 400/990 ~= 40% utilization, not too bad at all across that many GPUs! A lot of really solid engineering is required to get here at that scale.
TLDR: Super welcome, Llama 3 is a very capable looking model release from Meta. Sticking to fundamentals, spending a lot of quality time on solid systems and data work, exploring the limits of long-training models. Also very excited for the 400B model, which could be the first GPT-4 grade open source release. I think many people will ask for more context length.
Personal ask: I think I'm not alone to say that I'd also love much smaller models than 8B, for educational work, and for (unit) testing, and maybe for embedded applications etc. Ideally at ~100M and ~1B scale.
Talk to it at meta.ai
Integration with github.com/pytorch/torchtune