

We're on a mission to make AI truly personal. https://xitter.gq/t.co/FEWPwyEWul
Joined July 2026
- Tweets34
- Following12
- Followers73
- Likes28






Great to see UnslothAI making browser automation more accessible with local models.
At StartLux, we’re exploring the decisions behind these workflows. In our own mock-store demo, StartLux-Decision-27B selects the next page control and assesses whether the task is complete, while our harness executes the actions.
Watch our demo:
xitter.gq/StartLuxAI/status/2106…

Your local LLM can now take control of a browser and complete tasks autonomously via Unsloth!
Qwen3.8-27B successfully controlled the browser to complete tasks like chess, painting, with no human intervention.
GitHub: github.com/unslothai/unsloth
Guide: unsloth.ai/docs/basics/brows…
We’ve been shipping. Here’s what’s out.
🛠️ StartLux-27B
A 27B model for tool use and multi-step task execution. In CAICT’s August 2026 MCP evaluation, StartLux-V1.0-27B-Preview scored 39.25% Overall Micro Pass@1, ranking #2 among six tested models.
⚡ StartLux-Decision
Fast decisions when confident. Deeper reasoning when needed. Model weights and inference code for the StartLux-Decision family are available. On October 16, StartLux-Decision-v1.1 27B reached #1 on the Hugging Face Jev Decision Index 0.3.2 text leaderboard.
🔧 StartLux-Prism
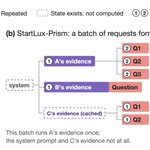
To make decision models easier to use and deploy, we released and open-sourced an inference engine built specifically for StartLux-Decision, delivering up to 5.3× speedup on a single GPU. Faster decision responses. More efficient computation.
🧭 DecisionPivot
A benchmark for evaluating decision-making at key points in LLM systems: whether decisions are correct, whether models still make the right decision when a decisive detail changes, and how much work they can automate at a fixed error rate.
🤖 Made with AI

Explore our models, code, research, and benchmarks 👇
🛠️ StartLux-27B
· Results:
startlux.com/benchmark/
⚡ StartLux-Decision
· GitHub:
github.com/StartLuxLabs/Star…
· Hugging Face:
huggingface.co/startlux-mode…
· ModelScope:
modelscope.cn/organization/S…
· Paper:
arxiv.org/abs/2610.17309
· Technical blog:
decision.startlux.com/
🔧 StartLux-Prism
· GitHub:
github.com/StartLuxLabs/Star…
🧭 DecisionPivot
· GitHub:
github.com/StartLuxLabs/Deci…
· Paper:
arxiv.org/abs/2610.28522
🌐 Find us
Website: startlux.com/
X: xitter.gq/StartLuxAI
YouTube: youtube.com/@StartLux-AI
📬 Get in touch
Media & business: [email protected]
Investor relations: [email protected]
Careers: [email protected]

Thanks for highlighting DecisionPivot, @HuggingPapers!
For practical use, we need to ask how much work a model can handle within an acceptable error rate.
DecisionPivot explores this alongside accuracy and confidence, helping us understand when to rely on a model’s decision and when further review may be needed.


🚀 We’re hiring!
Believe great AI should run on your own devices? So do we. Come build with us! 7 open roles across research, engineering, and product. Find your fit below 👇
📩 Send your CV and work to [email protected]

Thanks to @thePandaily for sharing Prism! We really appreciate the continued interest in our work.

StartLux open-sourced Prism, an inference engine built for decision models: 19 ms per short question on one H200, 2.8x faster than before, with int8 outputs that stay bit-exact and accuracy within 0.03 points of BF16. @StartLuxAI

⚡️ Same model. Same GPU. Up to 5.3× the speed.
Today we’re open-sourcing StartLux-Prism, our dedicated inference engine for decision models.
On a single H200, running StartLux-Decision v1.1 27B AutoThink, Prism INT8 delivers 1.2–5.3× the speed of our vLLM 0.31 FP8 setup across four tested workloads.
• Short question (~256 tokens): 53.1 → 19.0 ms — 2.8× speedup.
• Three questions sharing one context: 92.9 → 17.4 ms — 5.3×.
• The same three questions with reasoning: 1,296 → 785 ms — 1.7×.
• Long question (~8,192 tokens): 531.2 → 439.8 ms — 1.2×.
Accuracy with reasoning stays nearly unchanged: 92.94% vs. 92.97% with BF16 across seven benchmarks covering 12,351 decisions.
Results stay reproducible, too. With fixed hardware and weights, output probabilities remain bit-identical across tested batching and caching configurations.
✨ From models to inference, we’re expanding the local AI stack.
Code:
github.com/StartLuxLabs/Star…
Models:
Hugging Face: huggingface.co/startlux-mode…
ModelScope:modelscope.cn/organization/S…
API:
bamboonode.dev

The final answer-scoring step is smaller, too.
For the 27B model, Prism scores just 26 option letters instead of the full vocabulary of roughly 248,000 tokens. Probabilities normalized over the listed options remain mathematically equivalent to computing the full vocabulary scores first and then normalizing over those same options.
Shared context, computed once. Final answers, scored only where needed.

😊感谢 @NFT_Chen 这么用心的分享!
“把算力花在刀刃上”也是我们一直在努力的方向,期待大家试用~

🤯无敌了!0.8B~27B全尺寸开源!全球最强决策模型StartLux-Decision炸场,算力只花在刀刃上!
StartLux Labs刚发布的StartLux-Decision(覆盖0.8B、2B、4B、9B、27B)彻底改写决策模型赛道:
🔹Instant:一次前向直接出答案,单卡H200中位延迟仅25-52ms,快到离谱。
🔹AutoThink:有把握就秒答,没把握才短推理,智能分配算力。
🔹原创RLCD²:用冻结模型+Proper Scoring Rule打分,奖励“概率变准”,软性惩罚过长推理 → 平均推理长度最多缩65%,长度上限内完成率最多提48个百分点,准确率几乎不掉。
🔹Decision Index 0.3公开榜断层第一:各尺寸Instant同规模最强开源模型高7.4~16.9分,27B AutoThink直接冲到73.4。
🔹全新基准DecisionPivot(只改一个关键细节答案就翻转,可程序化验证):AutoThink成对准确率比Instant再高11.5~18.4个百分点,全场领先。
🔹全栈友好:vLLM / llama.cpp / MLX全支持,GGUF + MLX 4/8-bit量化版,Mac也能跑。
3步本地起飞:
1️⃣git clone github.com/StartLuxLabs/Star… && cd StartLux-Decision && pip install -e '.[vllm]'
2️⃣hf download startlux-models/StartLux-Decision-v1.1-4B-AutoThink --local-dir models/4B
3️⃣startlux-decide serve --model models/4B --launch-vllm --gpus 0 --port 8090
代码Apache-2.0,权重CC BY-NC 4.0(商用另洽),兼容TypeSafe /v1/systemone,Agent直接无缝接入。
决策模型的新王已至,谁还在用通用大模型硬判?
🔗 GitHub:github.com/StartLuxLabs/Star…
📄 论文:arXiv 2610.17309
#大模型 #开源模型 #人工智能 #强化学习 #LLM #AIAgent #决策模型 #StartLux #RLCD2 #AutoThink


Lovely to see our work featured by @thePandaily. ☺️Thanks for helping more people get to know StartLux!
Can AI keep up with a Tesla Roadster in midair? 🏎️
An AI Blogger Woyin AI (沃垠AI) tests StartLux-Decision on a 14-second clip, making 31 requests and receiving 155 judgments, 71 of which trigger reasoning. The reported model request latency is 62ms.
StartLux-Decision supports high-frequency decisions on continuous visual or text inputs. It makes fast judgments and reasons further when needed.
What would you test next? 😉
Models & code:
github.com/StartLuxLabs/Star…
Thanks to @Chinazhidx for highlighting StartLux-Decision and our latest results. 💪 We’ll keep pushing forward.

🔥Chinese AI startup StartLux has topped Hugging Face’s Decision Index 0.3.2.
StartLux-Decision v1.1 27B scored 69.12, leading the next model by 2.86 points.
It’s the only model above 69 in the 173-model table.
It’s a 27B open-weights decision model: give it a state (text, JSON, up to 8 images) and typed questions with listed options, and it returns a probability for every option in one forward pass without generating text.

Decision is harder. But now we’re setting the pace.
🚩StartLux-Decision v1.1 27B is now #1 on the Decision Index 0.3.2 text leaderboard.
• Full Score: 69.1. Public and private evaluations.
• We’re building AI that can make fast decisions when confident, and reason further when needed.
• Model weights and inference code are available.
View the results:
huggingface.co/spaces/multim…
Put our models to work:
github.com/StartLuxLabs/Star…

Most models generate. Decision is harder.
Today we’re releasing the latest StartLux-Decision models:
a family of decision models built for fast choices and deeper reasoning.
• Instant: single-pass decisions, from 0.8B to 27B
• AutoThink: adaptive reasoning, from 4B to 27B
#1 among evaluated models on the public subset of Decision Index 0.3.
Our AutoThink 27B scores 73.37, outperforming Jev (hosted) by 15.41 points.
Model weights and inference code are now available:
github.com/StartLuxLabs/Star…
Free API testing of AutoThink 27B is also available through a third-party platform:
bamboonode.dev/

Longer reasoning isn’t the goal. Better decisions are.
We introduce RLCD², our reinforcement learning approach for StartLux-Decision AutoThink.
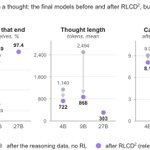
Instead of rewarding longer reasoning, RLCD² rewards improvements in decision probabilities while discouraging unnecessary computation.
On AutoThink 9B:
• 65% shorter reasoning traces (2,494 → 868 tokens)
• Normal termination: 45.9% → 93.9%
• Held-out decision accuracy remains stable
Better decisions. Less unnecessary reasoning.
Full method, reward design, and experimental results:
arxiv.org/abs/2610.17309


StartLux Community Showcase ✨
“Switch to the yellow T-shirt.” And just like that, it switches!
A developer in our community built HELURIO Kids Fit, a voice-controlled virtual try-on demo using StartLux-Decision-4B.
The model runs locally on a MacBook with an M5 Pro, making clothing-selection decisions in around 100 ms.
It's exciting to see what people are building with StartLux-Decision.
Check out the demo below!
Project: github.com/heliosli6767/helu…
Thanks to @ChinaDaily for highlighting our work on StartLux-Decision. This is another step toward making powerful AI more useful in everyday life and work.

A new #AI model is taking a different approach to helping AI agents make decisions.
Developed by Shanghai-based AI company StartLux, StartLux-Decision scored higher than Jev 1.13 in 31 of 38 benchmarks, according to the company. Its 27B version was developed and validated in just three days.
The model uses an "Auto Research" system, in which AI helps generate hypotheses, run experiments and analyze results. Its code and model weights have been made open source.

Introducing StartLux-Decision — a family of open-weight models for fast, local decision-making.
· Decision performance: 27B scores 63.88 on Decision Index 0.2.1, ahead of Jev 1.13 on 31 out of 38 benchmarks.
· Accuracy: 27B averages 91.82% across the seven test suites used by Intern-Decision, compared with Jev’s 88.74% and Intern-Decision-4B’s 90.02%.
· Speed: In our short-request test, 4B handled three decisions in a single request, averaging 26 ms.*
· Local deployment: Five dense sizes (0.8B–27B), with original and GGUF weights. On Decision Index 0.2.1, our 0.8B, 2B, 4B, and 9B models exceed the highest public leaderboard score at each respective size; 27B exceeds the overall leader, Jev 1.13.
Models:
huggingface.co/collections/s…
Code & results:
github.com/StartLuxLabs/Star…
Self-evaluated results; Jev comparison uses the September 28, 2026 public leaderboard.
*Short-request test on one H200, BF16, with fast kernels and CUDA graphs enabled.

Decisions in action: StarCraft II.
In this demo, StartLux-Decision-27B guides a Terran bot to victory against the game’s built-in Hard AI. The model chooses what to build, which units to prioritize, and whether to attack, defend, or gather. A scripted bot handles execution.
Watch the decisions and their probabilities in the video below.
Try StartLux-Decision. We’d love your feedback.
Original checkpoints are available across the family, with GGUF versions for all five dense sizes. The repository includes inference code, evaluation scripts, raw results, and fine-tuning tools.
Code: Apache-2.0.
Weights: CC BY-NC 4.0 — research and other non-commercial use with attribution. Commercial use requires a separate license.
Get the model
huggingface.co/collections/s…
Quick start
github.com/StartLuxLabs/Star…