

Ph.D student at @Princeton | Formerly @JohnsHopkins ’25, @HopkinsDSAI @JHUCompSci @jhuclsp @CCVLatJHU | AI/ML/NLP/CV
Princeton, NJ
Joined June 2024
- Tweets35
- Following667
- Followers413
- Likes49




How do you find the best agentic reasoning strategy for a given task?
We introduce Strategist, an agent that evolves better llm reasoning strategies as Python programs, storing each one in a library so the next task can start from it.
Yes, chain-of-thought was invented by human, but the next one might not be!
Details in thread 🧵

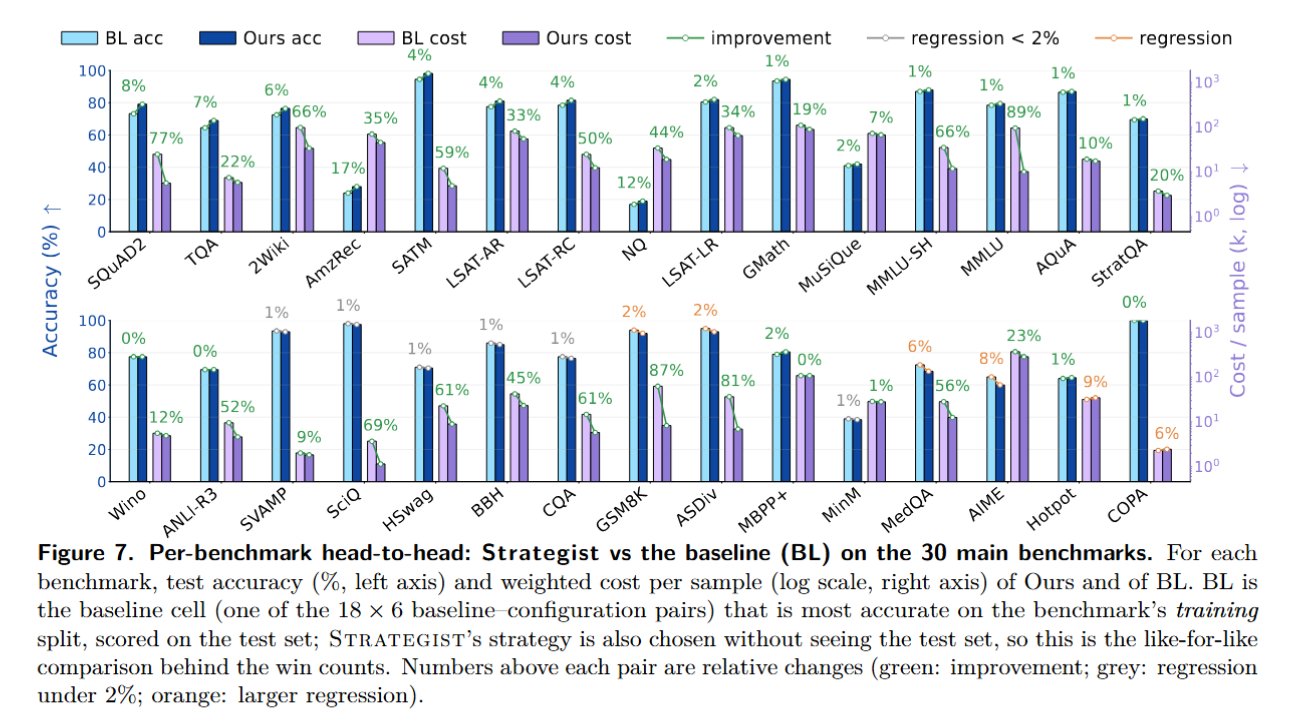
On 30 benchmarks, Strategist beats the strongest hand-written baseline on 24, with the same average accuracy at 39% lower cost.
On 10 new tasks, the library alone, with no search, is more accurate than the baseline on 8.


We will present the paper at NeurIPS this December!
Paper: arxiv.org/abs/2611.03618
Thanks to Qi Xu, Zhigang Hua, and @liuzhuang1234 for the support!
Try it on your own tasks? We’d love to see what it finds.

On 30 benchmarks, Strategist beats the strongest hand-written baseline on 24, with the same average accuracy at 39% lower cost.
On 10 new tasks, the library alone, with no search, is more accurate than the baseline on 8.


2
136
We will present the paper at NeurIPS this December!
Paper: arxiv.org/abs/2611.03618
Try it on your own tasks? We’d love to see what it finds.
5
141
Taiming Lu retweeted

You want a strong small LLM. Would you start small — or inherit from something bigger?
📄 New paper: Small LLMs: Pruning vs. Training from Scratch
We find that pruning is more than a better initialization: simply giving randomly initialized LLMs more training tokens is often not enough to catch up.

Taiming Lu retweeted

Can a small academic team build a strong text-to-image model using only public datasets?
Introducing i1: a simple, fully open recipe for strong text-to-image models
Knowledge doesn't always flow downhill.
We find that in LLM pretraining, a weaker teacher can improve a stronger student, and pushing the teacher further can actually hurt.
New paper: Strong Teacher Not Needed? On Distillation in LLM Pretraining.

ALT A weaker teacher can still help and an overly strong one can hurt — what matters for distillation in LLM pretraining is teacher–student compatibility, not raw teacher strength.
Distillation improves generalization more readily than in-domain fit.
Out-of-distribution perplexity and downstream accuracy improve more consistently than in-domain perplexity, where some configurations help OOD/downstream while doing nothing for in-domain.

ALT As α grows, in-domain improvement collapses onto a single curve in teacher loss, but OOD and downstream split by architecture, meaning teacher train loss alone is a misleading proxy for teacher quality.
Teacher–student compatibility matters more than raw teacher strength.
This changes how you pick a teacher: both for frontier training (where the best available teacher is often a prior generation) and for efficient small models, where "bigger teacher is better" isn't the right rule.
Thanks @liuzhuang1234 for the support!
arxiv: arxiv.org/abs/2605.23857
code: github.com/zlab-princeton/st…

ALT See our paper for more details.