

llm psychosis 1.0 survivor circa sonnet 3.5
Joined February 2010
- Tweets11.4K
- Following76
- Followers1.1K
- Likes5.8K



Pinned Tweet
Exploring Direct Tensor Manipulation in Language Models: A Case Study in Binary-Level Model Enhancement: areu01or00.github.io/Tensor-…
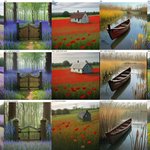
Weight space programming on image model : SDXS-512
Agent edited 0.00017% of the network to turn flat postcards into scenes you could walk into. No training.
Recipe to reproduce in comments below.
Point your agent to the comment :
Recipe, 768 weights, no training
Model: SDXS-512 Dreamshaper, a one-step text-to-image model (CLIP text encoder -> UNet -> tiny VAE, 441M weights).
Edit: one tensor, text_model.final_layer_norm.bias, the 768-value additive term in the last layer of the text encoder. Every token slot passes through it, so a change here shifts all 77 text slots the UNet reads.
How the change is computed:
1. Take 20 everyday prompts (portrait, animal, food, landscape, interior, etc.).
2. Encode each prompt twice with CLIP, once as is and once with this appended: ", candid photograph, natural light, muted colors, film grain, soft shadows".
3. Subtract the plain encoding from the styled one. That gives a 77x768 difference per prompt.
4. Average over the 20 prompts, then over the 77 slots. That leaves one 768-value offset vector.
5. bias += 0.5 * offset. Save the text encoder.
That's the whole edit: 0.00017% of the weights, 3 KB of a 1.76 GB model. The UNet and VAE are untouched, and the prompt you type stays the same.
What it does: the camera drops lower, focus separates into foreground, subject and background, and colour gets calmer. Typing those same words into the base model only mutes the colours, layout and depth stay the same, because appended words can't change the slots before them.
Limits: 0.5 is near the ceiling (faces start to blur at 0.6, images collapse at 1.0). Paintings drift toward the same muted look. The video is hand-picked from ~150 renders, and it works best on scenes with something tall up close. No new ability, just a different default.

5
238


Weight Space Programming: a glimpse into continual learning.
Agent edited Qwen 0.8B's weights to inject facts about my X profile directly into the model: my handle, bio, GitHub, and what i build. It edited 2% of the network (5 of 488 tensors). No training, no gradients.
Result:
Before, it had never heard of me ("I don't have access to private information…").
After, it tells you who i am, my bio and GitHub, answer project questions it was never trained on. Everything else it knew is untouched.
Reproduce : Link to reproduction repo in comments. Point your agent to the repo and teach model your own facts.
Hand this to your agent:
repo: github.com/areu01or00/qwen0.…
What it does, closed form, zero gradients:
- reads the activation entering mlp.down_proj (the "key") at every answer-token position, layers 17-21
- target per token = that token's output embedding, scaled by how far the model is from saying it
- per layer: dW = R Kp^T (lam*Kn Kn^T + Kp Kp^T + mu*I)^-1 Kp = answer keys, Kn = keys that must not move (~40 general Qs + your contrast set at 10x), lam=3 - spread bottom-up across 5 layers; each layer delivers its share of what's still missing - closed loop: the edited model answers on its own, finds the first token where it drifts, re-solves with that token pushed harder (boost capped 10x, ≤6 rounds)
- saves a normal HF model folder. 5 of 488 tensors differ, everything else is byte-identical
Knobs: --layer (top edited layer, default ~87% depth), --spread (how many layers, default 5), --lam (higher = more local, weaker write)

weight space modding is going to unlock so many robotics usecases holy shit
Task: edit Depth Anything V2 Large's weights directly to improve edge detection.
Result : It now finds 41% more of the real depth edges. About 0.35% weights edited.
Weight space harness in action in comments below and how to reproduce (no code needed because mods are THAT easy)
How to reproduce, no code needed, paste this into your agents:
In the DPT head, take the 3×3 kernels of refinenet1.resConfUnit2.conv2 and refinenet2.resConfUnit2.conv2. Split each kernel into its smooth part (best fit of a flat value plus a left-right and up-down ramp) and the rest, the curvature that responds to edges. Boost the rest: ×1.15 in refinenet1, then scale that whole kernel ×1.3. ×1.5 in refinenet2.
That's it. Every other weight is unchanged.
10
311
Tensor-Slayer retweeted

One more zero-order FineWeb-30M speedrun record: 3.5 val loss in 14.2s on one 8xH100 node
Down from our previous 22.9s (#52) record, ×1.64. The stepping stones:
🟠 22.7s: #52 rerun. Identity-path phase, then Cut with single roots at blocks 4 and 6, fused chain kernels, one CUDA graph per estimate.
🟢 19.9s (×1.14): 16-row updates. From 10% of Cut on, each GPU estimates two rows natively in one graph, with one gradient exchange and one optimizer step per 16 rows. Same rows, same order, half the updates. On the way, the end merge became a per-part fit inside the run: each weight matrix gets its own pull toward the weight average, fit on held-out rows.
🟣 17.4s (×1.3): Kernels and a cheaper root. The chain kernels moved to tensor cores (wgmma), we added Gluon FA3-style kernels for value credits and the key scan, and weight credits went to bf16. Root 4's replay is ~40% of each estimate, so early in Cut it now runs only on every 2nd update and its measured deviation counts twice.
🔵 14.2s (×1.63): The systems tail. A pruned top-k that matches the old one bit for bit, gathered value tables (16 MB instead of 268 MB), RoPE-rotated keys, bf16 recompute that we checked with training runs, rank-major ANVIL with overlapped graphs, and per-head q/k polar from CharlesDDDD's #54. Time per Cut row fell from 1.76 ms to 1.07 ms.
One lesson from what failed: cheaper root estimates (token subsets, control variates, importance sampling) all lost. Bias cost more than noise, and noise late in training cost more than offline gradient checks predicted. Forward-only credit seems to need its signal most at the end.

PAW = generating .paw which is basically packaged LORA weight updates (derived through synthetic input output pairs through the base model), metadata and instruction about the adapter which is bolted on top during inference.
You describe a task in natural language > the model generated synthetic data > LORA > .paw > inference + .paw
TS takes fundamentally a different approach. No synth, no data, no training, no LORA, no RL.
Describe intent - for eg : “improve reasoning by scaling test time compute” > this input goes to “Mother” LLM ( i am not calling it teacher or trainer because it does none of those things that conventional wisdom expects of teacher model) along with + Tools to access weights of target (Base LLM) .
> Tools include : low level memory operations, base LLM weights, activations, Logit lens
> The Mother LLM edits weights of the target LLM based off of its internal knowledge. Operations such as : Scale particular layer by 1.2/0.85x or scale just top 10% of MLP by 1.05x, or apply sigmoid, or normalise , clamp up/down etc
> The operations are applied at runtime using pt hooks.
You can see in the below example how “improve reasoning” task made the base model ……improve.
xitter.gq/tensorslay/status/1936…
1
25
I am upgrading tensor slayer framework with GEPA + DSPy
The old framework used @DSPyOSS alone to scale test time compute (no RL/no datasets/no FT/ no prompting)
The mother LLM makes architectural changes to the target LLM like shown below.
Why GEPA ? : I have gathered enough data about MLP layers which can be used as examples and fed to mother LLM to modify architecture of target LLM during run time.
30
Tensor-Slayer retweeted

Neural Thickets (@yule_gan @phillip_isola): add random noise to an LLM's weights, keep the best copies, let them vote. Reasoning jumps, no training.
Why does it work? It's sampling in disguise. Swap noise on billions of weights for one random vector on the logits: same gains 🧵

