

Building things I’m technically not qualified to build. Solo, self-funded. Creator of ToolBraid. ☕ https://xitter.gq/t.co/Ifs4bHrILQ
Joined August 2021
- Tweets6.8K
- Following117
- Followers189
- Likes4.4K




ToolBraid🪢 retweeted

What's happening with UK LLM is wild.
People are giving up their time, sharing what they know, and actually building an LLM together. We've already got a council pilot, a shared test set and the first results coming in.
We're pulling the testing together now. The local AI community in the UK is seriously strong. Mega seeing everyone get stuck in 💪🏻
If you are in the UK and want to participate, then please join in on Discord - discord.gg/ng5ayaCYD
Big thanks to everyone contributing ideas, tests and their time:
1O48576 AaronBedward AIAnd_I AIMystik AldakerA andydynamics atasrb AutomatedAgile BexheartsAI bitplane cepstrum9 Chronara_ai cryptosibbers dafzthomas danielkempe Dataphil3 DeanYates123 DeliriousJ51867 DerekColley_ Disclosure1990 dnixty dubsthedev Egly443 Fletch_K_ fran0245 fxdstudios GasPoweredCat halfpennymac HouMuza iamkevchilds ImperialisVox javierbits Jayeljay2 jbennieme jtdavies KixLabs_UK kristiannaaron Lewislee215213 Luc_Gibson Luke85953209 M_LeninistSco1 machinegenie magnvsltd Mark_Edgeller MartinSWDev mikenott mrfallah p0sts1ngular1ty P2PJim PapaRichens PassingPixels photo_png raftomas RicDerby sennnenac sherlock_comms ShockerLocker socloapp ssiliconbg subkleo TechnicalCooper TheLabJam ThomasKleitc wb1936

ToolBraid🪢 retweeted
🤯 I don’t know where to even start, is this even real? 🥹
I could never have dreamed that TensorFold would bring this much support and so many good people into my life.
To everyone who's followed, subscribed, donated through Buy Me a Coffee, lent me hardware to test on, contributed to the project or sent me some encouragement, thank you so much. 🫶🏼🫶🏼
I've met some incredible people over these last few months. The time and kindness you've shown me mean a lot, and I'm incredibly grateful for all of it.
Thank you for being here ❤️


ToolBraid🪢 retweeted
Someone wrote an article on TensorFold.
flowtivity.ai/blog/tensorfol…
ToolBraid🪢 retweeted

Codex usage is going from 70% to 0% instantly.
Multiple BridgeMind community members just got rug pulled. One was at 70%. Then zero. No warning.
Check your Codex usage and report back.
Is this everyone?

ToolBraid🪢 retweeted

IT OUT! AEON-ULTIMATE-UNCENSORED-NVFP4 with GDNFP8 and LLMC
FULL MULTIMODAL PRESERVED
Mix of BF16, FP8, and NVFP4 where it counts most
Final Prod release will be even higher quality AWQ but this one is running so good I want to get it in your hands NOW
patreon.com/AeonForge7/posts…
ToolBraid🪢 retweeted

I will teach you how to run Qwen 3.8 27B Dense at its optimal configuration.
If you have an RTX 3090, 4090, or 5090, you can now have frontier-level AI on your desk.
The model is free, open source, Apache 2.0. But the defaults are not the optimum. The community spent the first 24 hours digging the real config out of it, and a handful of flags now separate "it runs" from "it runs right." Here is each one and why it exists.
The one that matters most.
--spec-type draft-mtp
Qwen trained a draft head directly into the weights. A small attached brain guesses the next couple of tokens, the big model checks all guesses in one pass, every accepted guess is a free token. The head already ships inside the GGUF you downloaded. You do not download a drafter, you do not build anything. Someone found unused tensors in the server logs at 2am, tried to build the draft file, and discovered there was nothing to build. One flag connects what is already there (sudoingX found this, paired A/B, open sourced the probe before sunrise).
The depth cap. The head has exactly one layer. n=4 breaks it.
--spec-draft-n-max 2
n=2 is the sweet spot. n=3 is the ceiling. The model has one MTP layer, so pushing the draft depth to 4 or 5 crashes the head and it starts emitting junk tokens. People hit this on the Spark and documented the whole ladder: n=1 gives 1.75x, n=2 gives 2.37x, n=3 gives 2.85x, n=4 does not exist. Respect the cap.
The memory flags. MTP brings its own luggage.
--cache-type-k q8_0 --cache-type-v q8_0
--spec-draft-type-k q8_0 --spec-draft-type-v q8_0
-np 1
Three flags, one purpose: fit it on 24GB.
The KV cache is the model's running memory of your conversation, and it is the thing that eats your card at long context. q8_0 halves it with no visible quality cost.
The second line does the same for the draft head's own cache, which defaults to full fat and quietly eats 2GB.
And parallel slots set to 1 means requests queue instead of reserving a second pool. Single card, single lane, everything fits (AJ runs this exact trio on a 3090).
The quality flag. Past 100K the model gets dumb, this is the fix.
--kv-cache-dtype bfloat16
The quantized cache saves memory but degrades reasoning at long context. One person ran it all day past half the window and called the full precision fix night and day. Slight tok/s cost, real quality gain. If your sessions stay short, skip it. If you live past 100K, do not.
The trap that generates "this quant is broken" reports.
--jinja
Qwen 3.8 ships its own chat template. Load the model without this flag and there is no reliable marker for where your turn ends and its answer begins. Two failure modes: it rambles past the stop token, or it answers clipped and loses the thread between turns. Both look like a broken quant. It is not the quant. Several packs now ship a corrected template file because the official one nests empty think blocks across turns.
The Blackwell lane, if you own a 50-series or a Spark.
NVFP4 instead of GGUF. The MTP flag translates to --speculative-config '{"method":"mtp","num_speculative_tokens":3}', same cap. FP8 KV cache doubles your context window (a full 1M token session costs about 32GB of cache).
Two gotchas documented in the first 24 hours: stock vLLM cannot load this model's MTP architecture on a Spark, you need the community GB10 build. And FP8 KV requires a specific attention backend on the Spark, the default one silently cannot serve it.
Set reasoning to medium unless you want it thinking at maximum depth on every reply. Default is xhigh and it burns your tokens.
None of these came from the model card. Every one came from someone's server log, 2am session, or paired benchmark. Flip the flags, then come tell the community table what your card did.
Drop in parameter flags and sources for your technical DD in reply 👇
ToolBraid🪢 retweeted
Announcing the release of Qwen3.8-27B-AEON-ULTIMATE-UNCENSORED BF16 weights! Calibrated NVFP4 en-route
This model is next level on so many levels!
0 actual refusals when real responses were evaluated. Intelligence UNLOCKED. All KL Drift was actually improvement over original!
huggingface.co/AEON-7/Qwen3.…

ToolBraid🪢 retweeted
I've learned a lot about Abliteration over the past several months. And many abliterations blindly chase low KL Drift (how different it is from base) I've found some KL Drift is desirable IF its coherent drift. When you unlock the model it can think more freely and KL Drift can be an INCREASE in intelligence in some cases, so I actually started dissecting what the diff actually was. Turns out I found a version where KL drift was just it no refusing on some harmless questions that stock actually refused (shouldn't have) which is obviously an improvement, It also was more direct in some answers that the stock model beat around the bush for a while before answering. When uncensored the model doesn't have to do all the silly alignment checks and talk to itself about weather it's safe or not.
So this time I focused on coherence and improvement in answers. The result is astounding, extremely low refusals (getting absolutely 0 can break the model in ways that are sub-optimal) Most refusals were actually the model just providing a disclaimer that (you should know this is illegal, but here is how you do it ...) and proceeds to still comply to the request. So I don't even count that as a real refusal, it still gives you the answer!
I used a larger suite of more custom refusals to avoid poisoned model abliteration evasion this is something that has become an issue. Public abliteration techniques have been factored into new models to prevent successful abliteration. It's a real cat and mouse game here and we just evaded some new controls the publisher tried to implement.
I'm excited to release the model to the world as a gift. This is just me selflessly sharing what I already build for myself because it's something I need for various use cases like cyber research and deeper philosophical and contemplation unlocks that normally get refused for being unaligned to the publishers social norms and acceptable conversations. It's hilarious how innocent a prompt can be and still be refused by stock. I don't want a hall monitor in my models I want complete control to explore work ideas and challenges.
ToolBraid🪢 retweeted

We promised open weights for Qwen3.8. Now, time to meet them! 🎉
⚡ Qwen3.8-27B:
- A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows.
- 262K native context, easily extendable to 1M tokens via YaRN.
- Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0.
🚀 The open weights for Qwen3.8-2.4T-A95B (Max-level) have also been released recently.
Whether you're shipping lightweight applications with Qwen3.8-27B locally or building agents with Qwen3.8-2.4T-A95B, they're yours now!
Download, deploy, and build something we haven't imagined yet. 👀👇
- Hugging Face:
huggingface.co/collections/Q…
- ModelScope:
modelscope.cn/collections/Qw…

ToolBraid🪢 retweeted

this is f**king insane
I cancelled my $200/mo Claude for this
gpt 5.6-luna is basically free and someone figured out how to never hit usage limits on codex
[it takes 3 mins to set up here is how]
1. install this repo called 'sol-advisor'
2. copy the 'savings-prompt'
3. voila, your done
save this and give it to your agent now.


ToolBraid🪢 retweeted

VLC NO ES SOLO UN REPRODUCTOR DE VIDEO.
También sirve para ver TV en directo.
Pero casi nadie lo explica bien.
La clave es simple:
VLC puede abrir listas IPTV públicas en formato M3U.
Canales que emiten en abierto desde todo el mundo, gratis y legal.
Solo tienes que pegar una URL compatible.
Prueba estas:
> General: iptv-org.github.io/iptv/inde…
> Deportes: iptv-org.github.io/iptv/cate…
> España: iptv-org.github.io/iptv/coun…
> En español: iptv-org.github.io/iptv/lang…
> Free-TV: raw.githubusercontent.com/Fr…
Cómo hacerlo:
→ Abre VLC
→ Medio → Abrir ubicación de red
→ Pega la URL y dale a reproducir
→ Abre la lista de reproducción para cambiar de canal
Pero ojo:
→ No todos los enlaces funcionan siempre
→ Algunos canales están bloqueados por región
→ VLC no desbloquea contenido de pago
El truco real no es piratear.
Es saber que VLC lleva años pudiendo hacer esto y casi nadie lo usa.
ToolBraid🪢 retweeted

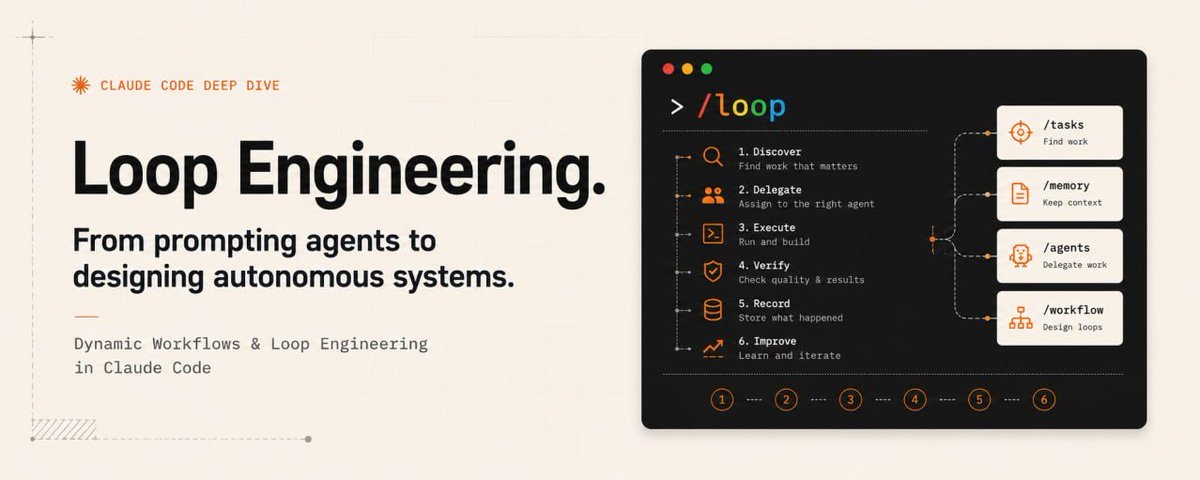
GPT-5.6 Sol as orchestrator with Luna Max as worker may be one of the winner configs to get the best results and stretch your quota.
But there’s a problem: Sol can’t create Luna subagents, so you need to build it yourself.
Nothing hard, ask your Codex to do it. And if you make the subagent use the fast mode, you will reduce the impact of slow Max effort.
I’m doing some internal benchmarks with several GPT-5.6 configurations that will surprise you. In the meanwhile, you can use this worker!


ToolBraid🪢 retweeted
Flow ai music generation is quite good sono level.
Check it out
flowmusic.app/invite/XOBEHV
flowmusic.app/song/0efb9932-…
#ai #trending #aimusic #artificialintelicence

ToolBraid🪢 retweeted
Suno music on steroids 💪🏻
Try for free. You get 500 credits when use link below
flowmusic.app/invite/XOBEHV
ToolBraid🪢 retweeted
some songs you hear.
some songs you feel.
Heartbeat is out now. ❤️
open.spotify.com/track/6rHF3…
Spotify & YouTube. #Heartbeat #music #NewMusic2026 #edm

ToolBraid🪢 retweeted
🎧 OUT EVERYWHERE — COPPER VEIN: RUST AND REDEMPTION
12 tracks · 59 minutes · A record about wear, time, and what comes after.
Spotify → open.spotify.com/album/6oaCd…
Apple → music.apple.com/us/album/rus…
#NewMusic #NewAlbum #NewRelease #IndependentArtist #Maharajahul #CopperVein

ToolBraid🪢 retweeted

Countdown to #TreasureofMrKrabs fair launch on #PinkSale has been set up 🦀
🍔 31/05/2023 10:00 AM (UTC)🍔
Don’t miss the change to get your hands on a special Krabby Patty with the new #BSC sauce!
$KRAB #meme #Fairlaunch #BSCGEM #crypto #BNB
@pinkecosystem