
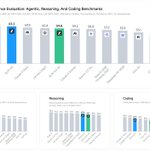
RT @HongyangZhang: We recently conducted an evaluation of algorithmic reasoning — the inputs are generated by executing an algorithm on a g…

Kudos to @jietang and @Zai_org! GLM-4.5 delivers impressive quality and speed — and huge thanks for open-sourcing it!

Introducing GLM-4.5 and GLM-4.5 Air: new flagship models designed to unify frontier reasoning, coding, and agentic capabilities.
GLM-4.5: 355B total / 32B active parameters
GLM-4.5-Air: 106B total / 12B active parameters
API Pricing (per 1M tokens):
GLM-4.5: $0.6 Input / $2.2 Output
GLM-4.5-Air: $0.2 Input / $1.1 Output
Tech Blog: z.ai/blog/glm-4.5
Weights: huggingface.co/zai-org/GLM-4…
Z.ai API: docs.z.ai/guides/llm/glm-4.5
OpenRouter: openrouter.ai/z-ai
Develop Tools: docs.z.ai/scenario-example/d…
Try them now: chat.z.ai

1
4
716
GLM-4.5 is shaping up to be a serious open contender:
⚔️ Competes with OpenAI O3, Claude 4 Opus, Grok-4
🧠 355B total / 32B active (Air: 106B / 12B)
🧩 128K context + native tool use
🛠️ Hybrid "thinking" & "non-thinking" modes
📚 Trained on 15T general + 7T code/reasoning tokens
1
1
243

Sen Wu retweeted

2024 was all about momentum. 🚀
We turned questions into answers, saved hours that felt impossible to reclaim, and let our agents do what they do best: turn raw data into real impact.
In 2025, we're raising the bar again.
Here’s to making 2025 even smarter, faster, and more data-driven. ✨ We’re just getting started.
See you next year!

Sen Wu retweeted
Numbers Station Labs is extremely excited to release Meadow, the first and simplest agentic framework built for complete data workflows. Meadow is fully open source! 🪴💪🏼
Results against benchmarks below 🧵↓
numbersstation.ai/introducin…
Thrilled about our excellent teamwork with @motherduck @tdoehmen @laurel_orr1 ! Can't wait to see how much the community benefits from this open-source model!

🎉 Introducing DuckDB-NSQL 🦆🧠 w/@MotherDuck!
A ducking LLM for local analytics that outperforms others by 20+ points in DuckDB-specific queries 🤩
🌍💻 Open source & runs on your laptop!
GitHub tinyurl.com/mr2s59v7
🤗 tinyurl.com/yznbxnz8
Blog ⬇️tinyurl.com/4ut3drm2

13
614
Sen Wu retweeted

Excited to share our paper “Cross-Domain Data Integration for Named Entity Disambiguation in Biomedical Text,” which appeared this week at #EMNLP2021!
Paper: arxiv.org/abs/2110.08228
Code: github.com/HazyResearch/medi…
Data: huggingface.co/datasets/mvar…

Sen Wu retweeted

To what extent can we match proposed architectural modifications for incorporating knowledge, using only simple changes to the data? How can we understand why data modifications will be effective? @Wu_Sen @HazyResearch and I explore these questions in: arorasimran.com/static/media…

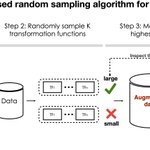
1/4 Excited to share our work that formally explains some of the mysteries behind data augmentation -- along with SoTA results on CIFAR! Joint work w/ @HongyangZhang, Greg Valiant, @HazyResearch. Paper at #icml2020: arxiv.org/abs/2005.00695. Code: github.com/SenWu/dauphin.

4/4 Credit to TANDA (NeurIPS’17 @ajratner), AutoAugment/RandAugment from Google, and Adv. AutoAugment (ICLR'20) that inspired our work. Would be interesting to also study the impact of data augmentation on robustness @hendrycks. Feedback welcome! Blog: hazyresearch.stanford.edu/da….
6
Sen Wu retweeted

Built upon the weak-supervision framework Snorkel from @HazyResearch , Fonduer is a powerful framework for extracting knowledge from documents and making them structured. Wanna know more? Tutorials are available at github.com/HazyResearch/fond…

Sen Wu retweeted

Super excited to release #HoloClean as an open source project under Apache license. #MLforDataEnrichment. Check it out and download from holoclean.io. proud to be part of this awesome team.
Sen Wu retweeted

Get hyperbolic about your relationships! Exploring the limits of embedding your databases, graphs, and structures in low dimensions using hyperbolic embeddings: stanford.io/2u1tvtE https://xitter.gq/t.co/PSc6s794jE
Sen Wu retweeted

New blog post - Structure Learning: Are Your Sources Only Telling You What You Want to Hear? hazyresearch.github.io/snork…