






Pinned Tweet
Finishing two weeks of tabular DL announcements with the python package for TabPack 🏎️


👂 👀
Go see and talk to Dima about their latest work!

This Monday, Nov 2, Dmitry Baranchuk (@DmitryBaranchuk) will present his paper:
Representation-Space MMD for Diffusion Language Models
Project also co-led by Ilya Drobyshevskiy (@free001style) and Ilia Sudakov (@sudakov_il)!

One more tabular ML release from our researchers, and a third one coming soon!
Stay tuned 🥠

I've long argued for more diverse evaluation setups in tabular ML research. This will continue. It was a key motivation behind our new paper
A thread on data scaling in MLPs, GBDTs and tabular foundation models, and what it means for generalization.
arxiv.org/abs/2610.26794

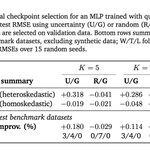
Training neural networks for tabular regression? Our latest work may be of interest
And it's not only about which of the 18! regression objectives is best, but touches on the role of noise and global early stopping in tabular DL in general
arxiv.org/abs/2610.13909
Thread (1/N)

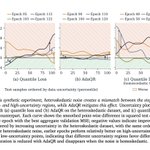
We propose one way to address the stopping-time mismatch at the training objective level we introduce Adaptive Quantile Regression
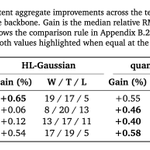
On 28 datasets with 1,000+ training samples, it improves on quantile loss on several backbones, without changing the inference procedure
(7/N)

2
6
216
Find more details in the paper, and try the alternatives to MSE in your next tabular regression problem, we would be glad to know how it works out!
paper: arxiv.org/abs/2610.13909
code: github.com/yandex-research/t…
(8/N=8)
6
191
Our diffusion team is branching into text!
arxiv.org/abs/2610.06648
We propose a simple post-training method for diffusion LMs: swap the usual training objective for kernel-based distribution matching in feature space.
Promising gains from small-scale experiments to 16B models!


Introducing a simple method to post-train both discrete and continuous diffusion LMs.
It's based on Maximum Mean Discrepancy (MMD) that matches token-level feature distributions. Our method improves generation and speed on OWT/GSM8K and scales to 16B models. 🧵

1
10
1,108
If you are more of a visual learner, see the video @iNikitaGushchin and @sudakov_il cooked up below:
xitter.gq/sudakov_il/status/2107…

MMD (Maximum Mean Discrepancy) has shown promise in image generation. Can it improve diffusion language models too?
We post-train DLMs to match generated and reference distributions in a frozen DLM’s feature space. It works for both discrete and continuous models, and scales to 16B! 🚀
The results are strong across text generation, math reasoning, and code! Here’s how it works 👇
1
2
324

go see Roma at COLM and read reasoning shift!

In SF for COLM this week! Our paper Reasoning Shift was accepted as a spotlight at COLM’s Efficient Reasoning Workshop🙊
📚arxiv.org/abs/2604.01161
Super excited to meet Bay Area people, open for coffee and research chats, especially RL, reasoning & AI safety. Hit me up! ☕️🌉


LLMs are general asynchronous agents
We're releasing AsyncLLM - a framework for pretrained LLMs to observe, reason and act concurrently, with no additional training
Paper: huggingface.co/papers/2609.3…
Code: github.com/dvmazur/async_llm
Website with Demos: dvmazur.github.io/async_llm
🧵...

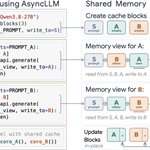
The engine efficiently batches inference across coroutines. Built on Mini-SGLang, supporting MHA, Gated DeltaNet and multimodal MRoPE
github.com/dvmazur/async_llm
(4/5)
