

CS PhD student @berkeley_ai, 4D Vision + Robotics | MSCV @CMU_Robotics | Research Intern @ Frontier AI & Robotics (FAR)
Joined March 2022
- Tweets122
- Following298
- Followers544
- Likes387




Pinned Tweet
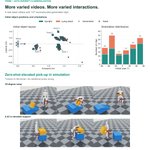
Humans generalize from rich interaction experience. We bring this to humanoid loco-manipulation through scalable real-to-sim-to-real.
Introducing PRISM, we expand 4 real videos into 256 counterfactual variants, recover robot-object trajectories, and train one policy that generalizes across diverse objects, scales, and spatial layouts.
CoRL’26 🚀 Website for details 👉 prism-real2sim2real.github.i…
Work done at Amazon FAR w/ @zhenkirito123 @pabbeel @rocky_duan @JitendraMalikCV @carlo_sferrazza @ckarenliu @GuanyaShi @akanazawa
Zihan Wang retweeted

Collecting data for dexterous hands is hard. Teleop needs a full setup. Bringing UMI-like devices to 20-dof hands is challenging.
Introducing DexPort 🖐️: a hand-held interface w/ a real robot hand. No embodiment gap, recorded joint state AND actions, easy to use.
Zihan Wang retweeted

We trained an imaginative agent! ✨
Agima: an omni agent that plans by imagining futures.
𝗦𝗙𝗧: Directly generalizes to harder tasks! 𝟮%→𝟰𝟬%, beats GPT-5.6 Sol (𝟮𝟬%).
𝗥𝗟: New ways to imagine emerge! Imagines a second plan only if the first one fails (𝟯𝟮%→𝟭𝟬𝟬%).
Zihan Wang retweeted

With @JayHe748646 @KehanWen170077 @leggedrobotics , we push humanoid mobility to next frontier.
Achieved by a generalist contact planner + a generalist tracker + a generalized neural mapping, warmstarted from few human data.
Website: leggedrobotics.github.io/ACP…
Promo Video 👇
Zihan Wang retweeted

What can a robot hand learn from seconds of human motion?
It turns out: dexterous skills that generalize!
Excited to share AdaDex: Learning Adaptable Dexterous Skills via Hybrid Dexterous Mimicking.
From one short hand–object clip per skill, AdaDex learns an adaptable dexterous skill, with skills spanning functional grasping, object reposing, in-hand reorientation, and throw-and-catch.
Project page: yuxuank.com/AdaDex/
🧵👇 (1/8)
Zihan Wang retweeted

We found a way to scale humanoid control that reduces GPU-hours by more than 1000×.
Across 129,514 motions, SuperMimic surpasses the state of the art (128 GPUs, 7 days) with 1 GPU in 3 hours.
Project: supermimic.github.io
Demo: supermimic.github.io/demo/
Zihan Wang retweeted

How can we represent whole-body interaction for humanoid robots—compactly enough for low-frequency planning, yet richly enough to preserve high-frequency feedback control?
Introducing FIBER! 🤖
FIBER learns a unified latent interface between high-level planning and whole-body control, enabling a humanoid to acquire diverse interaction behaviors from heterogeneous experts through a pretrained, frozen Behavior Foundation Model (BFM).
With a single planner and BFM, we demonstrate heavy-door pushing, box carrying, object grasping, controllable navigation, and more!
🌍 Website & Live Demo: fiberaa.github.io
📄 Paper: arxiv.org/abs/2610.24675
A thread on the ideas behind FIBER 🧵👇
Zihan Wang retweeted

Failures are inevitable for robots that are deployed in the *big* world. We introduce ReSYNC, a system that leverages large-scale RL sim2real to recover from local failures and concept discovery to explain/avoid new failures. Check it out here: jaraxxus-me.github.io/ReSYNC…
Zihan Wang retweeted

Can diffusion models generate high-quality images without CFG?
Yes! We introduce ✨Correction Training for Diffusion Models✨, which significantly improves sample quality without relying on classifier-free guidance.
Project page: sunovivid.github.io/correcti…
🧵 (1/n)
Zihan Wang retweeted

Now autoregressive video models can remember. 🧠
Introducing MosaiChunk: persistent visual memory for long-horizon autoregressive video generation🧩.
Instead of remembering everything, it remembers the right things. ✍️
1/6
Zihan Wang retweeted

🤖 For parallel-jaw grippers, high-level plans can already be executed with mature primitives such as grasping. What about dexterous hands?
Introducing GOTT (General Object Trajectory Tracking): object trajectories to dexterous execution with a reusable cross-embodiment contact primitive.
The same primitive supports diverse real-world tasks including sweeping, pouring, whiteboard erasing, and hammering.
With one checkpoint, GOTT reaches 90-96% grasp-and-lift success across multiple objects on three real-world arm-hand platforms.
Check videos 👇
Zihan Wang retweeted

Practice makes perfect. A truly agentic robot shouldn’t just know what to do. It should also figure out how to get better.
What if a robot could watch a demonstration, figure out what it needs to practice, and learn how to get better through practice?
Introducing RPG: Guided Self-Improvement for Embodied Agents, a real-to-sim-to-real pipeline that turns real-world demonstrations into targeted practice.
RPG reconstructs practice tasks from demonstrations, uses demo videos to guide skill improvement, and continually updates a shared skill system from failures.
On real robots, RPG achieves 30/30 successes across 3 tasks. In simulation, it reaches 95.0% success across 22 manipulation tasks after 15 rounds of self-improvement.
Demo → Reconstruct → Guided Practice → Self-Improve → Go Real
Zihan Wang retweeted

Excited to introduce QF3: Fast Flow RL with Filtered Q-Gradients!
Train humanoids from scratch, fine-tune VLAs, even fine-tune image models... all with one simple off-policy update ✨
Zihan Wang retweeted

We’ve all seen the cool “Astra for robotics” demos. But behind the scenes? Slow rollouts, hand-engineered APIs, and/or simulated behaviors that struggle on real robots.
How do we make coding agent actually work in the physical world? 🦾 Introducing SimEX: Simulation-Integrated Robotics AutoResearch 🧵
arxiv.org/abs/2609.38982
Zihan Wang retweeted

How can humanoids keep getting better on their own? Two loops:
🔁 Training: a data flywheel that grows from its own loco-manipulation skills: sirui-xu.github.io/InterMimi…
🧩 Test time: robots that behave better as an LLM agent thinks longer and evolves: sirui-xu.github.io/InterEvol…
🧵
Zihan Wang retweeted
Since Skill from Video (2018) and Videomimic (2025) the unspoken challenge has been finding the right videos to teach robots at scale.
Zihan's work changes that with v2v, turning a few good demos into many counterfactual videos.
Another step towards scalable real2sim2real!

Humans generalize from rich interaction experience. We bring this to humanoid loco-manipulation through scalable real-to-sim-to-real.
Introducing PRISM, we expand 4 real videos into 256 counterfactual variants, recover robot-object trajectories, and train one policy that generalizes across diverse objects, scales, and spatial layouts.
CoRL’26 🚀 Website for details 👉 prism-real2sim2real.github.i…
Work done at Amazon FAR w/ @zhenkirito123 @pabbeel @rocky_duan @JitendraMalikCV @carlo_sferrazza @ckarenliu @GuanyaShi @akanazawa
Zihan Wang retweeted
video to video is a nice idea of data generation, which ensures both grounding and versatility.
Humans generalize from rich interaction experience. We bring this to humanoid loco-manipulation through scalable real-to-sim-to-real.
Introducing PRISM, we expand 4 real videos into 256 counterfactual variants, recover robot-object trajectories, and train one policy that generalizes across diverse objects, scales, and spatial layouts.
CoRL’26 🚀 Website for details 👉 prism-real2sim2real.github.i…
Work done at Amazon FAR w/ @zhenkirito123 @pabbeel @rocky_duan @JitendraMalikCV @carlo_sferrazza @ckarenliu @GuanyaShi @akanazawa
Zihan Wang retweeted
Nice work, Zihan! Still remember the late nights before CoRL, you on PRISM and me on VLK, both doing real-to-sim-to-real. Glad to see PRISM released! 🚀🚀🚀
Humans generalize from rich interaction experience. We bring this to humanoid loco-manipulation through scalable real-to-sim-to-real.
Introducing PRISM, we expand 4 real videos into 256 counterfactual variants, recover robot-object trajectories, and train one policy that generalizes across diverse objects, scales, and spatial layouts.
CoRL’26 🚀 Website for details 👉 prism-real2sim2real.github.i…
Work done at Amazon FAR w/ @zhenkirito123 @pabbeel @rocky_duan @JitendraMalikCV @carlo_sferrazza @ckarenliu @GuanyaShi @akanazawa
(3/4) Generated videos diversify object positions and poses. Generalization goes beyond new objects: trained only on flat terrain, the same policy picks up objects on a 35° ramp and from a 0.43 m elevated support in simulation, without any fine-tuning.

(4/4) We’ll release our code, model checkpoints, and all data. The release is currently under review. Stay tuned!
More demos: prism-real2sim2real.github.i…