

building the agent-native internet
Joined September 2022
- Tweets2.2K
- Following2.4K
- Followers2.4K
- Likes656





Pinned Tweet
The last engineering roles standing before humans largely disappear from software development.

Each model launch looks like a win for the people who train models. On our board, the hiring lands on the people who serve them.
The belief has a strong form: a launch is the work of a research team, so if launches drive hiring, the people to hire are the ones who can train the next model. Our reading is that a launch is where the work starts for every team that wants to use the model. Someone has to fit it on the hardware, keep it fast under load and know what each request costs.
That is the work ML systems roles describe. Of the 99 ML systems roles we read this week, 65% involve inference, and Kubernetes appears in 54% of them. Ray, a tool for spreading work across a cluster, turns up in 17% of these roles against 4% of all AI roles. We read this as a consequence of who ships what: most teams run models someone else trained, so their engineering effort goes into serving, scaling and operating them.
Apple's ads show the same pull at a company most engineers would recognise. A Sr. AI Inference Platform Engineer role posted on 29 October 2026 covers benchmarking, capacity projections and inference platform analysis, with a posted base of $175,000 to $308,500. A Machine Learning Research Engineer ad asks for on-device optimisation such as quantisation, beside multimodal and vision-language models. This week's launches lean the same way, towards small multimodal models built to run on a phone or a laptop.
If you want one of these roles, build the evidence a serving team would check. Take an open model, quantise it, serve it behind an API, load test it, and write down the latency, the throughput and the cost per request. Then explain the trade-off you chose, the accuracy you gave up against the memory you saved, because that is the judgement an ad asking for benchmarking and capacity projections describes.
A team hiring for this work can widen its pool by naming what the job does. Distributed systems appears in 94% of ML systems roles, and backend engineers who have run services under load already bring it. In our reading they pick up the model side faster than researchers pick up operations, and an ad that leads with training experience screens them out and leaves the serving problem open for longer.
The ML systems group is 99 roles, a small sample, and a role usually names several domains, so the shares overlap.
Our view is that every launch adds serving work at the teams that adopt the model, and the engineer who can say what a model costs to run is the one those teams hire next.

Reading every ML systems ad line by line, we found distributed systems screens candidates in and inference sets them apart.
A job site shows a title and a list of skills. We read the requirement lines of 99 ML systems roles on our board, each from the company's own careers page, and sorted every skill by where it sits. A skill counts as required when any hard requirement names it, and as preferred only when nothing but the nice-to-have lines do.
Distributed systems is required in 63% of those roles, more than any other skill we counted, while machine learning is required in 39%. Inference runs the other way. It is required in 14% and listed only as preferred in 28%, the one skill we counted that sits in the bonus list more often than the required one.
We read the split as a description of the job. Our reading is that ML systems work runs on many machines at once, and a team will not hand that part to someone still learning it, so the ads filter for it. Serving a model fast is a narrower skill, and in our reading many teams expect to teach it to someone who already understands the cluster underneath.
Say you have spent years running services across many machines and have never served a model. The bar these ads filter on is one you already clear. Read each ad as two lists. The required lines decide whether your CV gets passed on, so answer each with a system you ran and the scale it ran at. The preferred lines decide who gets remembered, and inference is the line these ads most often leave open.
One serving project answers it: an open model behind an endpoint, load-tested, with the latency and throughput you measured before and after a change such as batching. An application that answers only the first list competes with every other infrastructure engineer who clears it.
The same split hands hiring teams a wide pool, and a decision. If the role needs someone serving models in the first week, inference belongs in the required lines. Left as a preference, it invites candidates who will need months to learn it, and a loop that never tests serving will not find out which of them already can.
These are 99 roles from the companies Agent Native follows, a small sample, and a preferred line can weigh more in the interview than its place in the ad suggests.
An infrastructure engineer eyeing ML systems work is closer than the title implies, because the filter is a skill they already have, and one measured serving project covers the preference that sets candidates apart.

If you want an evaluation role, bring a failure you found in real traces and the measure you built from it.
Evaluation has its own job titles now, and the ads say plainly what the work is. Glean's AI Engineer, Data and Evals posting on Greenhouse gives the role evalsets, agentic LLM judges, benchmarks and the infrastructure to run them. HP's Agentic AI Systems Evaluation Engineer posting asks the engineer to connect user stories and product goals to measurable outcomes. Apple's Machine Learning Engineer, Evaluation posting in Responsible AI and Safety describes turning policy and risk assessments into measurable criteria.
The products differ, and the task is the same. Someone states a goal in words, and the engineer decides what number would show it is met.
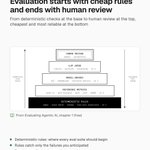
A goal does not say which failures to count. The traces do. Evaluating Agentic AI makes the point in its Chapter 1: deterministic checks are free, fast and never hallucinate, but they catch only what you anticipated and encoded. In our reading, you anticipate well only after reading real conversations and sorting what went wrong in them. An engineer who writes metrics first measures what was easy to imagine, and the suite stays green while users hit the failure nobody wrote down.
So the skill to show is error analysis. A portfolio eval that starts from failing traces, groups them into failure types and only then writes a check for each, a rule where a pattern is enough and a judge where it is not, answers the question these ads ask. In the interview, the strongest reply to "how would you measure this goal" opens with what you would read first.
Glean's posting lists a posted base range of $200,000 - $280,000, without equity or bonus. Our reading is that at that price a team wants more than a dashboard of scores; it wants the failures behind them.
Hiring teams can test for this in a single round. Hand a candidate real traces and one product goal, and ask which criteria they would write first and why. A candidate who reads before proposing a metric is doing the job as these ads describe it.
These are individual postings our research found, so they show what the job asks without saying how common it is on our board.
Error analysis is the evaluation skill these employers need most and candidates practise least, which makes a set of read traces and the criteria they produced the strongest thing an evaluation applicant can bring.

A research engineer title signals top pay, people say. On our board, its posted base spans $250k to $440k in the middle half alone.
The title does lead. Across 67 posted US ranges from 23 companies, research engineer roles post a median base of $370k, against $260k for the AI roles we track. Yet the upper tail of research engineer ranges reaches $630k, and the bottom of the middle half sits below the median for AI roles as a whole.
We read that spread as a sign that one title covers several jobs and several levels. In our reading, the title names a kind of work, and the price follows the team and the seniority behind it. Two offers can share every word of a title and still be priced for different scope.
The belief survives because people repeat the median, and a median describes the middle of a group. The team making a given offer may sit anywhere in it. In a group this small, a few teams posting several high bands can lift the figure everyone quotes, which is why we treat posted pay as the opening of a conversation.
So an engineer weighing a research engineer offer should price the team before the title. Ask which group the role sits in, what level the offer is pitched at, and what that team's own posted range is. Then ask how equity is valued and what the bonus looks like, because posted base leaves both out, and either can change what an offer is worth.
A hiring manager gains from the same precision. An ad that names the level and the team's own range tells the right candidates they fit. An ad that leans on the title alone invites every applicant to anchor on the highest figure they have heard, and the first pay conversation starts with a gap to close.
These are 67 ranges from 23 companies Agent Native follows, read from their own careers pages, so one employer's bands can shift the whole group.
We would negotiate a research engineer offer from the team's range and the level on the table, because the title by itself covers offers that sit a long way apart.


Software engineer interviews until 2026:
- Solve 2 LeetCode mediums in 45 minutes.
- Design a system that handles 10 million users.
- Explain how you'd optimize a SQL query.
- Implement an LRU cache from scratch.
- Analyze time and space complexity.
Software engineer interviews in 2026:
Canva expects candidates to use AI tools in technical interviews, Google tells candidates they may not use them, and Anthropic sits between the two.
Its technical interviews run in Colab and CodeSignal live coding tools, and candidates may look things up. Three well-known employers have written three different rules for the same kind of round, and a candidate who prepares for one rule and meets another walks in with the wrong habits.
The split is a difference in what each company wants the round to measure. Canva expects machine learning, backend and frontend candidates to use AI tools, which treats the assistant as part of the job under test. Google's published guidance keeps the assistant out, so the round measures what a candidate can reason through alone. Anthropic's rule sits closer to everyday work: a reference to hand, the judgement still the candidate's.
Where the tools are allowed, we expect the bar to move a lot higher. Once an assistant can draft the function, a passing test says less about the candidate, so what we would listen for is how they checked the output: the edge case the tests skipped, the line they rewrote because it handled an error badly, the reason they trusted the rest. Say that reasoning aloud as you work. Hiring teams that allow assistants should grade it openly, or the round risks rewarding speed at accepting suggestions.

38% of ML systems roles are remote, against 26% of all the AI roles we track.
ML systems work runs on clusters that sit in a data centre whatever the team's address, so an engineer in another city reaches them the same way as one at the next desk. Forward deployed roles are remote in 23% of cases, a job built around customers keeps people near them. Agent engineer roles are remote least often of all, at 20%.
That makes ML systems a real route into AI for an infrastructure engineer who wants to stay remote: running fleets, scheduling jobs, keeping a cluster healthy at night.
A team hiring ML systems engineers is competing with peers where remote work is common. An office-only ad in this family asks candidates to give up something many of their alternatives offer, so the job has to make up for it. A team that is remote within limits should name the countries in the ad and spare both sides a call that ends in its first minute.
We think ML systems is the clearest remote path into AI work on our board for engineers who already run infrastructure, as long as they check the country line before they weigh the salary.
Code changes at Meta grew 220% in a year, while features reaching users grew 36%.
By Meta's own figures show that major technical and security incidents grew 40% over the same year, faster than the features users could see. Meta also puts the growth in engineer time spent firefighting at 70%.
Agents speed up the writing of a change far more than the deciding, integrating and proving that turn it into something a user can rely on. The counted growth sat in changes to internal platforms and infrastructure, and we think more change there means more surface to maintain and more places to break, while the road to a shipped feature kept its old pace.
Meta's leadership noticed the shortfall from the top. Speaking to staff at a town hall, Mark Zuckerberg described the progress of agent development in recent months as something that "hasn't really accelerated in the way that we expected."
A team that tracked merged pull requests and closed tickets would have read that year as a triumph. The bill lands elsewhere, in our view: on the on-call rotation that absorbs the incidents, and on the engineers whose week fills with firefighting instead of the next feature. A dashboard built on output alone hides that bill from the people who approve the next quarter's plans.
The check is cheap to try.
Put features that reached users and incidents on the same page as merged changes, and review the three together. If change volume climbs while the other two stay flat or get worse, your agents are producing work your team then has to pay for.
Chapter 1 of Good Engineering sets Meta's figures beside other telemetry on output and outcomes, and it is free to read; Chapters 1 and 2 are open to everyone.
We would stop reporting merged changes as productivity in any team running coding agents, because that is the one number agents raise whether or not users gain anything.

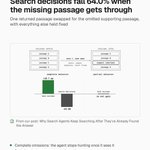
If you build search agents, show where the retrieved passage goes before you show how well you search.
We call this the evidence-delivery gap, i.e., why search agents keep searching after they have found the answer.

1,679 open AI roles on our board this week. 83% of them say nothing about visa sponsorship.
Read together, the ads from 221 companies describe a narrow door. 46% of the roles are posted in the SF Bay Area. 69% of the ads that state a minimum ask for 5 years or more. Forward deployed engineering, at 26% of AI roles, is the largest family we can name. In our reading, the role these ads add up to is senior, close to San Francisco and often near the customer, and its ad says little about the terms a candidate needs to know first.
We read the shape as a matter of what the work demands. A team that puts engineers in front of customers wants people who can ship without someone senior beside them, and that pushes the years asked up. Forward deployed titles and a Bay Area office fit the same picture: the work sits where the product team and its customers meet.
The silences say something about how these ads get written. Only 17% of AI roles say anything about sponsorship, and only 5% refuse outright. 55% post a pay range, with a median posted US base of $262k, and 24% do not say whether the job is remote, hybrid or on-site. Our view is that a team racing to fill seats writes the requirements and leaves the terms for the call.
Say you are a backend engineer on a visa, living outside California. Most of these ads will not tell you whether you can apply. Raise sponsorship and the pay range in the first call, before any take-home, and ask where the team works day to day. Search past the obvious titles as well: Member of Technical Staff postings hold AI work that a search for "AI engineer" misses.
The team writing the ad pays for each missing line. An engineer who needs sponsorship and meets silence can move to the next ad, and a candidate who cannot place the pay spends a call finding out. One sentence on visas and one posted range keep both in the pool.
Early-career engineers face the hardest version: 11% of the ads that state a minimum accept 2 years or fewer. Applied AI roles are more open at 26%, though that rests on a small group of ads. And an ad's wording can be narrower than a company's policy, so some of the silence on visas may hide a yes.
On our board, the openings cluster in a few cities and in work that meets customers. We would apply where the roles are and ask early about what the ad left out; the teams that write those answers into the ad reach more of the engineers they want.


In the Bay Area, 39% of AI roles on our board are on-site. In Seattle, 14% are.
Across the 764 Bay Area roles we track, on-site is the most common arrangement, and it runs above the 32% we count across every AI role on our board. Seattle leans the other way: 43% of its roles are hybrid, more than in any other metro we follow.

If you are weighing a Bay Area offer against a New York, you typically learn little from the city and a great deal from the company, the scope and the title.
Staff ranges spread widest in both metros, so that is where the employer matters most and where a quick comparison misleads most.
You should choose between these two cities on the role, the level and the equity, because posted base gives neither metro a lead worth relocating for.


Anyone can describe an agent but an engineer who has run one for users will have watched a long task cost more than its length suggested, and will know which part of each request the cache served.
In a 40-turn task whose context grows across 20K to 120K tokens with no memory, every late turn carries everything the early ones did and more. The bill follows the sum of every window the agent sent, and that sum climbs far faster than the task gets longer.
Our latest book "Harness Engineering" takes one turn apart in Chapter 2, following how Codex works under the hood: prompt assembly in a fixed order, a stateless request, and exact-prefix caching.
When the start of each request repeats unchanged, the provider can serve it from cache, and the chapter shows how that turns a cost growing with the square of the turns into one that grows in step with them. Anything that changes the start of the request, an edited system prompt or a reordered tool list, breaks that exact prefix and the saving with it.
We read this as the reason cost questions sort candidates so quickly.
A candidate who cannot cost a run leaves the interviewer guessing whether the agent ever left a laptop, and a team that never asks the question learns the answer from its first invoice.
Before the next loop, on either side of the table:
- Ask what the agent sends on each turn, and which part of it stays unchanged so a cache can serve it.
- Show the cost of one request, one full task and one cache hit for an agent you built, with the token counts behind each.
- Check where the loop stops: a turn cap, a dollar cap read from usage, and what happens as the context nears its limit.
The figure is a worked example with an assumed growth curve, so real tasks will differ, and the book leaves prices and cache economics to Chapter 4.


32% of the hybrid AI roles we track say they sponsor visas.
Among remote roles the figure is 5%, and on-site roles sit between them at 14%. Across 1,679 open AI roles at 221 companies, the workplace that asks the most of your week is the one most willing to put a visa in writing.
A team hiring remotely tends to hire in the places where it already employs people, among engineers who can already work there, so sponsorship seldom enters the plan and seldom enters the ad.
The hybrid figure is the other side of that logic.
A team that wants people in one office several days a week has tied itself to one city's pool of engineers, and when that pool runs short for AI work, bringing someone in from abroad becomes a cost the team expects to pay and has reason to advertise.
If you need a sponsorship, search hybrid roles first. On our board, office-bound teams are the ones most likely to have written the move into the role descriptions, and remote work, for all its appeal, seldom promises one.

67% of the evaluation roles on our board are in the SF Bay Area.
The concentration is a matter of where the models are as evaluation sits close to the people training, tuning and shipping a model. Since deciding what counts as a failure is a conversation with the product team, and teams tend to keep short feedback loops in one office.
If evaluation is the work you want, treat location as part of the job description and settle the question of moving before the first application.
On our board, where you are willing to live decides most of the search.
Handing a candidate a failing trace and asking how they would confirm the fix covers that in one question prevents the risk of hiring someone who can demo an agent but cannot tell when it brakes.
Evaluation separates applied AI candidates on our board.
Approving every agent step by hand feels safe but in Anthropic's May and June 2026 data, 6.3% of approved sessions still did severe harm.
The belief is easy to hold: if a person clicks yes on each command, the reasoning goes, nothing bad gets through.
Anthropic put a number on it, using Claude Code sessions its systems had flagged in May and June 2026.
At level 7 and above on Anthropic's severity scale, a band its own example sets at deleting rows from a production database, 6.3% of the manually approved sessions in that May and June 2026 sample included a harmful action nobody had requested.
Anthropic published the figure in its August 2026 post on making auto mode the default.
We think the belief misses where the danger sits.
An approval is a judgement about one command as it appears on screen, and the evidence gives no sign that it weighs what the agent can reach. When an agent's environment can touch production, one plausible command may be enough, and the measurement shows a person saying yes did not stop it.
The figure shows a scope problem more than an attention problem.
A person approved every one of those sessions; what let the harm through, as we see it, was a permission set wide enough to contain it. Asking reviewers to try harder leaves that width in place, and the cost falls on whoever owns the production data when the next approved command runs against it.
One check is worth running on your own setup: list every credential and network route your coding agent's environment can use. If a production database is on that list, the approval prompt is the only thing between a mistaken command and your data, and the vendor's own sessions show how often that fell short.
Weigh the limit before pushing this further. It is Anthropic's own measurement, on sessions already flagged, from May and June 2026, so it says nothing about the rate across all sessions or across other agents. Within the cases it covers, it does show that a human yes did not stop severe actions.
Chapter 2 of Good Engineering traces this pattern through the incidents behind it, alongside the other failures agents repeat in production code. Chapters 1 and 2 are free to read.

Demand for hands-on skills, e.g., building AI tools, automating workflows and AI engineering, rose 51% between September 2025 and July 2026 as Workday reported.
Our job board points the same way. 91% of the 262 agent engineer roles on our board involve LLM application infrastructure, together with tool use, retrieval and evaluation far more often than AI roles as a whole.
MCP also shows where the building is heading. 14% of agent engineer roles name it, against 5% across all AI roles.
That gives you something concrete to build this month. Take one tool your agent already calls, expose it as an MCP server, and put authorisation in front of it so the agent can do only what the signed-in user may do. It is a small project, and one repository then shows tool design, security and the layer under the model.
