

The best AI is built, not bought. Our platform, Applied Compute Agent Cloud, is now in private beta. Book a demo below.
San Francisco
Joined July 2012
- Tweets295
- Following24
- Followers8.4K
- Likes721





Pinned Tweet
Introducing Shift-1, a frontier coding router trained on AC2 that reduced coding agent cost by up to 55% with no noticeable drop in quality. Try it at shift.ac.
Read more on how to train and deploy your own custom router.
appliedcompute.com/platform/…

Applied Compute retweeted

The top 100 companies Lenny Rachitsky would most want to join: companies with the highest talent density, tackling the most ambitious problems, where you'll learn the most, and see the biggest upside.
- Abridge
- AfterQuery
- Airbnb
- Airwallex
- Anduril
- Anthropic
- Applied Compute
- Applied Intuition
- Base Power
- Baseten
- Basis
- Bedrock Robotics
- Black Forest Labs
- Chai Discovery
- Chainguard
- Clay
- ClickHouse
- Cloudflare
- Cognition
- CoreWeave
- Crusoe
- Cyera
- Databricks
- Decagon
- Deel
- ElevenLabs
- Etched
- Exa
- Factory
- fal
- Figma
- Figure AI
- Fireworks AI
- Gamma
- Genspark
- Gimlet Labs
- Glean
- Granola
- Hadrian
- Handshake
- Harvey
- Helsing
- Hex
- Kalshi
- Lambda
- Legora
- Linear
- Liquid AI
- Lovable
- Mercor
- Mercury
- Mistral AI
- Modal
- n8n
- Notion
- NVIDIA
- OpenAI
- OpenEvidence
- Palantir
- Parallel Web Systems
- Periodic Labs
- Physical Intelligence
- Pierre Computer
- Polymarket
- PostHog
- Prime Intellect
- Profound
- Railway
- Ramp
- Reflection AI
- Replit
- Revolut
- Ricursive Intelligence
- Rippling
- Runway
- Safe Superintelligence
- Saronic
- Shield AI
- Shopify
- Sierra
- Skild AI
- SpaceX
- Stripe
- Sunday Robotics
- Suno
- Supabase
- Surge AI
- Temporal
- Tesla
- Thinking Machines
- Together AI
- Turbopuffer
- Valon
- Vanta
- Vercel
- Waymo
- Whatnot
- Wispr Flow
- Wonderful
- WorkOS
cosign.co/lists/lennysan/100

Reflection AI’s Beam 1.0 is out today, a 501B MoE with 23B active under Apache 2.0. We ran a brief RL post-training run on it in AC2 that tripled its score on a challenging long-horizon agentic coding task in 40 steps, 0.07 to 0.215.
We’re offering day 0 support in AC2 for inference and post-training.


Beam is now available across platforms, with open weights under the Apache 2.0 license - in collaboration with an ecosystem of 40+ partners.
We're releasing:
- Weights, tokenizer, and reference implementation
- BF16, FP8 and NVFP4 weights and a DFlash2 drafter
- The open source harness we built and trained Beam on: Mirror CLI
Weights and model card on Hugging Face: huggingface.co/reflection

We were especially impressed with Beam’s inference efficiency during post-training. The architecture supports 1M context and stores minimal KV cache state per token, enabling training on long horizon tasks at high concurrency.
Thanks to @reflection_ai for the early access and for contributing a key open model to the Western ecosystem!
Applied Compute retweeted

Beam is now available across platforms, with open weights under the Apache 2.0 license - in collaboration with an ecosystem of 40+ partners.
We're releasing:
- Weights, tokenizer, and reference implementation
- BF16, FP8 and NVFP4 weights and a DFlash2 drafter
- The open source harness we built and trained Beam on: Mirror CLI
Weights and model card on Hugging Face: huggingface.co/reflection
Nemotron 3.5 Super VL by @NVIDIAAI is now supported for both training and inference on AC2.
In early post-training runs for our customer, we've been impressed with the quality of the base model for its inference efficiency.

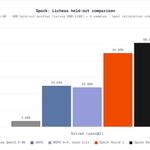
Introducing Spork, an efficient post-training recipe which increases our solve-rate on chess puzzles by 100% when compared to our best GRPO setup.
It uses a GRPO warmup, splits task-specific datasets further into partitions, trains specialists, and then uses multi-teacher on-policy distillation. Like a Spork, it leverages gains by simply consolidating specialists.

We find that most of the gains over GRPO (91% of the total jump) can be achieved with only 2 partitions and thus 2 specialists. In an additional experiment, we find that more divergent partitioning improves final performance over random partitions.

Like chess puzzles, many of the enterprise tasks that we train on at Applied Compute have low pass rates on existing frontier models. Spork serves as a new post-training paradigm to overcome these challenges. Read the full report.
appliedcompute.com/research/…

AC2 now supports decision model training. Teams can build custom Jev-like models for use cases like request routing, content classification, and anomaly detection.
Reach out to get started with your own classification task!

You can now train your own decision model in our platform AC2! Jev-like models, custom fit for your use case :)
We implement decision models through a language-model backbone with a small learned output layer called a decision head. The backbone processes the input, question, and answer choices, and the head produces scores which are softmaxed to produce a probability distribution over answer choices.
Our software interface makes it easy to add a variable-sized decision head to frontier open-weight models. Choose any open source model, and train it as a decision model using Brier loss or cross-entropy loss. Training updates both the decision head and the language backbone.
We tried it on 50k sampled training datapoints from the Civil Comments dataset, starting from Perplexity’s pplx-decider-v1-27b, and F1 for detecting toxic comments increased from 0.482 to 0.677 on 20k sampled eval datapoints. The training job took less than an hour on four B300 GPUs.
Reach out to get started with your own classification task: docs.appliedcompute.com/plat…

Applied Compute retweeted

Super excited to share this work we've been doing at AC (major kudos to @AtharvNaphade)!
It allows us to take a legitimate step towards taking our hands of the wheels during model training. Looking forward to sharing more about how we were able to use it for automating a full end to end training loop 👀

We're sharing a key step towards enabling Continual Learning at Applied Compute.
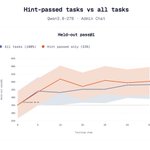
In On-Policy Self-Distillation, the teacher model supervises training with privileged information: a hint. The training signal depends heavily on hint quality, but manually refining hints across runs is impractical, and isolating their individual impact is difficult. We instead optimize hints automatically using efficient proxies for their eventual training value.
Hints go stale as the student learns. Refreshing them on still-failing tasks reaches 83% held-out. We found that training only on hints that pass validation beats keeping every training task, even if that means using 50% less data on more out-of-distribution tasks.

We share these results as a key step in resolving the bottleneck between identifying failures in production and actually providing correct, dense, and on-policy training signal for continual learning at scale. Read the full report. appliedcompute.com/research/…
