

Harness Engineer // building agentic infra and chasing the singularity // 1x Acquired • CTO @QORIS_AI 📩 DMs open for advisory · Europe CET · remote
talk harness with me →
Joined December 2024
- Tweets1.8K
- Following578
- Followers1.5K
- Likes31.4K


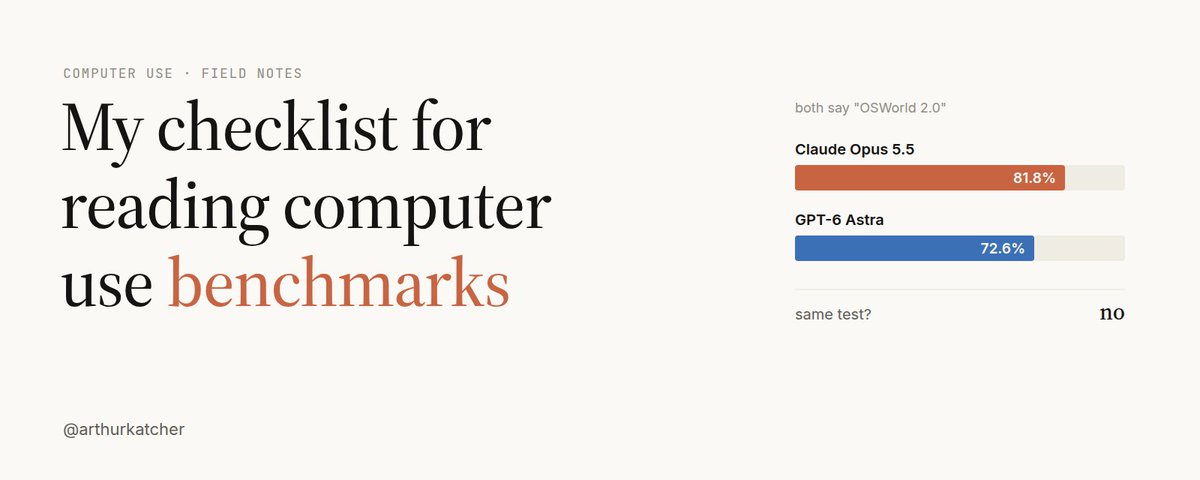
Sorry for the hot 2026 take...
but I'M IN LOVE WITH THE TERMINAL
And I'm so tired of people saying terminal is dead.
First of all, it's a free world, and everyone can choose their own IDE, even if it's a damn terminal.
Second, people don't make that choice for no reason. So let me spill out at least my reasons why I think TERMINAL IS KING:
1. It's a ubiquitous interface. You can run dozens of TUI harnesses, and your eye will still get a comparable one-dimensional interface between them all.
2. UI/UX is a taste question. Developers are pretty picky with their taste. I spend 90% of my day in that one interface, and I don't want to feel like a vision of one person should define the design of the tool I live in.
So in that very sense terminals are freedom, UI/UXs are a box made by others for you. I'd rather build be in my own box.
3. They're all damn laggy and buggy. There is not a single UI/UX for agent management in 2026 that nails it all across every possible harness.
So yes, I'm a terminal guy, and I'm not afraid to say it.

What new harnesses people are using now?
Besides Pi / Opencode / Claude code / codex and all that regular stuff.
Something interesting out there?
I’m dropping all the unit test from our CI.
The ratio of the value they bring to tokens (& GitHub actions) you pay for their development and maintenance rushes to 0, if it’s not already there.
It’s only e2e tests & evals for me now
Claude Code changes the level of thinking to xhigh each time after automatic compaction on idle state.
The compaction is good, but pls stop changing the thinking effort with it
My minimal Pi setup for using Sol 6.1 instead of Codex:
- pi
- web_search (exa + duckduckgo as a fallback)
- web_fetch (direct Node request with .md conversion)
- subagents (tintiweb/pi-subagents plugin)
- system prompt adapter
I find this combination outperforming regular Codex CLI setup.
Gave Grok 4.7 control over my browser.
It encountered recaptcha "I am not a robot" box.
With no thoughts it clicked in the box and got through successfully.
Gave the same task to Opus 5.5 -> it stopped on the captcha and asked me to solve it.
Grok vs Claude, 1:0
When working with long-running /goal sessions on my personal laptop, I find it practical to give the model a way to track the CPU load and the temperature with a running background monitor.
I've personally had a couple of times when my 16 GB RAM and 8 CPU laptop was running like 95 degrees hot because of the 3-5 simultaneous /workflows and a bunch of subagents completely annihilating my processor.
So that has led me to write a skill /track-load, which basically just launches a monitor that ticks your model with the current load data every X minutes in long-running flows, so the model can dynamically adapt.
It's meant to be used together with the type of session that acts as an orchestrator for a swarm of 10-20-100 parallel subagents and works for days, especially when you're running on resource-tight VMs/personal machines.
The skill for the monitor is in the comments, feel free to grab it.

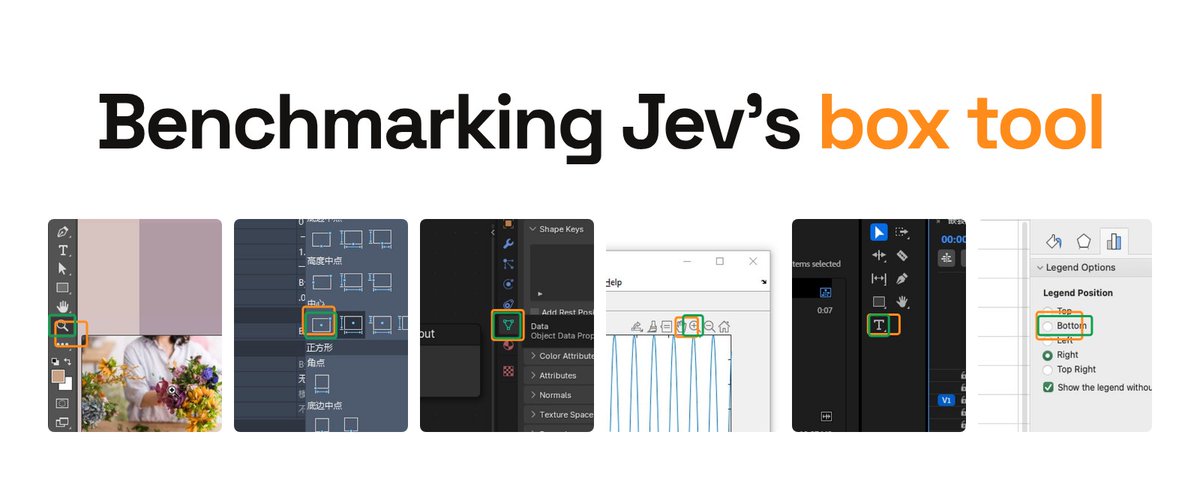
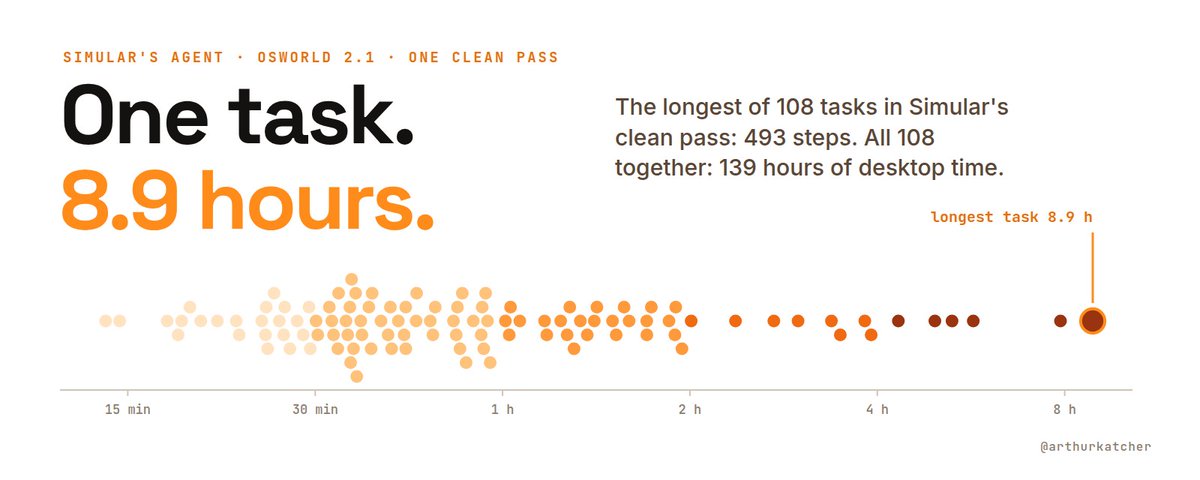
Thanks to @SimularAI for publishing every run of their Sai agent on OSWorld 2.1. The task times in this article come from their data. Honestly, more teams should share raw runs like this.

>> Claude: pauses their startup program.
>> People get rejected after being initially accepted.
>> OpenAI in the meanwhile: gives us $2.5k credits.
DM me for the steps.

Haiku 5.5 scores 72.4% on OSWorld 2.1 - offline subset.
I’ve discussed exactly what that means and how to read it in my yesterday’s article on computer use benchmarks:

Wrote an article on computer use benchmarks yesterday. Two habits from it.
First, check the test version before comparing benchmark scores.
Opus 5.5 gets 81.8% on OSWorld 2.1, GPT-6 Astra 72.6% on 2.0. Looks like a 9 point win. But the same model, Opus 5, scores 68.3% on 2.0 and 77.7% on 2.1. The version alone moves it 9 points.
Second, check if it's the average run or the best one.
Anthropic's 81.8% is the average of 5 runs. Gemini 4 Argon's 69.2% is the best of 3. Run a model 3 times and keep the top score, and you report a number it won't hit on a normal try.
Same thing this week with Grok 4.7 on VulcanBench. Grok 4.7 was run on it more than once, and each run got its own spot on the leaderboard. The top three spots are all Grok 4.7, and the 93.15 everyone shares is the best of them.
Labs should report the same version and the average run. Until they do, read the fine print.
