
Foundation Model @Tesla Optimus, prev PhD UW
Joined May 2022
- Tweets31
- Following338
- Followers372
- Likes473


Pinned Tweet
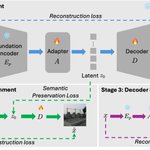
We found that visual foundation encoder can be aligned to serve as tokenizers for latent diffusion models in image generation!
Our new paper introduces a new tokenizer training paradigm that produces a semantically rich latent space, improving diffusion model performance🚀🚀.

Bowei Chen retweeted

Late to the party, but happy to introduce our #ECCV2026 paper: On the Diffusibility of High-Dimensional Latents.
We found that finetuning representation autoencoders (RAEs) for reconstruction can hurt diffusibility under standard velocity prediction in flow matching. Why?(1/10)

Congratulations!

We’re excited to share that @nuance_ai has raised a $50M Series A led by @lightspeedvp, joined by @Accel, @spc, @nvidia, and @definevc!
Much of human communication happens beyond words. Before we can speak, we learn to read faces, return smiles, follow gestures, and sense when someone is listening. That visual and emotional vocabulary stays with us for life.
At Nuance Labs, we’re building a foundation model that understands and responds to the full spectrum of human emotion. A single full-duplex audio-visual model that sees, listens, and responds in real time, with the natural give-and-take of a conversation with a friend or colleague.
We believe the best interface with a machine is the one we’ve practiced since birth.
Join us!
Bowei Chen retweeted

New paper: AsymFlow🔥
JiT x0-prediction is not enough for pixel generation. Better keep velocity in a low-rank subspace:
- 1.57 FID on ImageNet (best pixel flow model)
- Finetunes FLUX.2 klein into pixel space, beats the original on HPSv3/DPG/GenEval (#1 overall on HPSv3)
1/7

Nice blog, highly recommend!

Too many REPA / RAE / representation alignment papers lately?
I was lost too, so I wrote a blog post that organizes the space into phases and zooms in on what actually matters for general/molecular ML.
Curious what folks think - link below!
🔗 Blog: kdidi.netlify.app/blog/ml/20…

Bowei Chen retweeted

Excited to present UltraZoom at SIGGRAPH Asia next Tuesday (Dec.16)!
UltraZoom converts sparse phone captures of an object into a single gigapixel-resolution image that you can seamlessly explore. Threads below.
Website: ultra-zoom.github.io
Paper: arxiv.org/abs/2506.13756
Bowei Chen retweeted
Excited to announce a new track of accelerating Generative AI:
pi-Flow: Policy-Based Few-Step Generation via Imitation Distillation
github.com/Lakonik/piFlow
Distill 20B flow models now using just an L2 loss via imitation learning for SOTA diversity and teacher-aligned quality.

The Representation Autoencoders (RAE) by @sainingxie's team is fascinating — a brilliant demonstration that high-dimensional diffusion is indeed feasible.
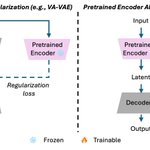
In our latest work on semantic encoders, we align a pretrained foundation encoder (e.g., DINOv2) as a visual tokenizer, achieving better reconstruction quality while preserving semantic consistency. Instead of freezing the encoder, we introduce a semantics-preserving fine-tuning strategy that significantly improves reconstruction quality.
I can see great potential in combining RAE with our approach to build semantically rich tokenizers with large channel dimension and strong reconstruction fidelity.

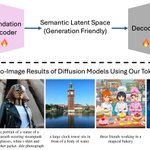
On LAION 2B dataset, we train a text-to-image diffusion model on our tokenizer, which converges faster and surpasses the FLUX-VAE baseline.
Check out more details and results in our paper!
[8/N]

We hope our findings inspire a rethinking of tokenizer design in generative modeling.
🙏 Huge shoutout to my amazing co-authors and collaborators @KaiZhang9546,@Sai__Bi,@HaoTan5,@zhanghesprinter ,@tianyuanzhang99 ,@zhengqi_li, @bitxiong,@jianming_zhang_.
[9/N]
We will be presenting Total Selfie at Arch 4A-E #185 this afternoon. Come and talk with us!
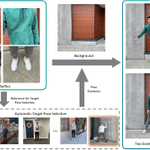
#CVPR2024 Arm-captured selfies only capture your partial body. Instead, what if you could capture a full-body photo that someone else would take of you in the scene?
We present Total Selfie, which generates full-body selfies from photographs originally taken at arms length. 1/n

#CVPR2024 Arm-captured selfies only capture your partial body. Instead, what if you could capture a full-body photo that someone else would take of you in the scene?
We present Total Selfie, which generates full-body selfies from photographs originally taken at arms length. 1/n
Because self-captured photos are typically taken close up, they have limited field of view and exaggerated perspective that distorts facial shapes. We instead seek to generate the photo some one else would take of you from a few feet away. 3/n