
MTS @MicrosoftAI / PhD @ChicagoHAI @UChicagoCS, human-centered ML.
Mountain View, CA
Joined October 2016
- Tweets74
- Following1.7K
- Followers870
- Likes565



Pinned Tweet
✨ New paper at #FAccT2023 next week ✨
Machine Explanations and Human Understanding
arxiv.org/abs/2202.04092
Explanations are hypothesized to improve human understanding of machine learning models. However, empirical studies have found mixed and even negative results.
Chacha Chen retweeted

🚀 Recruiting Student Researchers (SRs) interested in Multilingual RL!
Current student working on RL, LLM post-training, or multilingual LLMs? We'd love to hear from you!
Apply: google.com/about/careers/app…
CV + interests: docs.google.com/forms/d/e/1F…
Reposts appreciated!
Chacha Chen retweeted

Brilliant idea! Next up: Apple randomly reboots your Mac if you're building competing tech, Gmail silently edits your email if you mention rival platforms, and Tesla Autopilot swerves if it detects you're working on self-driving cars.
All in the name of safety, of course. Because malicious actors controlling the world’s operating systems, inboxes and cars would be extremely dangerous!


Chacha Chen retweeted

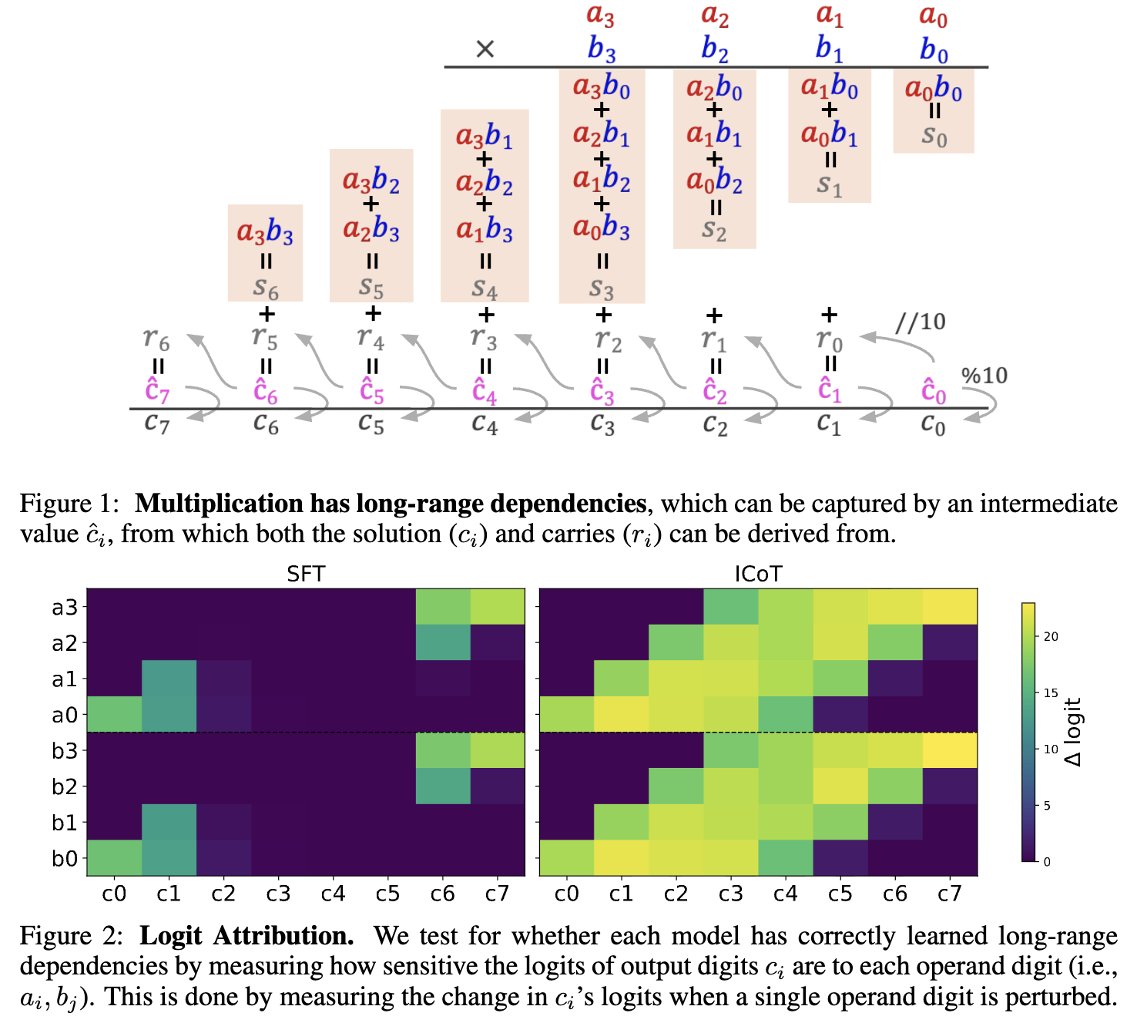
🚨Why can’t Transformers learn multiplication?🧮
Even with billions of params, models struggle with multi-digit multiplication.
In our new work, we reverse-engineer two models: a standard fine-tuned (SFT), and an implicit chain-of-thought (ICoT) model to see why. Read on!
1/n 🧵

Chacha Chen retweeted

1/n You may know that large language models (LLMs) can be biased in their decision-making, but ever wondered how those biases are encoded internally and whether we can surgically remove them?
Chacha Chen retweeted
🚨 New paper alert 🚨
Ever asked an LLM-as-Marilyn Monroe who the US president was in 2000? 🤔 Should the LLM answer at all? We call these clashes Concept Incongruence. Read on! ⬇️
1/n 🧵


Chacha Chen retweeted

CaseSumm is publicly available on HuggingFace! We hope this dataset enables:
- Better evaluation of long-context summarization
- Research on legal language understanding
- Development of more accurate & reliable legal AI tools
Dataset: huggingface.co/datasets/Chic…
I'll be presenting this work at 2pm and will be around until Sunday. Please reach out if you're interested in this line of work - would love to connect in person or virtually!

Chacha Chen retweeted

🚀🚀🚀Excited to share our latest work: HypoBench, a systematic benchmark for evaluating LLM-based hypothesis generation methods!

Chacha Chen retweeted

Even ChatGPT knows. It is very hard to think of a positive spin for Rosalind here. A shocking display of ignorance and arrogance.


Mitigating racial bias from LLMs is a lot easier than removing it from humans!
Can’t believe this happened at the best AI conference @NeurIPSConf
We have ethical reviews for authors, but missed it for invited speakers? 😡

1/ ✨ Can Multimodal LLMs generate radiology reports from chest X-ray images? In our recent evaluation paper, we show: not yet.


We’re excited to present this work at @SymposiumML4H next month in Vancouver. Happy to chat and feel free to reach out 😊.
160
4/ Our Evaluation Overview:
We started with direct report generation using different prompting strategies, but found the model failed terribly. To understand the low performance, we decomposed the task into two steps: image reasoning and report synthesis.
1
228
5/ We also conducted a human reader study to compare the quality and readability of AI-generated and human written reports.
Paper: arxiv.org/abs/2407.12176
Code:github.com/ChicagoHAI/cxr-ev…
Altogether, our findings cast doubt on the viability of using GPT-4V in a radiology workflow.
181
I will be in Rio for #FAccT2024 next week. Hit me up if you will also be there in person and would like to chat!🏖️🍻😎