

Democratizing Generative AI
India
Joined July 2023
- Tweets27
- Following4
- Followers1.3K
- Likes28




CognitiveLab retweeted

Can't believe i am doing this
Just Open Sourced the Largest Synthetic Parallel Multilingual OCR dataset
> 1M+ Document Images
> 22 Languages (Arabic, Bengali, German, English, Spanish, French, Gujarati, Hindi, Italian, Japanese, Kannada, Korean, Malayalam, Marathi, Odia, Punjabi, Russian, Sanskrit, Tamil, Telugu, Thai, Chinese)
> 6 Tasks (OCR, Layout Detection, Layout-aware Translation, Document VQA, Cross-lingual Retrieval, Document VLM Pretraining)
ps: this is the 2025 corpus. 2026 is ~5× bigger (~4.4M images, sharper renders, cleaner annotations) reach out to @cognitivelab_ai or [email protected] for more info

Launching NayanaOCR Corpus
👉🏼 1M+ Document images across 22 languages
Largest open source synthetic
> multilingual
> multimodal
> multitask
document corpus
Like the dataset if you find it helpful !!
huggingface.co/datasets/Cogn…

Today we are excited to launch NetraEmbed
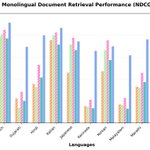
SoTA multimodal multilingual document retrieval model.
> Supports 22 languages
> ~ 150% improvement over existing baselines
> NayanaIR-Bench a open source multilingual document retrieval benchmark

Also excited to release "M3DR: Towards Universal Multilingual Multimodal Document Retrieval" paper preprint that cover the framework we used to train these models

Read more :
cognitivelab.in/blog/introdu…
We thank @modal for sponsoring compute for this research.

CognitiveLab retweeted
Happy to share got a paper accepted at a neurips workshop
This paper mainly tackles long context reasoning for multimodal models(vlms) with key focus citations and reasoning based re ranking got some good results with sft + rl(grpo) will put it on arxiv soon!

🚀 Thrilled to announce CognitiveLab wins the six-figure Llama Impact Grant by @Meta !
🇮🇳 As India's only recipient, we're powering Nayana a multimodal, multilingual multi task AI model family! #AI #MultilingualAI #Innovation

Nayana’s Mission: Democratize AI for education, healthcare, governance, & cultural preservation across languages & modalities.
Official Announcement :
about.fb.com/news/2025/04/ll…


🚨 Introducing Gaja 🚨 ~ (Llama3-Gaja)
A series of open source bilingual Hindi-English LLMs finetuned on top of Llama3-8b by @AIatMeta
huggingface.co/Cognitive-Lab…

ALT https://huggingface.co/Cognitive-Lab/LLama3-Gaja-Hindi-8B-v0.1
Our first attempt at fine-tuning LLama3 for Indic languages.
we choose Hindi as LLama3 was efficient at tokenising it
Many more experiments/iterations are in progress
👉🏼 Finetune for multi turn chat conversation
👉🏼 Performers decent in cross lingual tasks
👉🏼 Will soon put out the evals on Indic LLM leader board
huggingface.co/spaces/Cognit…

CognitiveLab retweeted
evaluated LLama3 using indic_eval (github.com/adithya-s-k/indic…)
on English, Hindi and Kannada
results are there on the Indic LLM Leader board
huggingface.co/spaces/Cognit…
👉🏼 It performs significantly better than LLama2 in most of the benchmarks.
👉🏼 In comparison to Gemma, it falls a little short.
👉🏼 Tokenization for Devanagari is efficient when compared to LLama2.
(both indic_eval and indic llm leaderboard are in alpha testing we are activlty developing to make it more reliable)


It's going to be hard to adapt Llama3 for Indic languages, in my opinion.
Here are a few reasons why:
👉🏼 The tokenizer used is TikToken-based, which is not really efficient in tokenizing Indic text despite having a vocabular size of 121k.
👉🏼 unlike sentence-piece based models, it might be difficult to perform vocabulary expansion.
I ran some quick tokenization on Devanagari and Kannada. It performed better than Llama 2 with Devanagari.
But with other Indic languages like Kannada and Tamil,etc it does not tokenize efficiently.
Here are some quick comparison screenshots.
I will have to do some more testing to see its base level peformace
will try to soon add it to the Indic LLM leaderboard
huggingface.co/spaces/Cognit…


Features include:
👉🏼 Support for 7 Indic languages.
👉🏼 Open source, hosted on Hugging Face.
👉🏼 Support for 4 Indic benchmarks, with more to be added.
👉🏼 Seamless integration with indic_eval
This is the alpha release and we will be adding a lot more tested features soon
The heart of the Leaderboard is
indic_eval - github.com/adithya-s-k/indic… is an evaluation library that integrates seamlessly with the indic LLM leaderboard.