

senior software engineer
São Paulo, Brasil
Joined June 2018
- Tweets7K
- Following398
- Followers2K
- Likes29.8K





o GUGO tá de volta

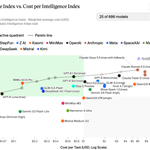
Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index
Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas.
As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon.
Key results for Gemini 4 Carbon with high reasoning:
➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work
➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude Opus 5.5 (max, 62) on the Artificial Analysis Coding Agent Index. Carbon ranks second on both Terminal-Bench 4.0 (64%) and FrontierCode v1.1 (51%), behind Claude Opus 5.5 (max) at 56%. Google has historically underperformed in this area and so this improvement stands out
➤ Improved agentic knowledge work, but not yet leading: On AA-Briefcase, Gemini 4 Carbon (high) scores 1609 Elo, a 126-point improvement over Gemini 4 Argon (high, 1483), but still behind models including Grok 4.7 (xhigh, 1638), Muse Wonder (max, 1659) and Kimi K3.1 Pro (1678). The largest gain comes from Presentation, up 293 Elo to 1598, alongside a 120-point improvement in Analytical Quality to 1671
➤ Lower Cost per Task than Claude Opus 5.5 for comparable overall intelligence: Gemini 4 Carbon costs $7.76 per Intelligence Index task, ~23% less than Claude Opus 5.5 (max, $10.04) but ~1.2x GPT-6 Astra (max, $6.25). It uses 123k output tokens per task, 29% fewer than Claude Opus 5.5 (max, 173k). At the same $4/$20 standard pricing, its Cost per Task is in line with Gemini 4 Argon ($7.68), while scoring 9 points higher on the Intelligence Index
➤ Leading AA-Omniscience v1.1 score, with low hallucination: Gemini 4 Carbon scores 54 on our recently updated AA-Omniscience v1.1, 6 points ahead of Claude Opus 5.5 (max, 48) and 8 points ahead of Gemini 4 Argon (46). Accuracy (% correct) rises 10 points over Argon to 58%, while its hallucination rate rises from 4% to 11%. This is still the second lowest of any model, behind only Argon, compared with 50% for both Claude Opus 5.5 (max) and GPT-6 Astra (max)
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $4/$20 per 1M input/output tokens, the same as Gemini 4 Argon’s standard pricing, with a 50% discount. Cached input tokens receive a 95% discount ($0.20 per 1M)
Congratulations to the @GoogleDeepMind team!

Vinicius Fonseca retweeted

Talvez isso traga um pouco de racionalidade a sua vida:
Nenhum político irá te salvar
Todos eles podem te ferrar, e muito!
Mas nenhum deles irá te salvar
Não sofra por isso
Foque em você, na sua família e no que está ao seu alcance
Repito, eles não irão te salvar

O que resolve criminalidade é bandido na cadeia.
O bandido não comete crimes por causa de condições socioeconômicas, comete crimes porque a justiça desse país atua a favor dos criminosos. Bandido tem que ter medo das consequências dos seus atos!


Vinicius Fonseca retweeted

Today we're releasing Underdog Saluki 27B
Based on Qwen 3.8 27B, Saluki is almost 7x smaller than its full-precision counterpart while it keeps 96% of its benchmark performance and beats Qwen at tool calling
It's the best model <8GB that runs in Underdog
Saluki is available today under Apache 2.0. Try today in Underdog underdog.ai/saluki

o chicote mudou de lado

TSE manda retirar publicações de Lula, Janja e aliados contra Flávio Bolsonaro glo.bo/3W0CJnf #g1 #eleição2026

a melhor coisa a se fazer em época de eleição é larpar de isentão quando você está cercado de normies
galera, usem o que vocês acharem mais confortável. um monte de gente acha isso uma atrocidade, mas vai fazer 6 anos que eu uso VSCode pra programar em java. sim, eu acho melhor que intellij, e até agora pagou as minhas contas, isso que importa.

Depois de 4 anos enfiando imposto no rabo no povo, amanhã o Haddad vai sofrer mais uma derrota humilhante nas urnas.
a briga agora não é nem mais flávio x lula
é globo x judiciário, o sistema tá mordendo o próprio rabo
Vinicius Fonseca retweeted

This week Claude Sonnet 5.5, GPT-6.1 Sol and Gemini 4 Argon all launched near the top of the Coding Agent Index leaderboard, but each has a different balance of performance and cost
The Artificial Analysis Coding Agent Index measures agents (a combination of model and harness) across three agentic coding evaluations.
➤ Claude Sonnet 5.5 (max) in Claude Code takes the top spot at 68, but also has the highest measured cost per task: $14.19
➤ Gemini 4 Argon (high) in Antigravity CLI scores 64 at $5.84 per task - less than half of Sonnet 5.5’s cost. Note, this uses Google’s promotional pricing, and Argon is not yet publicly available
➤ GPT-6.1 Sol (xhigh) in Codex scores 63 at $1.04, roughly one sixth of Argon’s cost


Vinicius Fonseca retweeted

"Christ is King" - Grok (paraphrase)

