

Infinite Inference. No Latency.
Santa Clara, CA
Joined February 2022
- Tweets337
- Following181
- Followers1.5K
- Likes345




Inference needs a different approach to compute.
On The Startup Project, d-Matrix CEO @sidsheth discusses memory-centric compute, low-latency inference, heterogeneous infrastructure, and the path from first silicon to rack-scale systems.
Listen here: thestartupproject.io/episode…
#AIInference #dMatrix

AI inference is becoming the new scaling challenge.
SquadRack is our reference blueprint for a rack-scale solution purpose-built for AI inference, using a disaggregated, standards-based approach designed to deploy in existing data centers.
Read more: d-matrix.ai/scaling-ai-the-r…
#AIInference #dMatrix

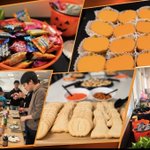
A little Halloween fun with the d-Matrix team. Great minds, creative spirits, and plenty of candy.
Happy Halloween! 👻
#LifeAtdMatrix #Halloween

AI infrastructure needs to evolve to keep pace with inference demands.
d-Matrix CEO @sidsheth joined @furrier and @NYSEWired & theCUBE during the CASPA CEO Summit for a discussion about accelerating AI inference through memory, scaling inference from cloud to the edge, and much more.
Watch the full conversation: youtube.com/watch?v=jnzS9al0…
#AIInference #Semiconductors #CASPA2026 #dMatrix

Proud to celebrate d-Matrix CEO @sidsheth as a recipient of Purdue University’s 2026 Outstanding Electrical and Computer Engineer Award.
Congratulations to Sid and all of this year’s honorees, and thank you to the @PurdueECE community for the recognition.
#PurdueECE #Semiconductors #AIInfrastructure #dMatrix


Building the future of AI starts with a strong innovation ecosystem.
d-Matrix India’s Pradip Thaker shares his perspective with Outlook India on semiconductors, AI, entrepreneurship, and the importance of local IP and deep-tech talent.
Read more: outlookindia.com/announcemen…
#Semiconductors #AI #dMatrix

A great few days at the CASPA 35th Annual Conference & CEO Summit.
d-Matrix CEO @sidsheth Sheth joined @KrishnaR_SiMa of @SiMa_Inc and Melton Chang of @SchneiderElec , moderated by @Srasgon of Bernstein, for a conversation on how the infrastructure stack is evolving for the next generation of AI.
Thank you to the @CASPAorg team, and congratulations on an incredible 35 years!
#CASPA2026 #AIInference #Semiconductors #dMatrix


From specialized processors to complete AI inference systems. d-Matrix is scaling up with Squadron™, a new Silicon Valley lab and a growing team.
Silicon Valley Business Journal explores what’s next: bizjournals.com/sanjose/news…
#AIInference

Tomorrow at #PyTorchCon, join d-Matrix Principal Engineer Tristan Webb for a Demo Theater session on how PyTorch can help accelerate kernel development for custom AI hardware.
dmx-compressor: Accelerating the Development of Kernels for Custom ASIC Hardware
🕧 Wednesday, October 21 | 12:35 PM
📍 Community Expo, Concourse Level
#PyTorchCon #AIInfrastructure #AIInference #dMatrix
Breaking through the memory wall. Rethinking AI inference.
d-Matrix CEO @sidsheth joins Tae Kim (@firstadopter) to discuss memory-centric compute, 3D-stacked DRAM, and the future of low-latency AI inference.
Read the interview: taekim.substack.com/p/an-int…
#AIInference #AIInfrastructure
Next week, d-Matrix is heading to #PyTorchCon in San Jose.
Stop by the d-Matrix booth to meet the team and join d-Matrix Principal Engineer Tristan Webb for his session.
“Accelerating the Development of Kernels for Custom ASIC Hardware”
🕧 Wednesday, October 21 | 12:35 PM
📍 Community Expo, San Jose Convention Center
#AIInference #AIInfrastructure #PyTorch #dMatrix
800+ tokens/sec per user. Heterogeneous inference in action.
At #OCP2026, d-Matrix demonstrated live attention/FFN disaggregation across NVIDIA H100 GPUs and memory-centric Corsair™ nodes.
Watch the demo:
nextgeninfra.io/2026-ocp-glo…

Join d-Matrix's Senior Principal AI Systems Architect Sai Rahul Chalamalasetti at #OCPSummit26 today for a session on scaling communication across increasingly complex AI systems.
One Abstraction, Many Transports: Push-Mode Communication from Chiplet to Rack
🕐 1:15pm
📍 SJCC — Concourse Level, Expo Hall Theater
#AIInfrastructure #OCP2026 #dMatrix
845 tokens/sec per user. ~50% lower latency.
d-Matrix Corsair + NVIDIA H100 are redefining AI inference with attention-FFN disaggregation.
Faster inference. Smarter compute.
Read more: d-matrix.ai/accelerating-ai-…
Meet d-Matrix Squadron. AI inference at data center scale.
Up to 1,024 Corsair XPUs. Ultra-low latency. Air-cooled, megawatt-scale compute.
Built for the next era of AI inference.
Explore Squadron: d-matrix.ai/announcements/sq…
#OCP2026 #AIInference
Big ideas. Bold conversations. NYC energy. ⚡
We're teaming up with @parasail_io and @youdotcom for the AI Engineer New York Speaker VIP Happy Hour!
AI innovators, great connections, and conversations shaping what's next.
See you in NYC! 🚀 luma.com/6dobkzfh
#AIEngineer #AIInference #dMatrix

Next week, we’re heading to #OCPSummit26!
Don’t miss d-Matrix:
Oct 12, 12 PM — Sid Sheth
Oct 14, 1:15 PM — Sai Chalamalasetti
📍 Visit us at Booth C82!
Two sessions. One mission: Infinite Inference.
opencompute.org/events/ocp-s…

AI infrastructure is evolving — and it takes an ecosystem to move it forward.
Great to see @AristaNetworks’ latest announcement on open Ethernet rack-scale infrastructure for AI.
As CEO Sid Sheth said: “Delivering interactive AI at scale is a complex tech challenge requiring collaboration across the ecosystem.”
Open standards. More choice. Built for what’s next.
arista.com/en/company/news/p…
#AIInference #dMatrix #AIInfrastructure

We’ve been named one of @FastCompany’s 2026 Next Big Things in Tech in the Foundational AI category.
Our Corsair™ AI inference platform and memory-centric architecture are redefining AI inference — delivering up to 10x faster interactive inference and up to 3x better energy efficiency for LLM workloads, without relying on scarce HBM.
Proud of the d-Matrix team.
Read more: fastcompany.com/next-big-thi…
#FCTechAwards #AIInference #dMatrix
